What is SAM 3 / 3.1?
SAM 3 is a new model in Meta's Segment Anything Model series.
Earlier SAM models only knew the shapes of things, so to cut out a specific object, you had to point to its location with a BBOX or coordinates.
With SAM 3, you can name the target in text, like with a VLM, and it handles the segmentation entirely on its own.
SAM 3.1 is an updated version of SAM 3. It improves tracking of multiple objects in video.
Model Download
- sam3.1_multiplex_fp16.safetensors (1.75 GB)
📂ComfyUI/
└── 📂models/
    └── 📂checkpoints/
        └── sam3.1_multiplex_fp16.safetensors
workflow
Still Image
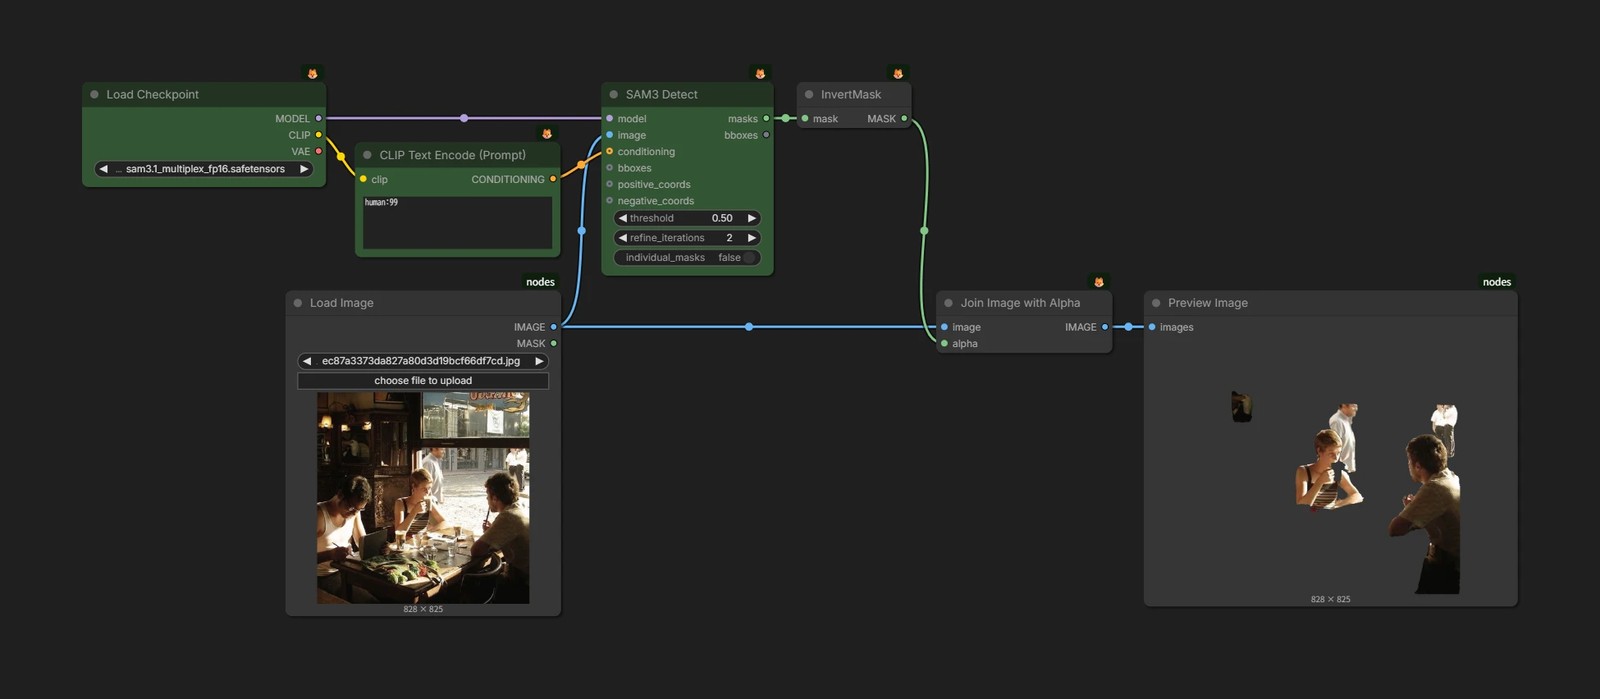
- Input the image, mask, and target information (text prompt, BBOX, coordinates) into the
SAM3 Detectnode. - This part is a little confusing: if several objects match the prompt, just writing
cardetects only the most likely one.- If you want to segment up to the N-th item, write it like
car:N. - If you just want everything on screen that matches, you can simply write something like
car:99.
- If you want to segment up to the N-th item, write it like
Video
- Use the
SAM3 Video Tracknode. - Pass the output to the
SAM3 Track to Masknode to use it as a mask. - The
SAM3 Track Previewnode takes an image andtrack_data, then colors the masked area so it is easier to see.