What is Instruction-Based Image Editing?
On this site, instruction-based image editing models means models that take an image plus text instructions (and reference images if needed) and edit the image according to those instructions.
Previously, you needed a different technique or workflow for each task:
- Style Transfer → LoRA or IP-Adapter
- Object Removal/Replacement → Inpainting
- Virtual Try-On → Dedicated Models
Instruction-based image editing models move toward "handling all of these with text instructions." nano banana, the current SOTA, falls into this category too.
History of Development
Let's get a rough picture of how instruction-based image editing developed.
InstructPix2Pix — The Starting Point of Editing by Instruction
InstructPix2Pix, released in 2023, opened the door to "instruction-based image editing."

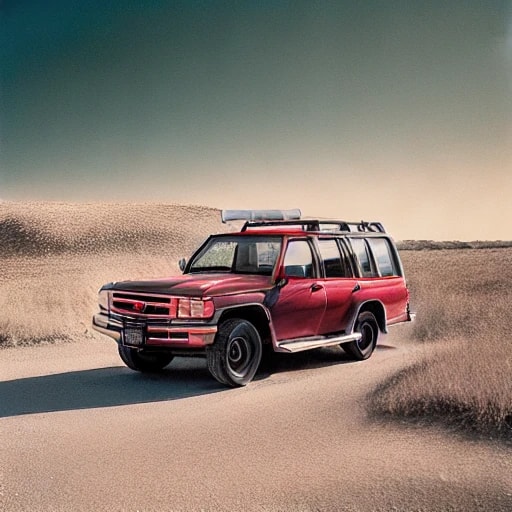
Turn the car red
It was trained on pairs of images and text instructions for editing them, with the goal of editing images according to whatever the user writes.
DiT and In-Context Approaches
It was only discovered later, but DiT models like Flux already had the ability to create images that stay consistent across multiple pictures.
IC-LoRA / ACE++ are frameworks that apply this property to editing.
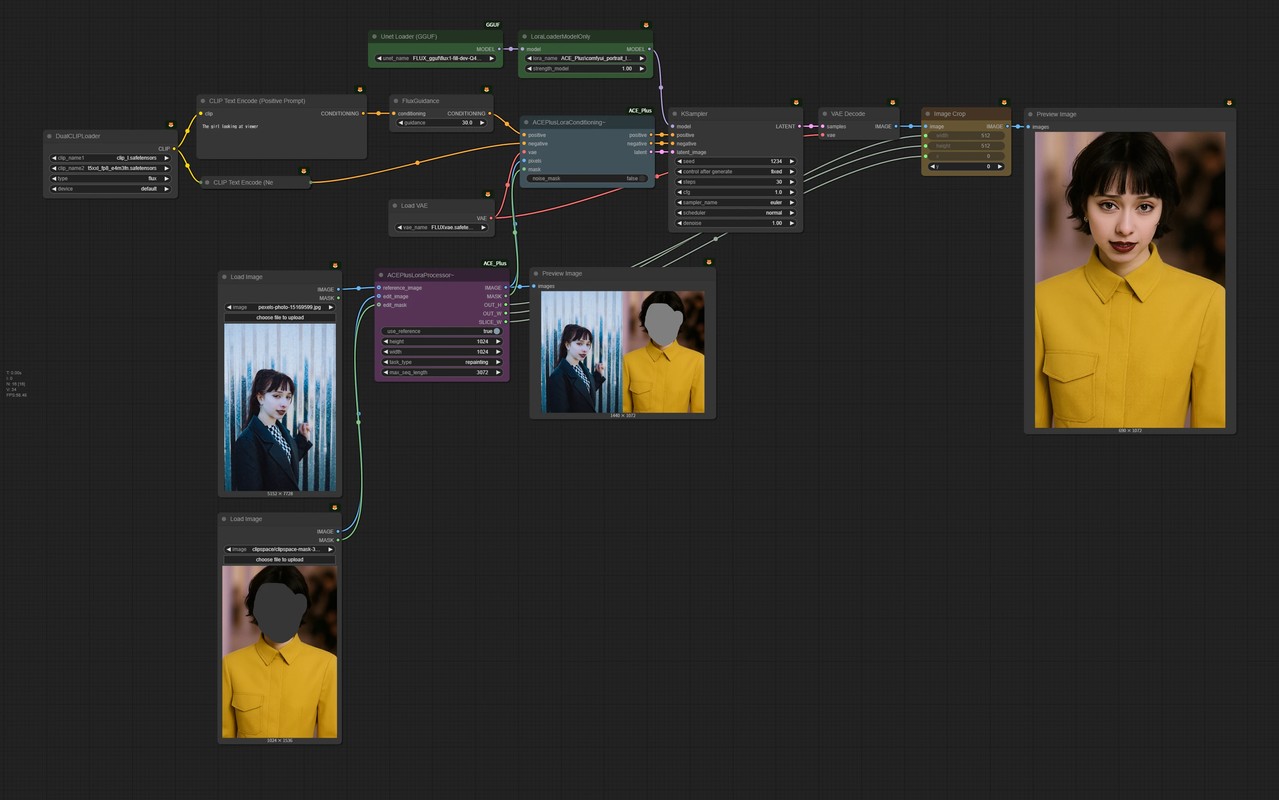
- Place a "reference image" on the left side of the image canvas.
- Mask the right side and have the model generate it.
- Add text instructions so it "edits the right side while looking at the left."
This so-called side-by-side technique showed that you could "edit while keeping the features of the reference image" without any special adapter.
Emergence of Image Editing Models
After that, dedicated image editing models derived from text2image models appeared, such as FLUX.1 Kontext, Qwen-Image-Edit, and OmniGen, and "image editing" started to be treated as its own category, separate from text2image.
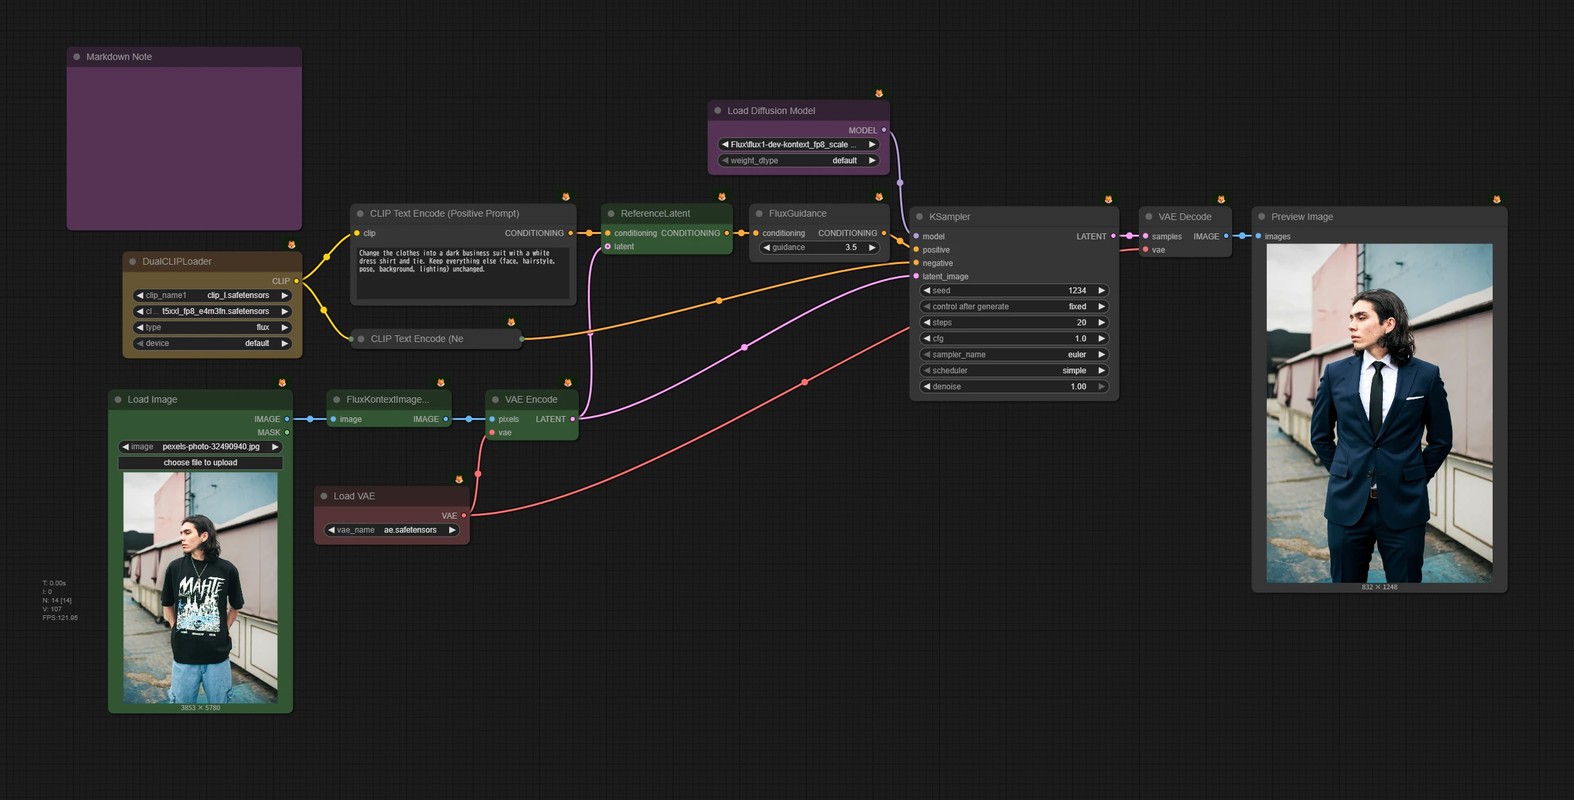
What they share is the aim of handling editing tasks (understanding the input image and deciding "what to change, and how much" based on the text instructions) in a single, (fairly) general-purpose model.
The Multi-Reference Era
Early instruction-based image editing assumed one input image: "1 image" + "text instruction" → edited result.
Starting with Qwen-Image-Edit-2509 and Flux.2, handling multiple reference images at once has become the clear trend.
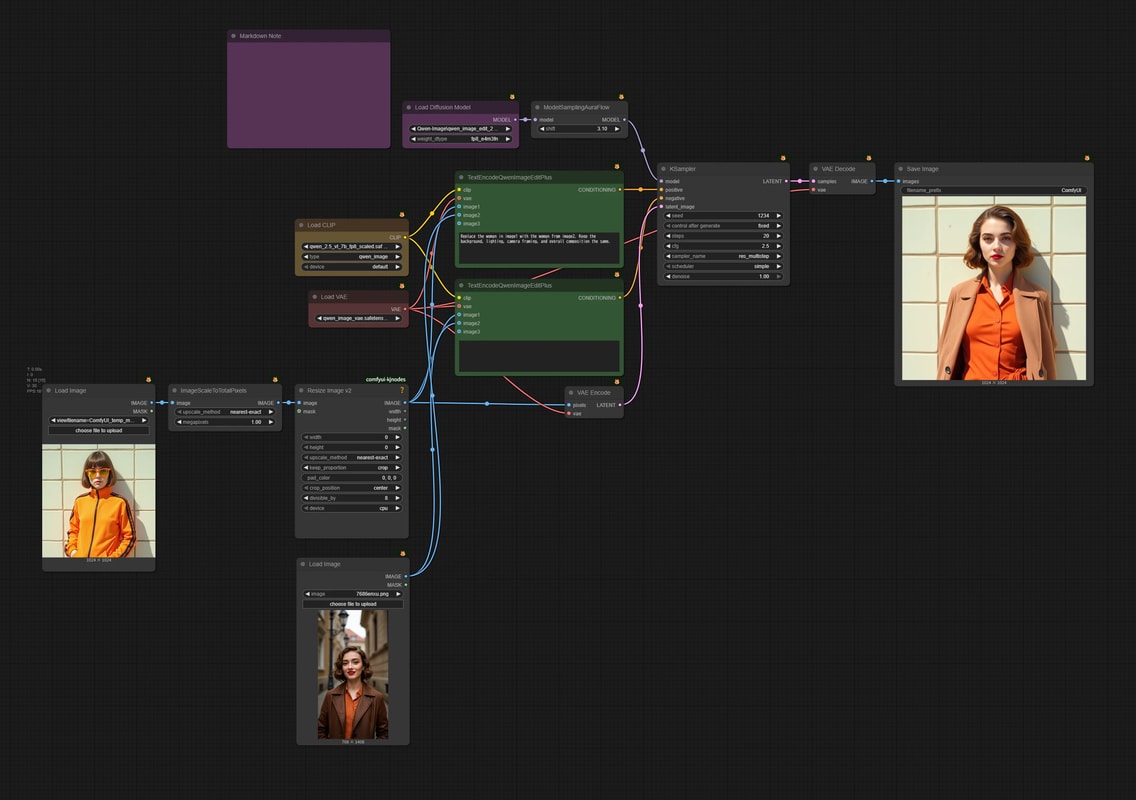
- Image A: Person (Subject)
- Image B: Clothes (For Try-On)
- Image C: Background or Style
You can now edit while "mixing" several references like this, so tasks such as subject transfer, ID transfer, virtual try-on, and style or lighting transfer are starting to overlap heavily with instruction-based editing.
Video Model-Based Editing
Another line of work repurposes video generation models for editing. FramePack's 1-frame inference and ChronoEdit are the main examples.
The idea: video models are built to keep multiple frames consistent, so if you treat the before and after images as a "short video," even big changes can be bridged naturally.
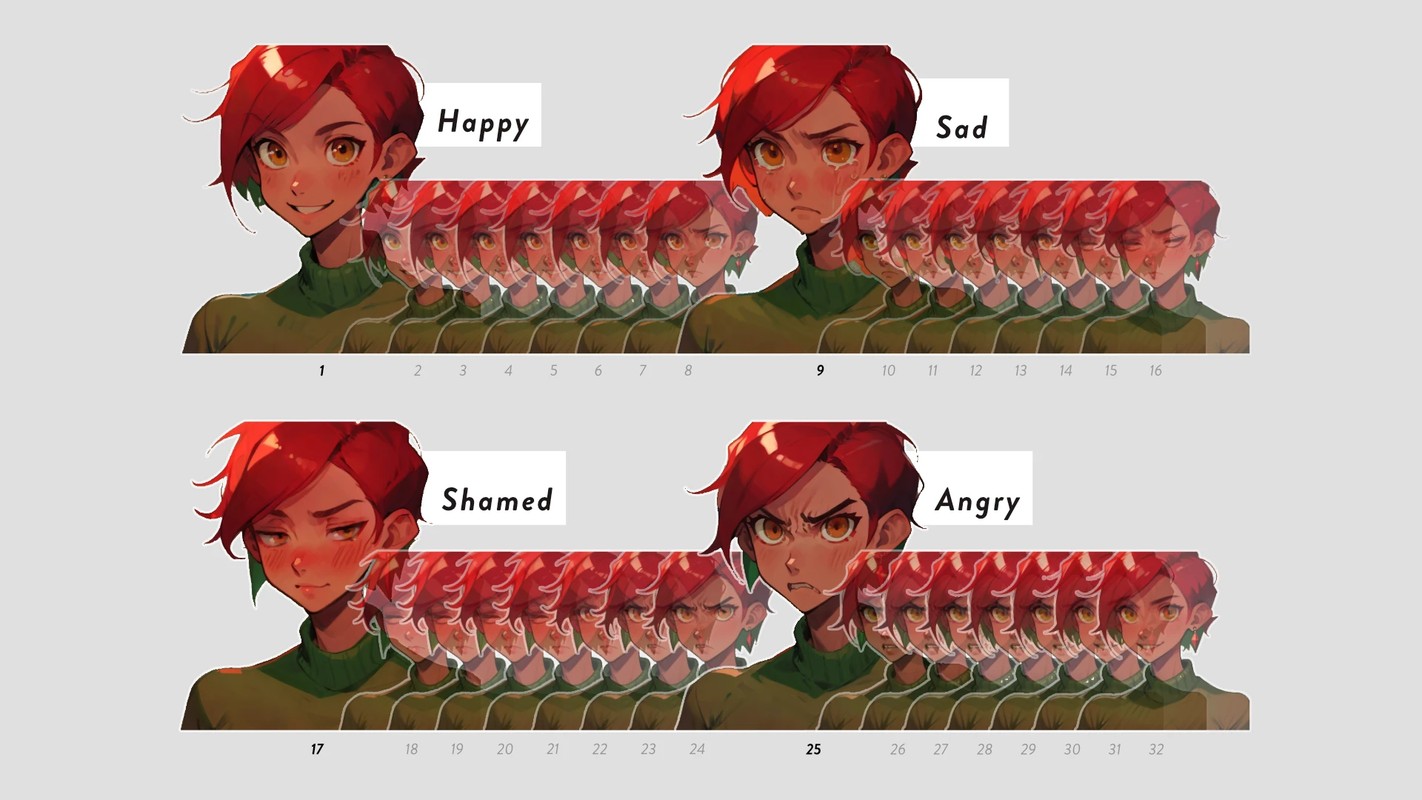
The idea itself is old. Back when AnimateDiff was the main thing, I used to make animations of a character pulling different expressions and use them as character variations.
There are still plenty of problems: the consistency can be so strong that big changes are hard, and it outputs dozens of video frames when an edit only needs one image. Still, I think it's a technology worth watching.
What Instruction-Based Image Editing Can Do
Instruction-based image editing models can handle a lot of tasks. This site covers them in detail on their own pages, so here I'll just run through the names.
Style Transfer
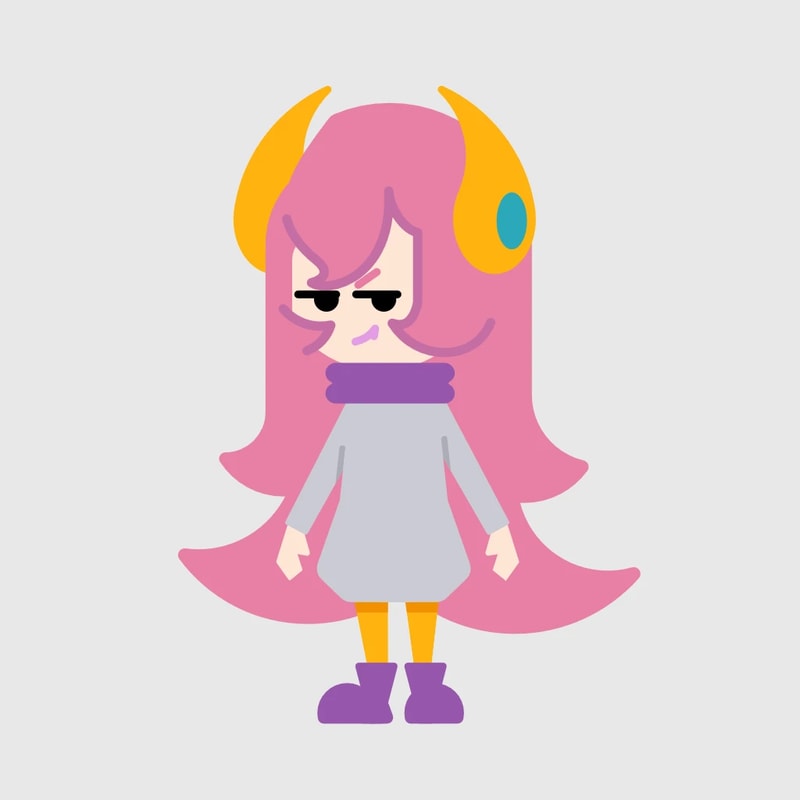
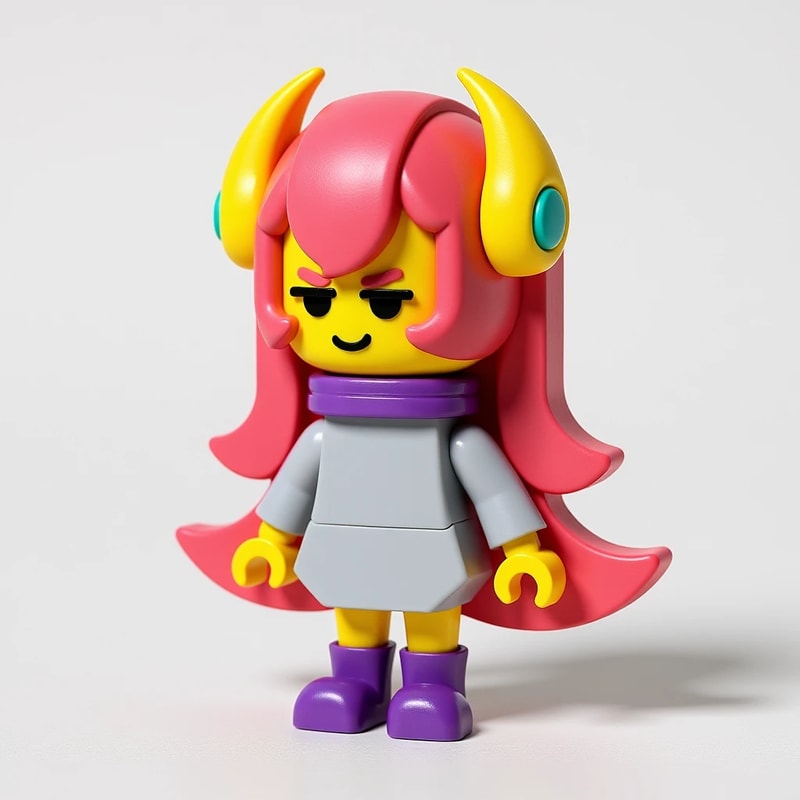
Changes the art style or feel, like "make it an oil painting" or "make it anime style."
Object Replacement
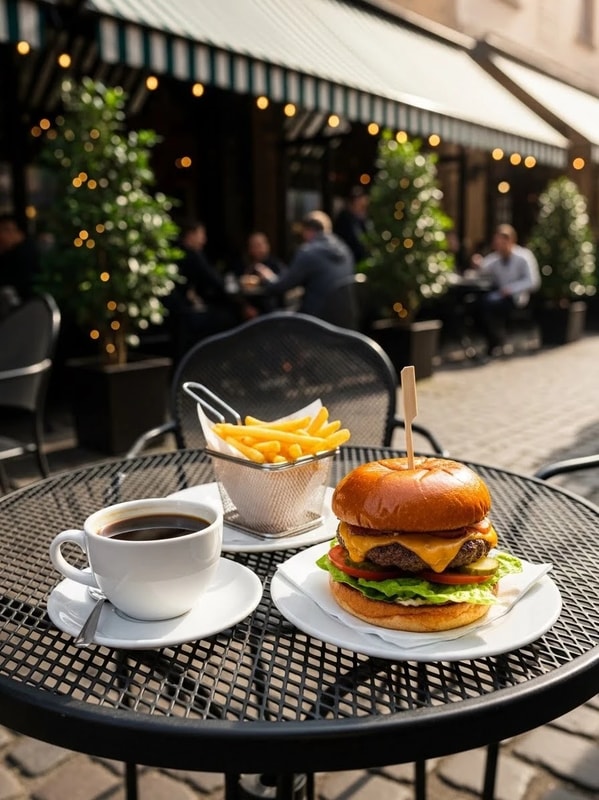
Swaps things out, like "turn this cup into a mug" or "turn the car into a motorcycle."
Object Removal
Removes unwanted things like passersby, signs, and trash.
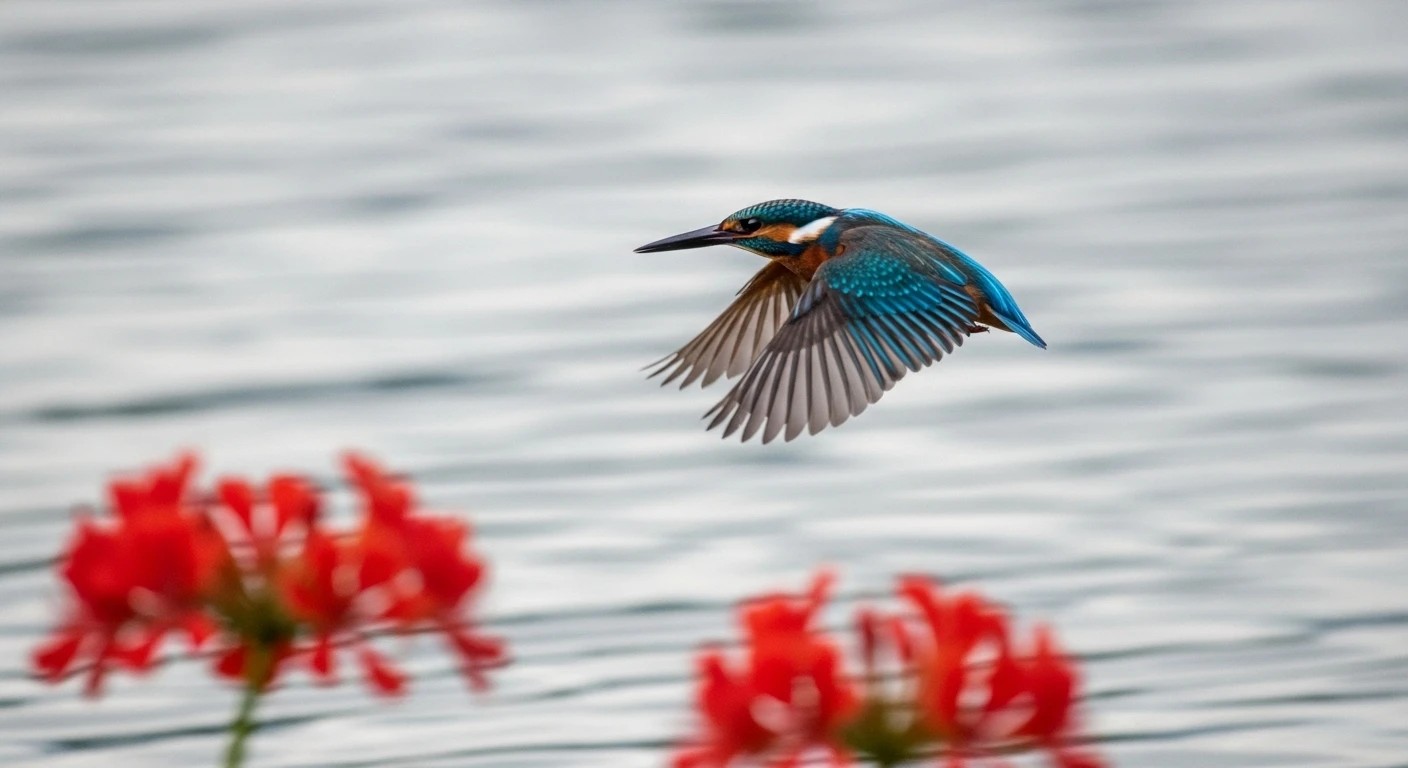
Background Change
Changes only the background, such as indoors → beach or day → night.
Text Editing
Changes the text on signs or packaging, swaps out typography, and so on.
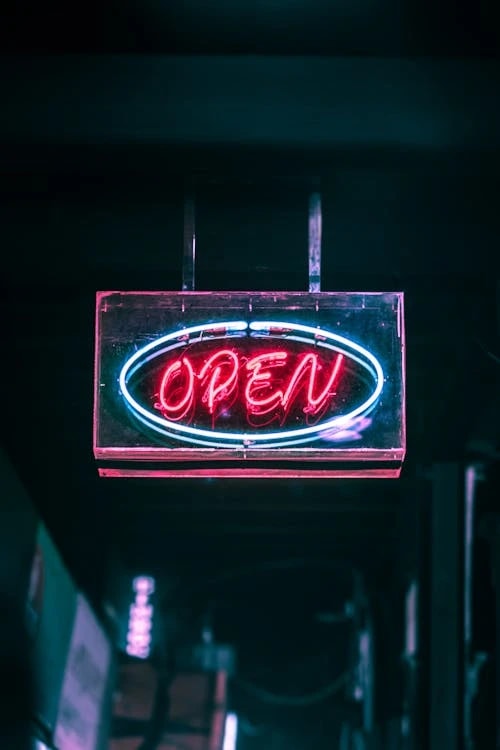
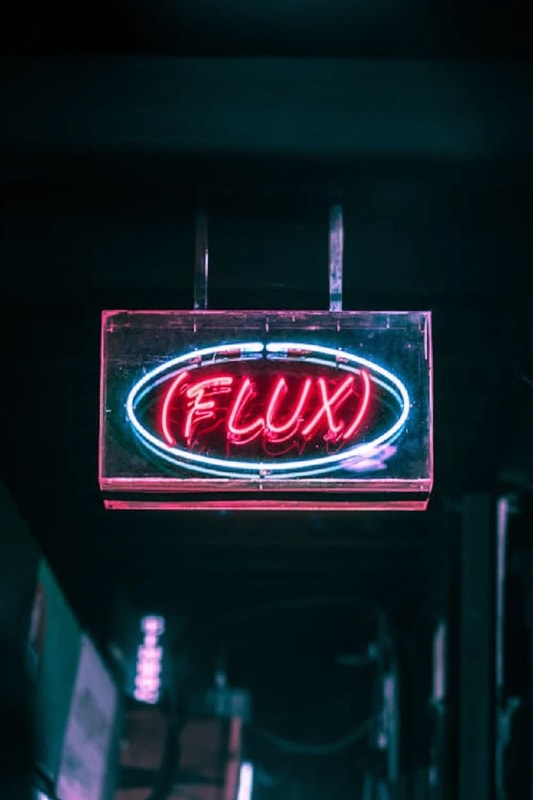
Camera Angle Change
Composition-type changes like "pull back a little," "from a low angle," or "seen from the side."
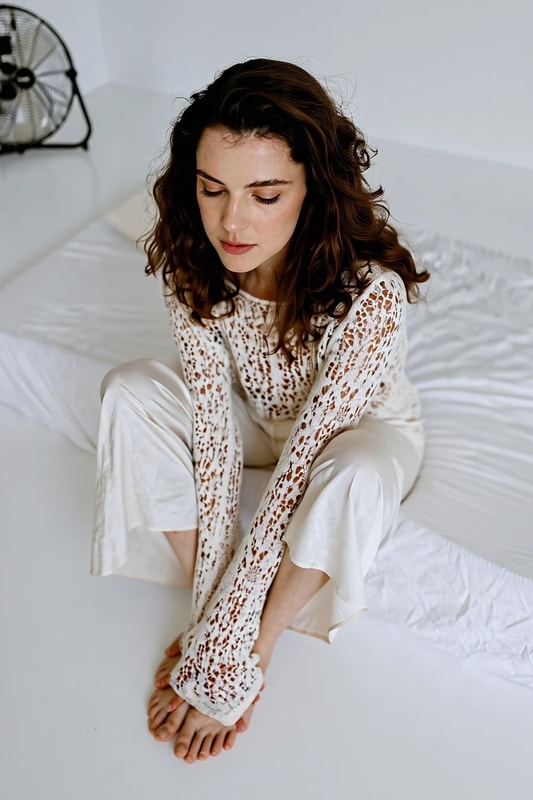
Virtual Try-On
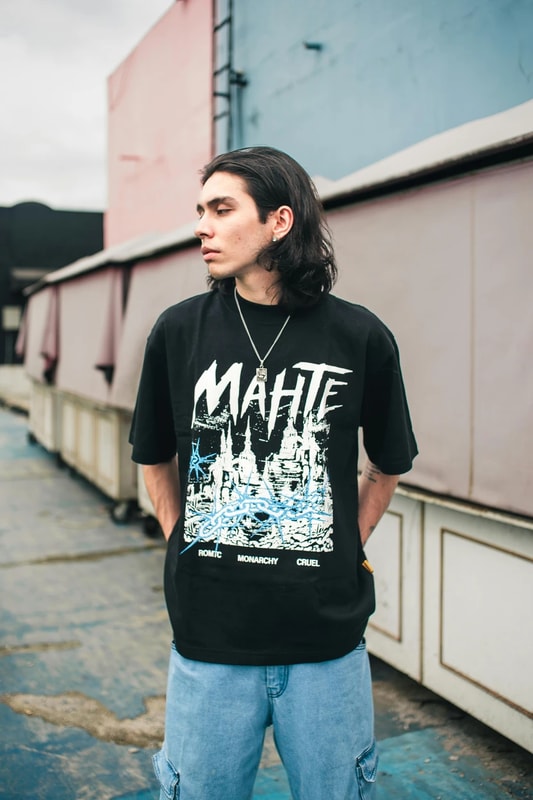
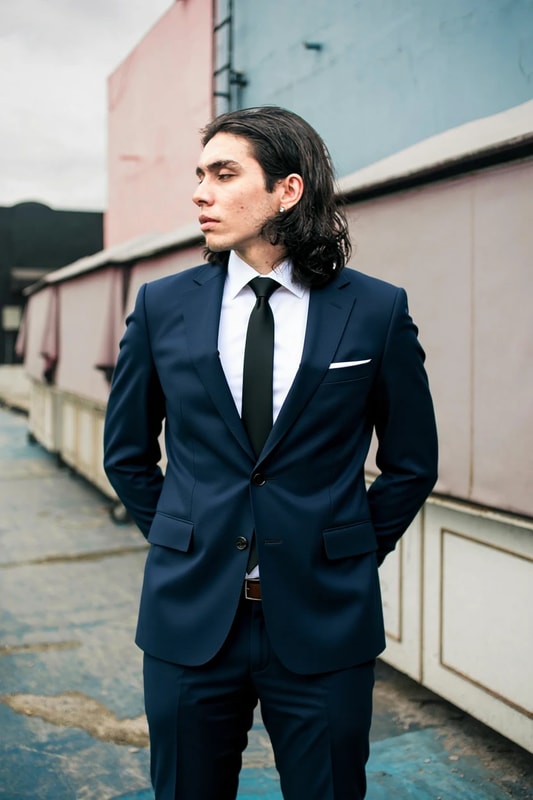
Changes what a person or character is wearing.
ControlNet-like Generation
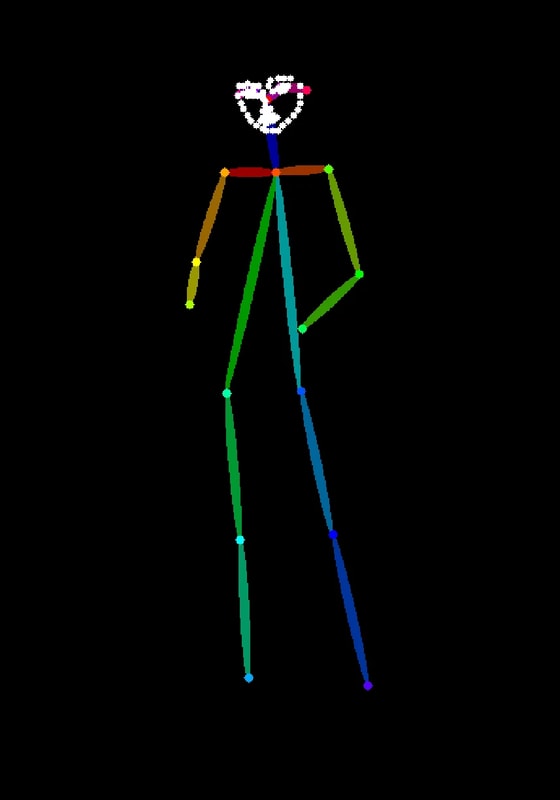
ControlNet generates images from a condition like a stick figure or depth map plus text, which you can think of as a kind of "instruction-based image editing." Today's instruction-based image editing models are trained to handle basic ControlNet-style generation.
Refining Rough Collages
You make a rough collage and have the model "edit" it so it looks natural.
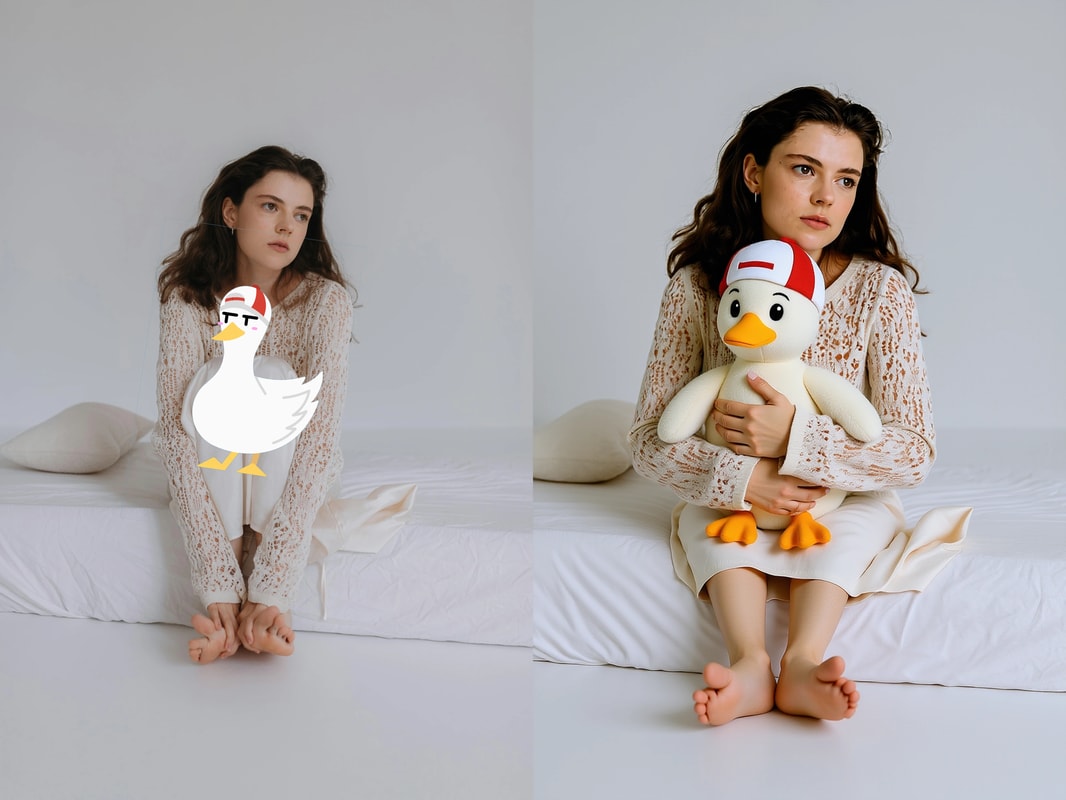
- Paste in objects, choosing their position and size yourself.
- Then tell it "make it a natural photo" or "make it look like one seamless picture."
This way, you can combine intuitive layout control with instruction-based editing. Details are covered on the "Refining Rough Collages" page.
Scribble Instructions
You give instructions by combining rough marks with text, like "turn the face toward the arrow too" or "put a bus where the red circle is."
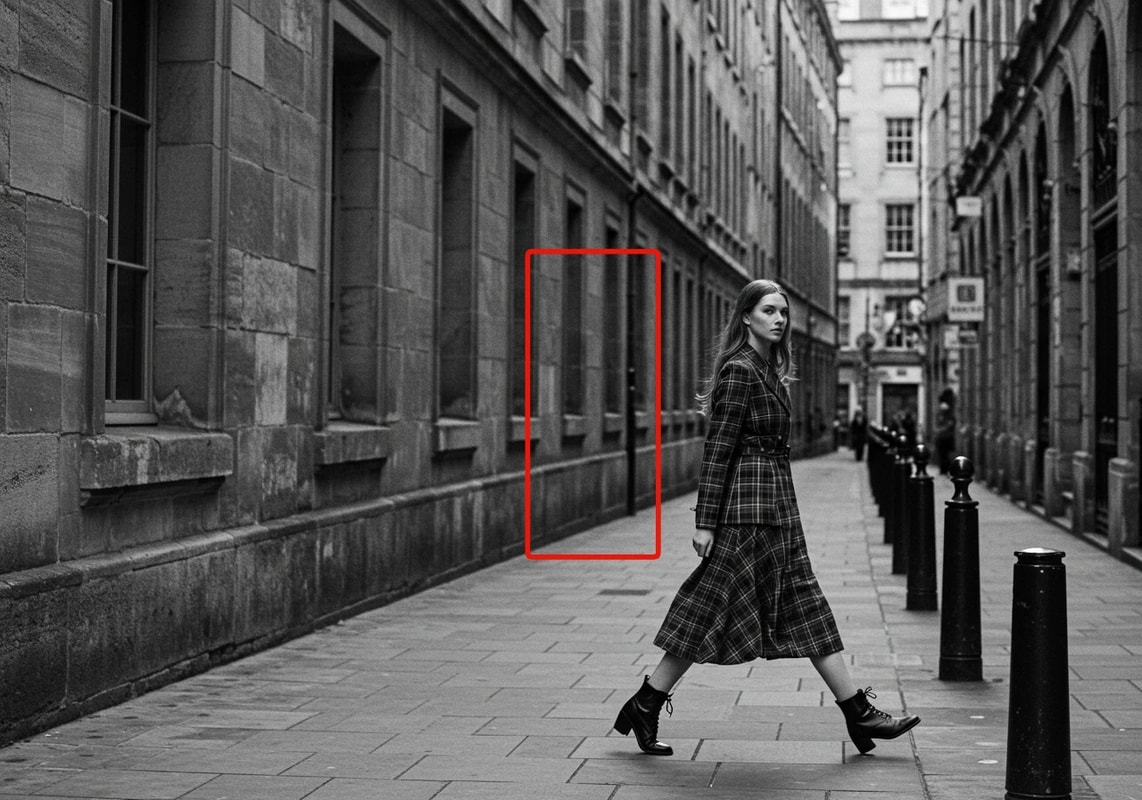
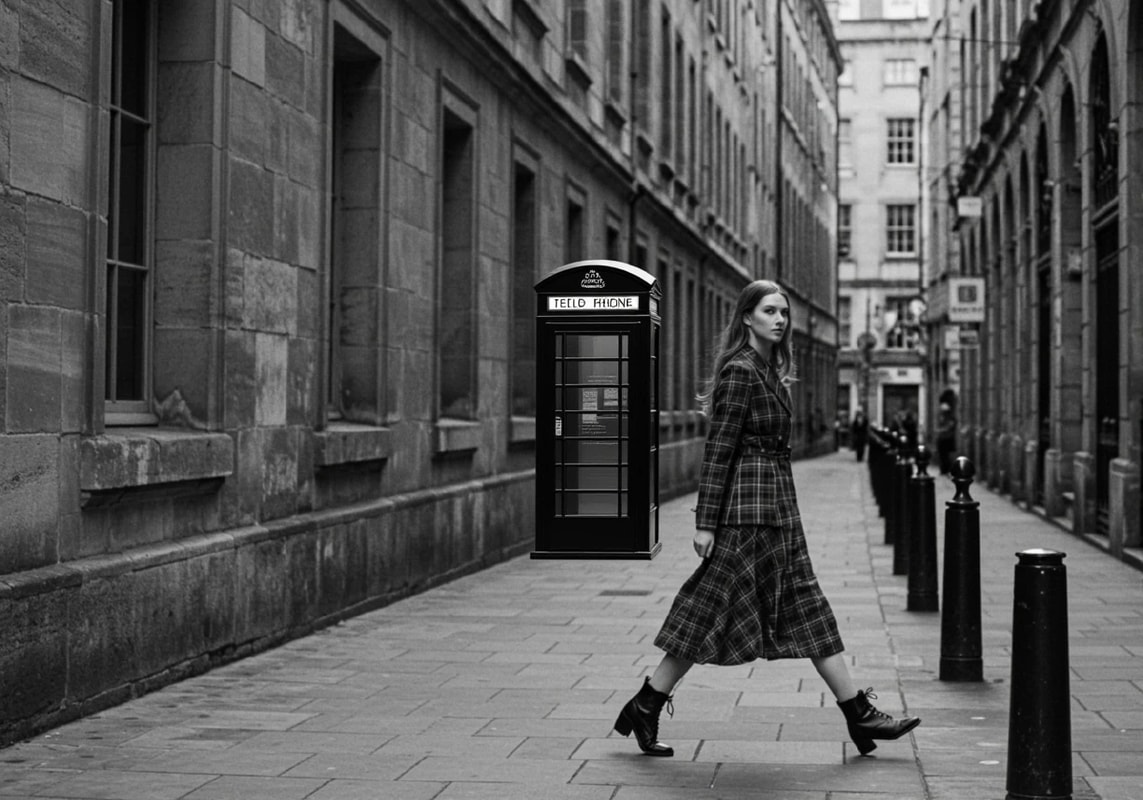
The weak point of instruction-based image editing is that text alone makes it hard to convey exact positions or how much to change. Ideally, we'd be able to "give instructions with a pen" to AI, the way a producer marks up a draft for a designer.
Not many open-source models can do this well yet, but once it works, it'll be the ideal UI/UX for working together with AI.
Easy to Create LoRAs
Thanks to the community building out training tools, making editing LoRAs is relatively easy.
For a LoRA that converts images into your own illustration style, about 10 before/after image pairs will get you a LoRA of decent quality.
"Refining rough collages" is a perfect example: what counts as "image editing" is actually a very open question. There may be groundbreaking kinds of edits nobody has found yet. Give it a try!