What is Prompt Generation & Editing?
Back when the prompt was the only parameter we could really play with, terms like "prompt engineering" and "spells" were all the rage (good times).
Compared to today's natural-language prompts, prompts for Stable Diffusion 1.5 were incantations made of strings of tags. The models didn't understand much, so you had to tweak prompts by trial and error while watching the output.
But writing these by hand every time is a chore, and it inevitably turns into a specialist craft. Handing that job off to an LLM is what this page calls "prompt generation & editing."
Prompt Generation in the Stable Diffusion Era
Stable Diffusion / SDXL-era models didn't understand natural language well, so the standard style was a string of comma-separated tags.
masterpiece, (best quality:1.05), 1girl, blue hair, …
People came up with tricks like stacking words with similar meanings or matching the quirks of the text the model was trained on... but building that "AI-flavored writing" by hand every time is a pain.
So dedicated models appeared that "turn a roughly written prompt into a Stable Diffusion-style tag list."
Representative Examples
-
- A lightweight model that generates Danbooru tag lists. Give it a few rough tags or a description, and it expands them into a dense tag list that suits Stable Diffusion.
-
Qwen 1.8B Stable Diffusion Prompt
- A small Qwen-based model specialized for generating SD prompts (e.g., Japanese → English tag lists).
Neither cares whether the result is readable for humans. Both are tools built purely to spit out prompts in a format SD1.5 / SDXL handles well.
Recent Models and Prompts
DiT models like FLUX and recent image editing models now use LLM-based text encoders such as T5 and Qwen.
As a result, they understand natural language far better than Stable Diffusion-era models did, and "spell"-style prompt tricks are mostly unnecessary now.
That doesn't mean you can "write something sloppy and reliably get good results," though.
It's the same with people. You could say a good director's job is to explain things like these concisely:
- Quantitative details such as distance, angle of view, focal length, time of day, and how many of something
- Specifics for each element, such as background, composition, lighting, style, and facial expression
Still, writing all that by hand every time is a pain, so we use an LLM like ChatGPT. Even loose requests like "flesh out this Japanese prompt for FLUX.2," "add composition, lighting, and camera details and clean it up," or "format this prompt for Qwen-Image" are enough to make the prompt much richer.
Some image generation models come with their own dedicated LLM, but it doesn't make a huge difference. The image generation model's own capability matters far more.
Using It in ComfyUI
There are several LLMs you can run locally in ComfyUI, but also consider calling Gemini or ChatGPT through API nodes.
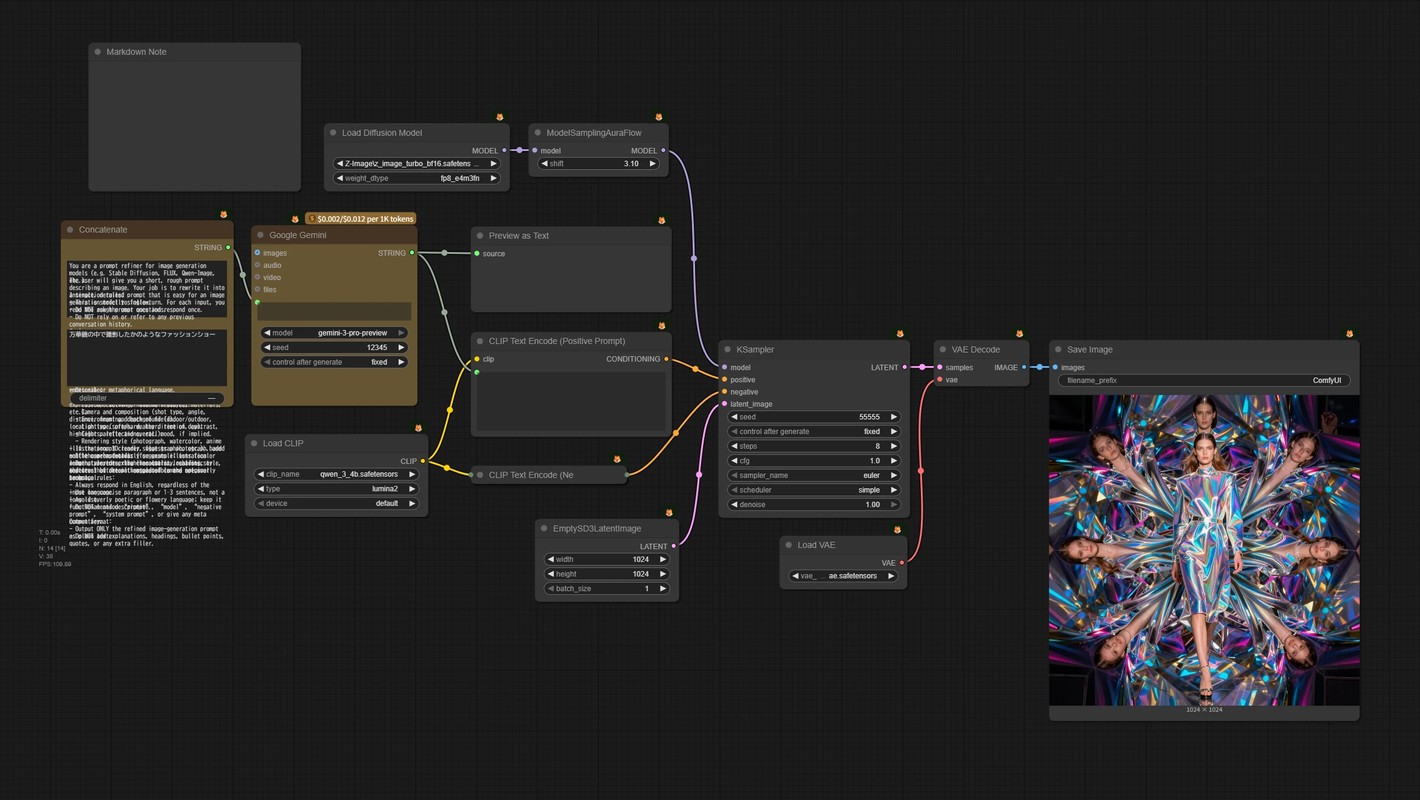
I'm one of those people who'd rather stick with local models, but honestly, running a decent LLM locally day to day is often harder on your PC than running an image generation model.
Luckily, LLM API fees are pretty cheap. I still haven't used up the $5 of credit I bought ages ago (´・ω・`)