What is a Latent Diffusion Model?
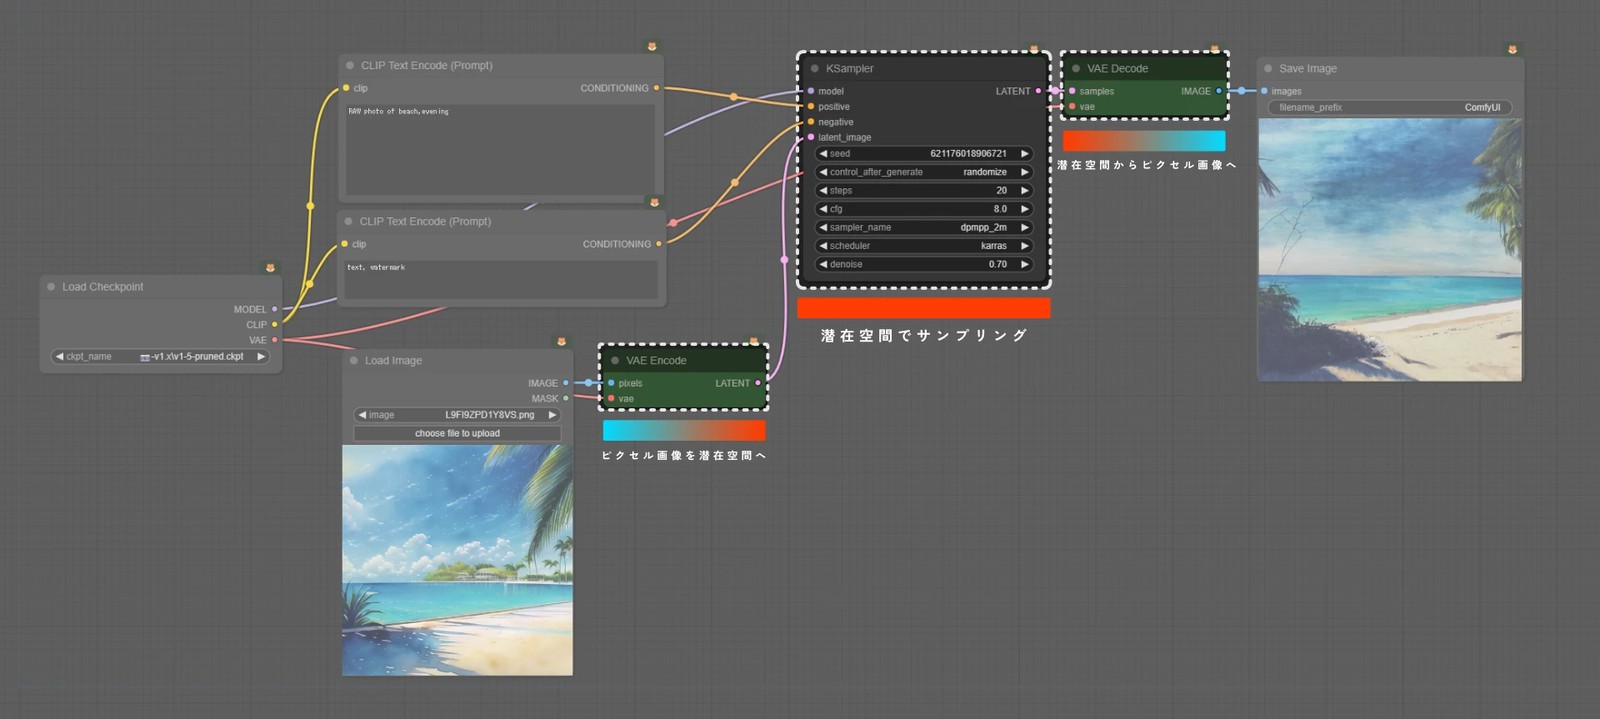
The Latent Diffusion Model is one of the biggest tricks that made it possible to run image generation AI on a home PC.
Running diffusion directly on ordinary images (pixels) means far too many pixels, so the computation gets heavy. Instead, the image is first converted into a compressed representation called "latent space" (latent), and noise is added and removed there.
For example, Stable Diffusion 1.5 compresses a 512×512×3 image into a 64×64×4 "latent image" and works with that.
Width and height each shrink to 1/8, so the pixel count drops to 1/64. "Doing diffusion in a world with far fewer pixels" is what made image generation fast enough to be practical at home!
Why Process in Latent Space?
1. Saving Computational Cost and VRAM
With a 512×512 image, you have to work out the color of every single one of those 512×512 dots.
A compressed latent is only 64×64, which cuts the computation dramatically.
2. Working with Meaningful Representations
What latent space compresses isn't fine pixel-level noise but high-level features like "object shape," "texture," and "overall color."
Latents are also a bit like "clay that hasn't settled into shape yet." Mixing pixel images together doesn't really do anything useful, but combining them as latents can sometimes produce a natural blend.
What is VAE?
A VAE (Variational Autoencoder) converts images into latent space and back again.
- Encoder: image → latent image
- Decoder: latent image → back to an image
Generation goes like this:
- 1. The diffusion model starts from a noisy latent image.
- 2. The U-Net (the diffusion model itself) removes noise from the latent bit by bit.
- 3. Finally, the VAE Decoder converts "latent image → normal image."
When the input is an image, as with img2img or inpainting, the image is first converted to a latent with the Encoder, and then the same steps follow.
The VAE Is Lossy Compression
The VAE is lossy compression.
If you convert an image to latent space and back again, it won't come back exactly the same. It gets slightly blurrier, or the colors and contrast shift.
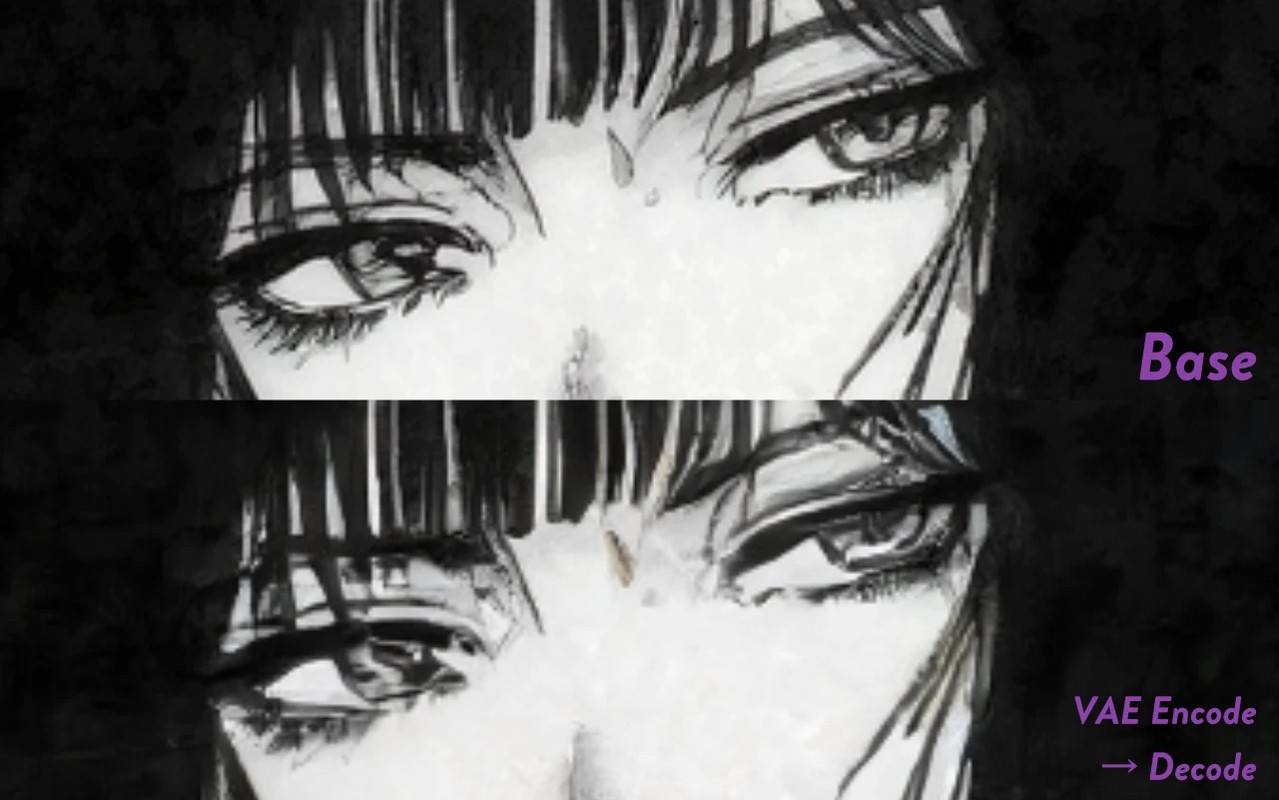
Try simply encoding an image with a VAE and decoding it with the same VAE, with no diffusion model involved, and you should see it has degraded a little. That trade-off, "a little degradation in exchange for being much lighter to work with," is what latent representations are all about.
Which VAE Should I Use?
Different models use different latent representations, so the VAE that produces them differs too.
Basically, you must use a VAE that matches the model.
Use the wrong VAE and you'll get images with odd colors or noise.