What is Pika H3 Flex?
Pika H3 Flex is MiniMax H3 with additional training by Pika.
Pika also builds its own video generation models, and the training used its own dataset.
On top of better quality, step distillation cuts it down to 6 steps, so generation feels very smooth.
Basic usage is the same as MiniMax H3. See that page for how to write prompts and which nodes to use.
Contains a referral link
Recommended Settings
- Resolution
- 768p, about 1 MP
- Width and height must be multiples of 32
- FPS
- 24 FPS
- Frames
17n + 5
- Video length
- 5–15 seconds
Model Download
LoRA
- loras
- pika_h3_flex_fl2va_v1_bf16.safetensors (1.96 GB)
- pika_h3_flex_ref2va_v1_bf16.safetensors (1.96 GB)
📂ComfyUI/
└── 📂models/
    └── 📂loras/
        ├── pika_h3_flex_fl2va_v1_bf16.safetensors
        └── pika_h3_flex_ref2va_v1_bf16.safetensors
Base Models
- checkpoints
- sam3.1_multiplex_fp16.safetensors (1.75 GB)
- diffusion_models
- text_encoders
- vae
📂ComfyUI/
└── 📂models/
    ├── 📂checkpoints/
    │   └── sam3.1_multiplex_fp16.safetensors
    ├── 📂diffusion_models/
    │   ├── minimax_h3_fl2va_pruned_int8_convrot.safetensors
    │   └── minimax_h3_ref2va_pruned_int8_convrot.safetensors
    ├── 📂text_encoders/
    │   └── qwen3vl_32b_minimax_h3_nvfp4_awq.safetensors
    └── 📂vae/
        ├── minimax_h3_audio_vae_fp32.safetensors
        └── minimax_h3_video_vae_int8_convrot.safetensors
text2video / T2VA
Model: fl2va
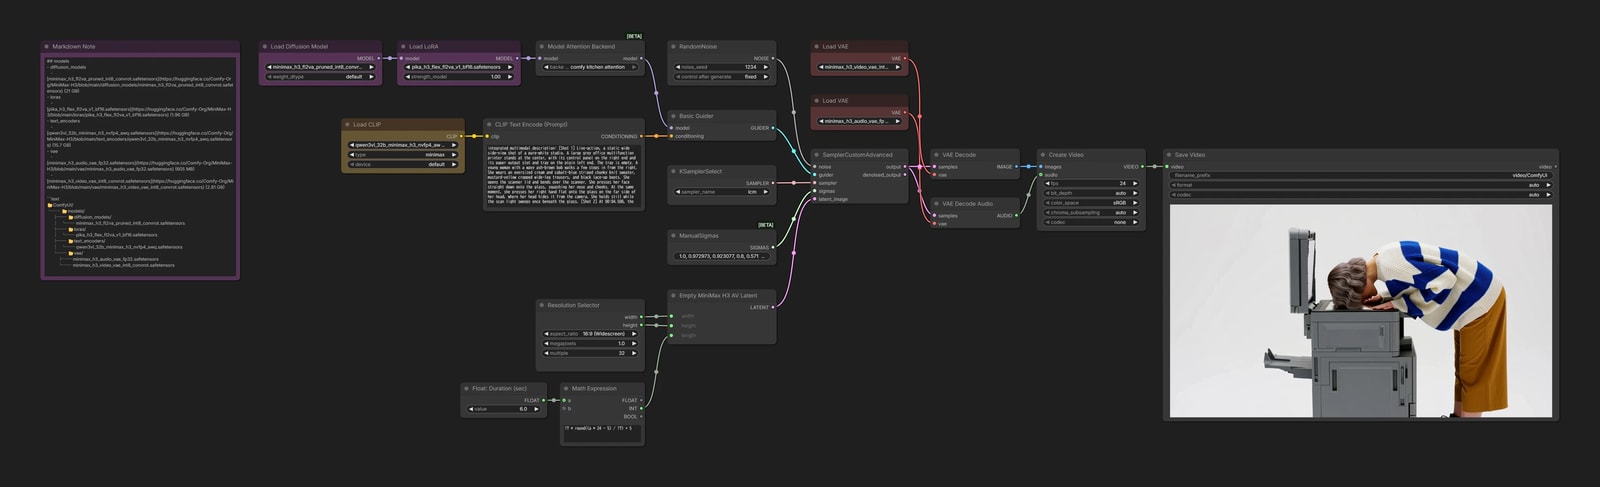
Load LoRA- Apply
pika_h3_flex_fl2va_v1_bf16.safetensorsat strength1.0
- Apply
SamplerCustomAdvanced+ManualSigmas- Use the 6-step sigmas Pika specifies
1.0, 0.972973, 0.923077, 0.8, 0.571429, 0.333333, 0.0- The sampler is
lcm
Outputs
image2video / I2VA
Model: fl2va
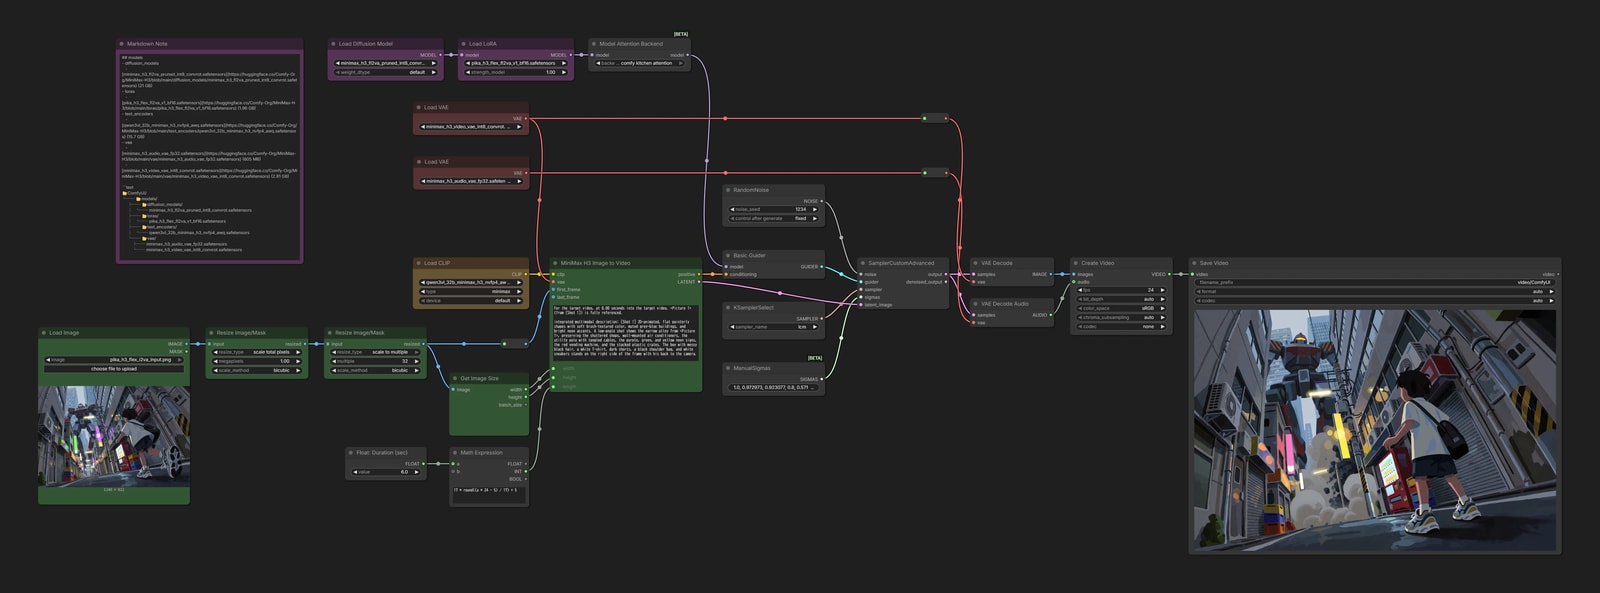
Outputs
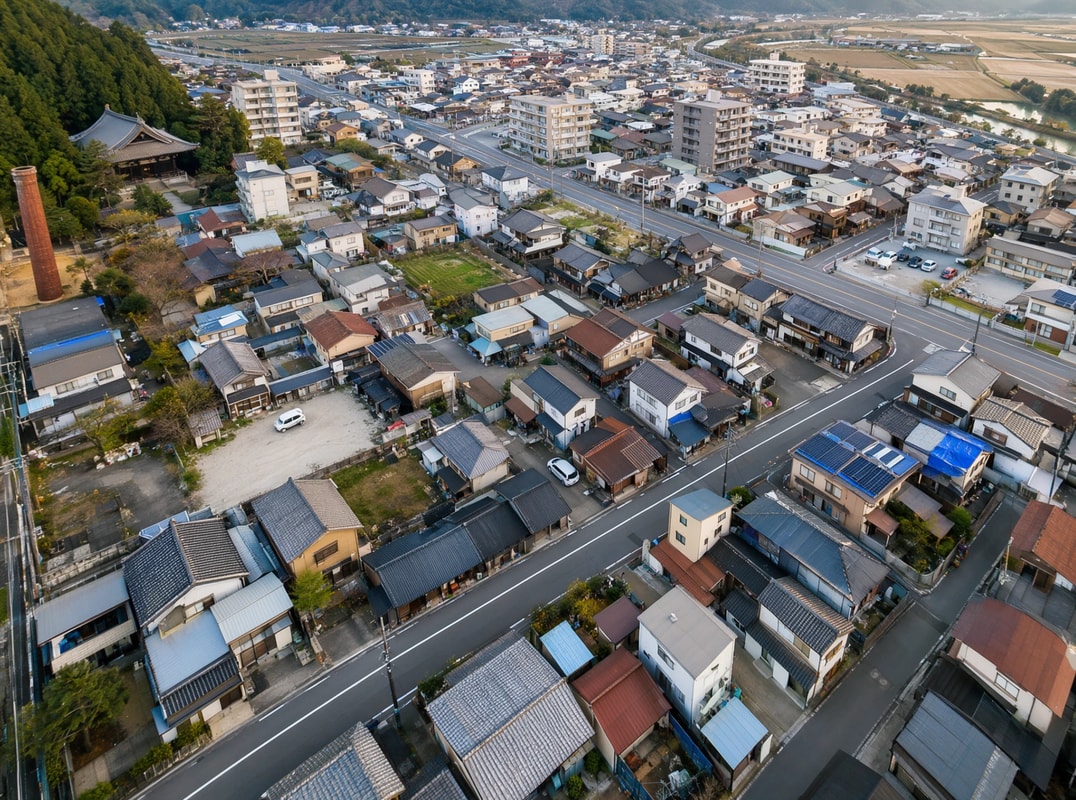
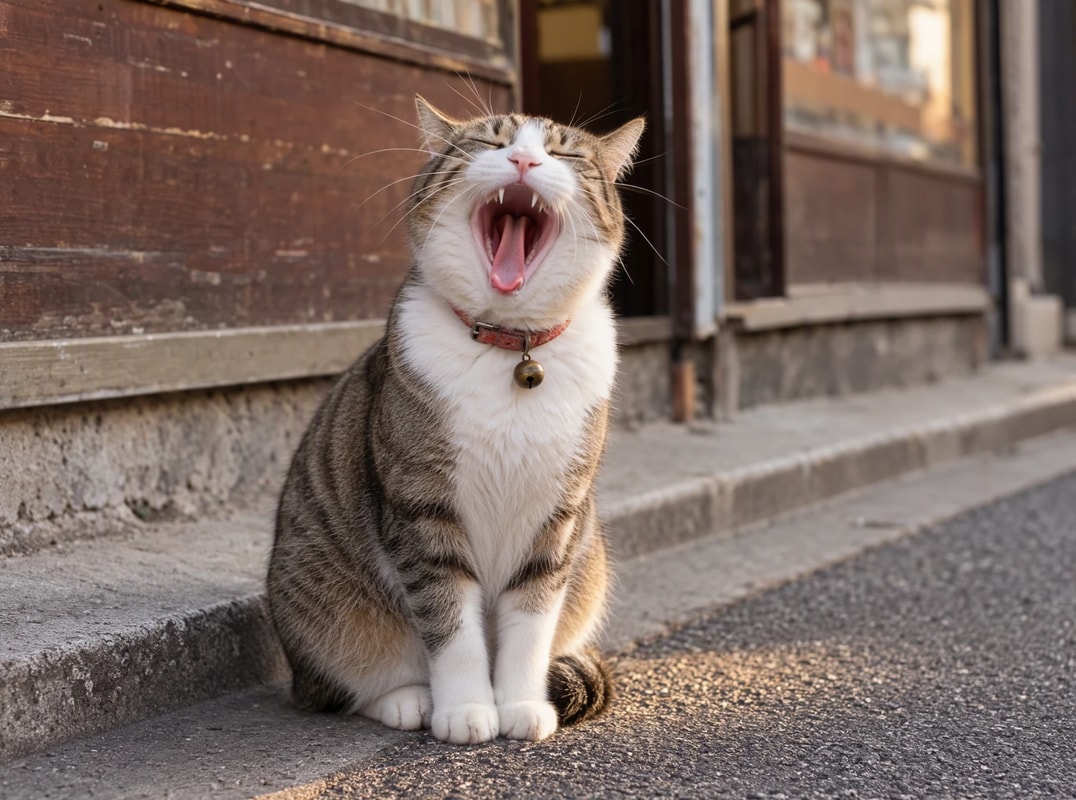
First / Last Frame to Video
Model: fl2va
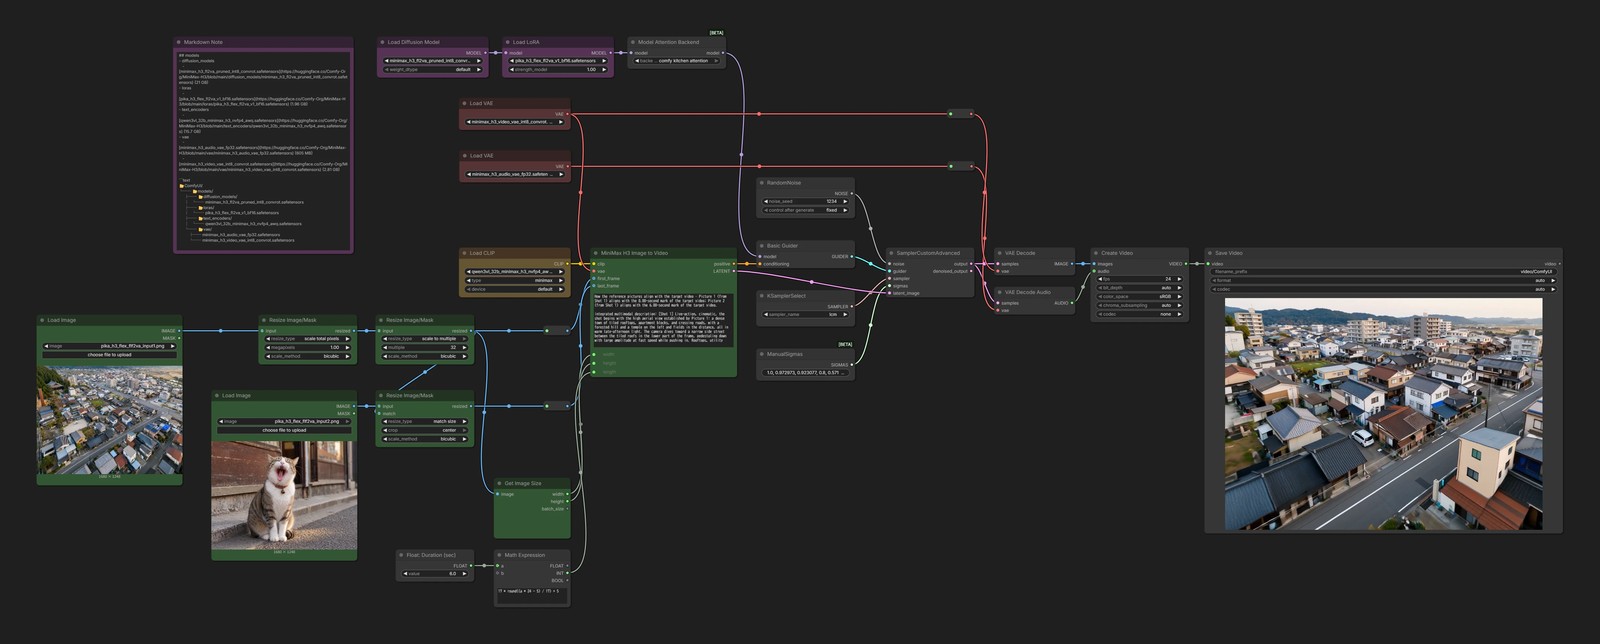
Outputs
Reference Generation
Model: ref2va
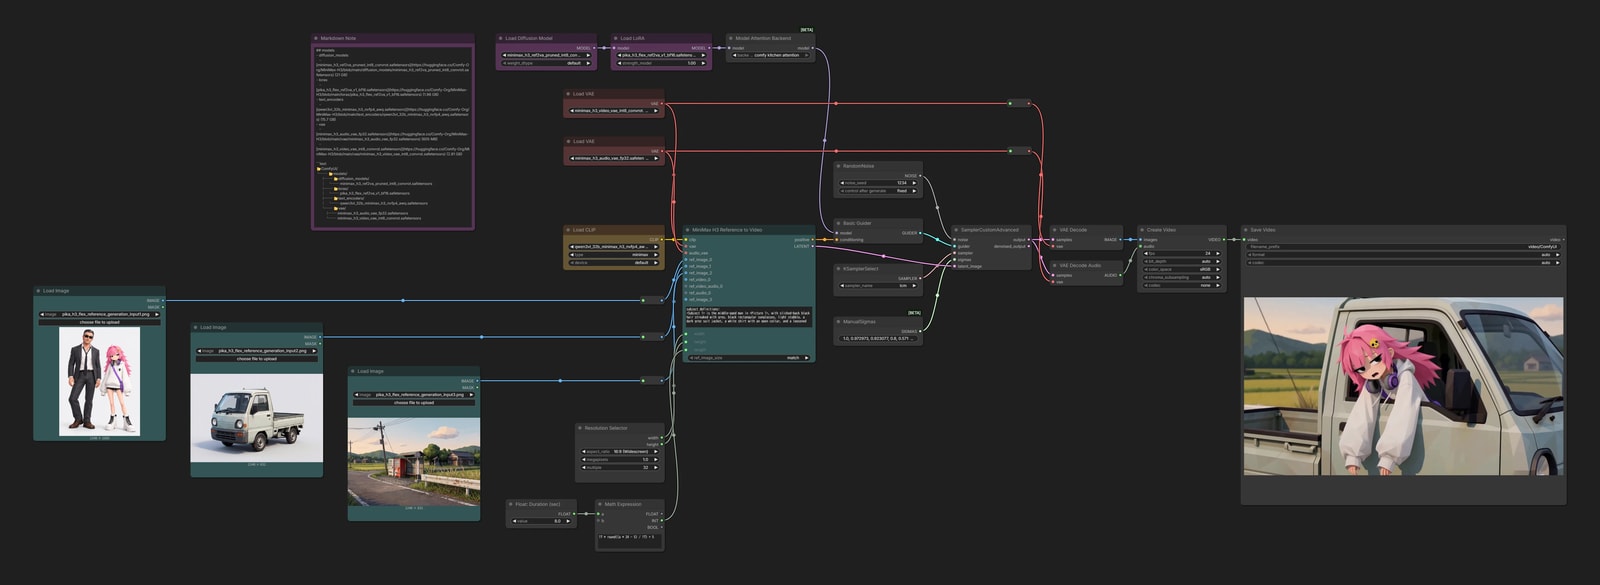
Load LoRA- Apply
pika_h3_flex_ref2va_v1_bf16.safetensorsat strength1.0
- Apply
Outputs
Video Editing
Model: ref2va
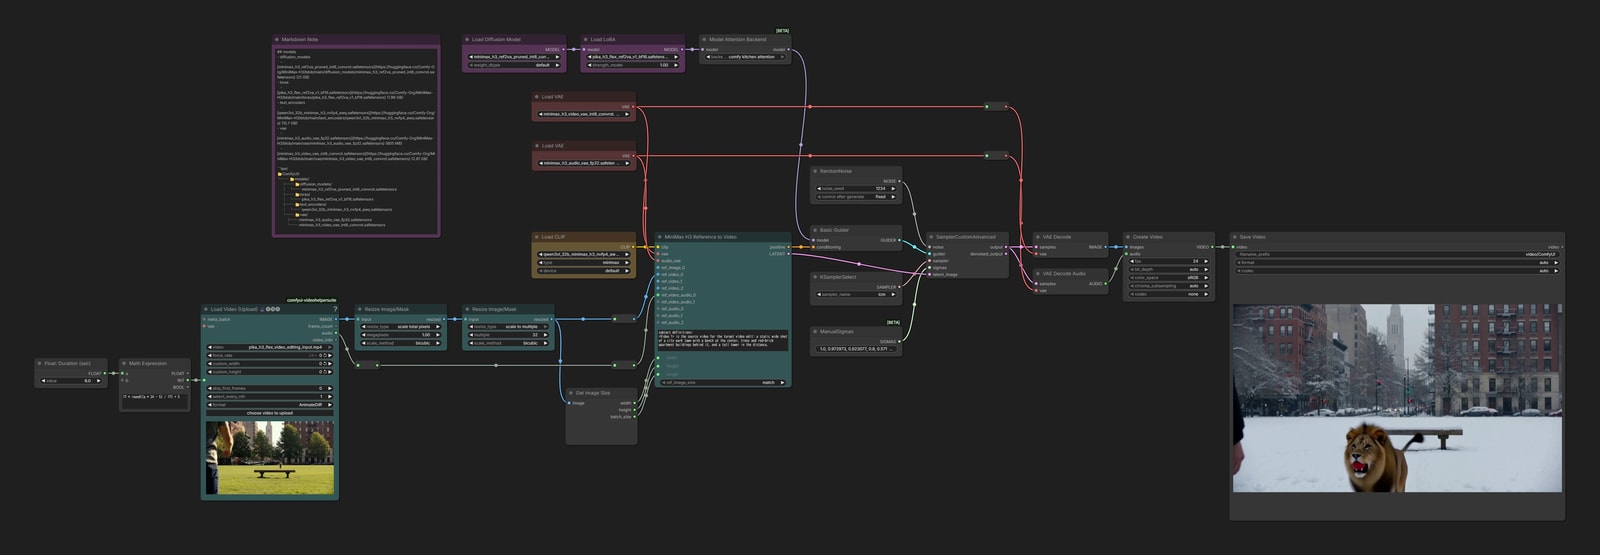
Outputs
Spatial Inpainting
Model: ref2va
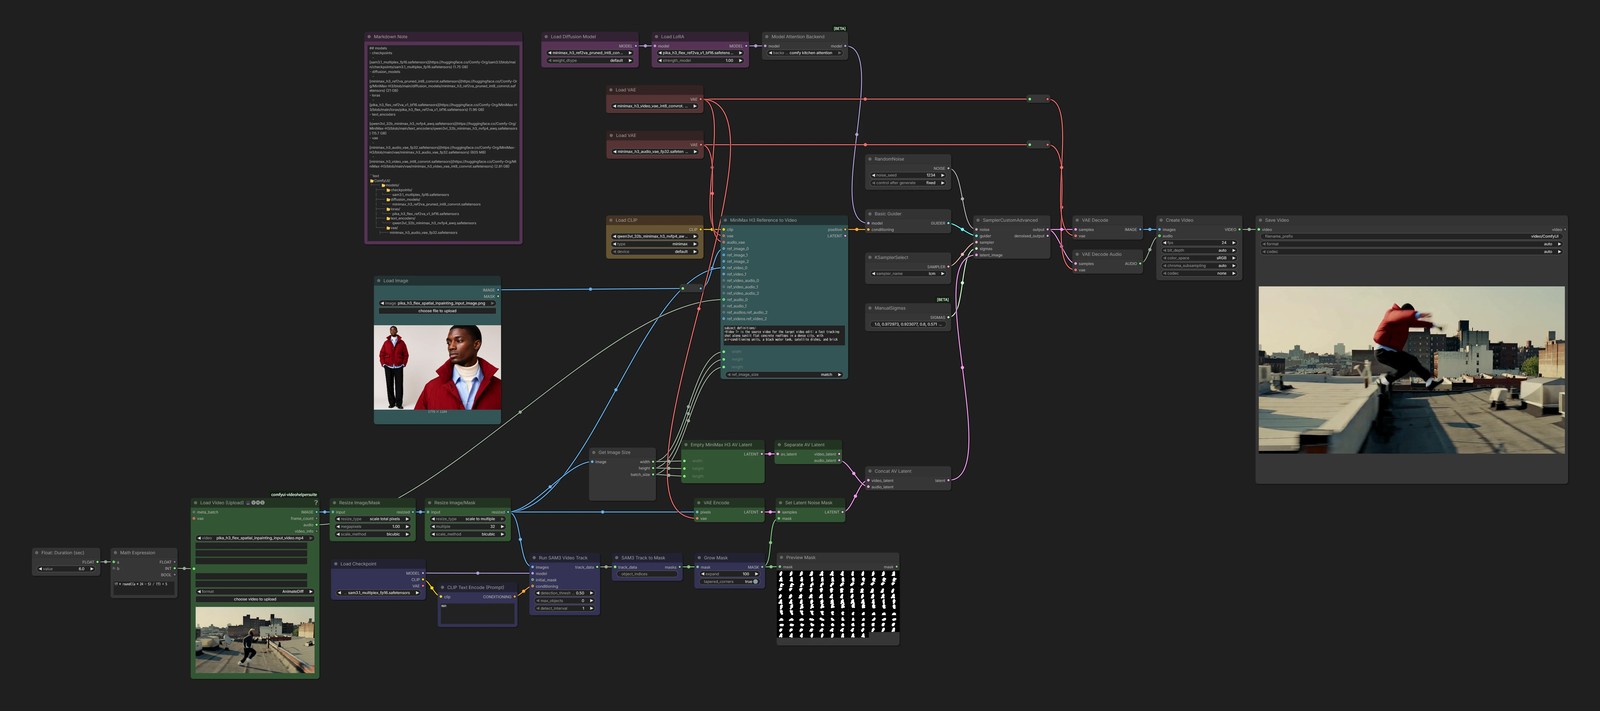
Outputs