What is SCAIL-2?
SCAIL-2 is a Wan2.1-based model specialized for motion transfer to people and characters.
The major difference from Wan-Animate and the previous SCAIL-1 is that it does not convert the input into an intermediate representation such as a stick figure.
The usual idea has been to make a stick figure with ViTPose or OpenPose, then use that as the condition for moving the person. But once you convert the video into a stick figure, a lot of information is lost.
Depth, contact, intertwined multi-person motion, non-human character motion, and so on...
So SCAIL-2 passes the reference image and motion video almost directly to the DiT.
Rather than having people hand-craft a complicated processing pipeline, building the right dataset and letting the AI understand the task gives you something more flexible and easier to use. I expect we'll see this way of thinking more and more.
Model Download
- checkpoints
- sam3.1_multiplex_fp16.safetensors (1.75 GB)
- clip_vision
- clip_vision_h.safetensors (1.26 GB)
- diffusion_models
- loras
- text_encoders
- umt5_xxl_fp8_e4m3fn_scaled.safetensors (6.74 GB)
- vae
- wan_2.1_vae.safetensors (254 MB)
📂ComfyUI/
└── 📂models/
    ├── 📂checkpoints/
    │   └── sam3.1_multiplex_fp16.safetensors
    ├── 📂clip_vision/
    │   └── clip_vision_h.safetensors
    ├── 📂diffusion_models/
    │   └── wan2.1_14B_SCAIL_2_fp8_scaled.safetensors
    ├── 📂loras/
    │   └── Wan21_I2V_14B_lightx2v_cfg_step_distill_lora_rank64.safetensors
    ├── 📂text_encoders/
    │   └── umt5_xxl_fp8_e4m3fn_scaled.safetensors
    └── 📂vae/
        └── wan_2.1_vae.safetensors
Animation Mode
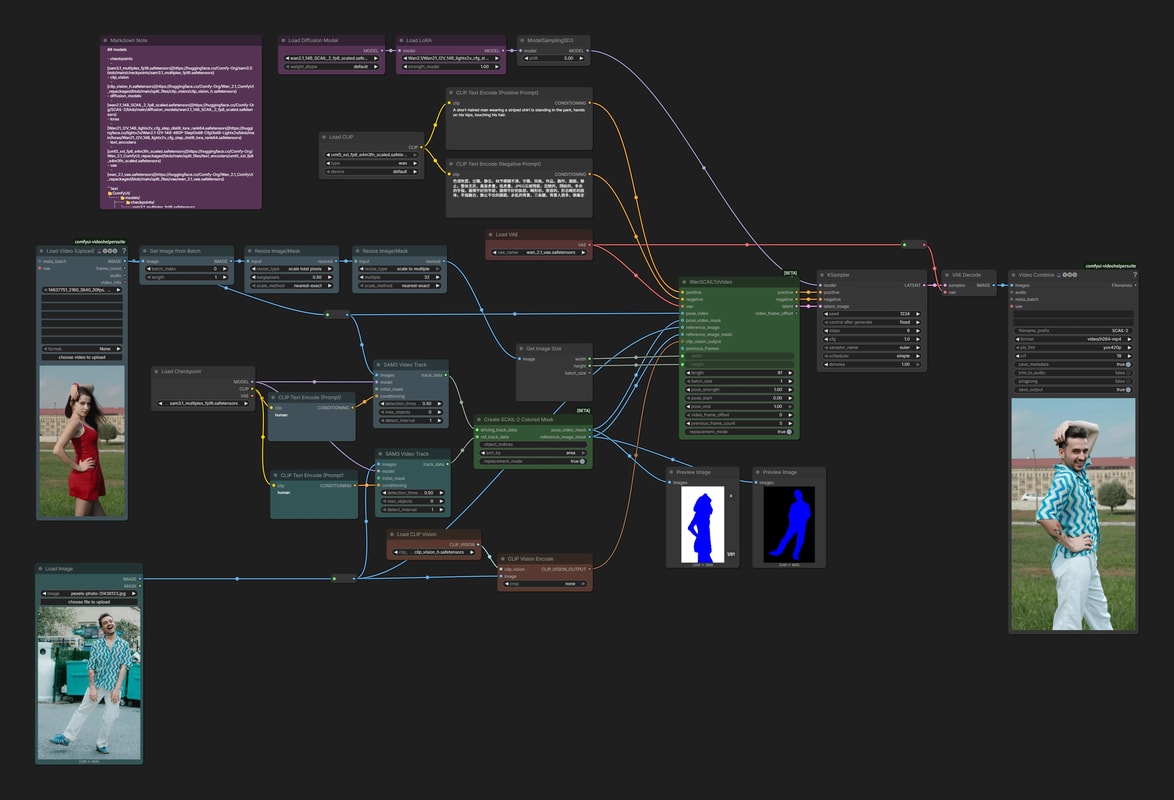
Move a reference image using a motion video.
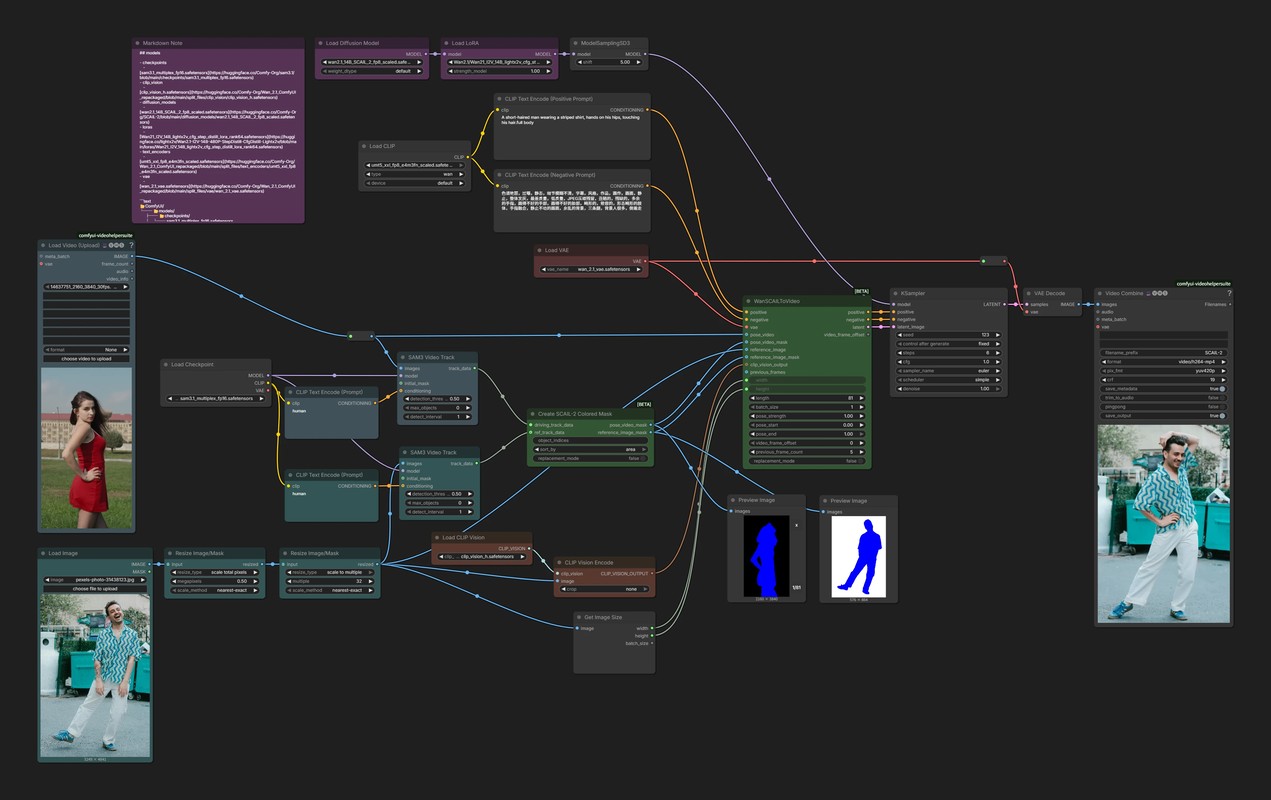
The base workflow is the same as Wan-Animate, but it's much simpler, so let's take it easy and go through it.
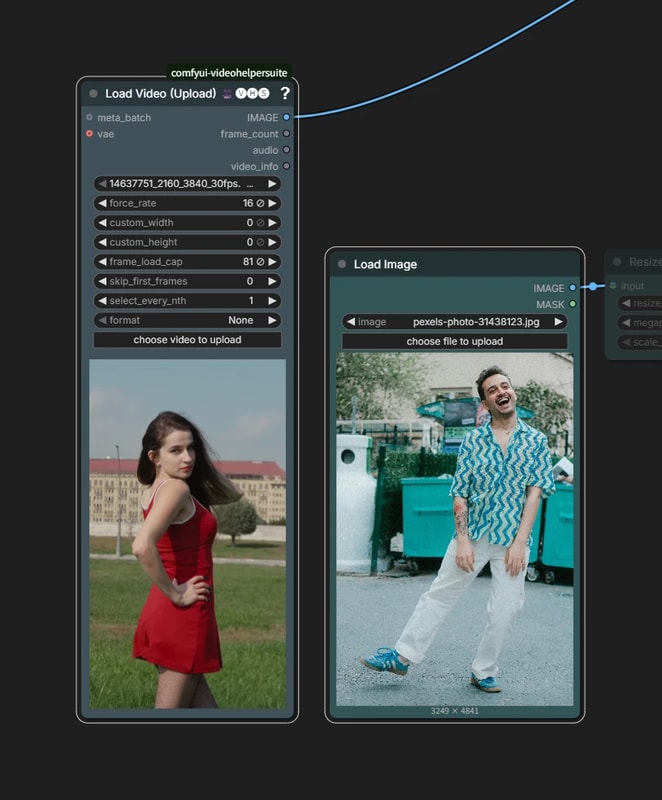
Reference Image / Motion Video
The reference image and motion video are resized internally, so they do not need to be the same size.
- Similar aspect ratios are easier to handle.
- The pose in the image and the pose in the video do not need to match perfectly.
- However, if they are too different, generation will fail.
- It's better to choose a reference image close to the first frame of the motion video.
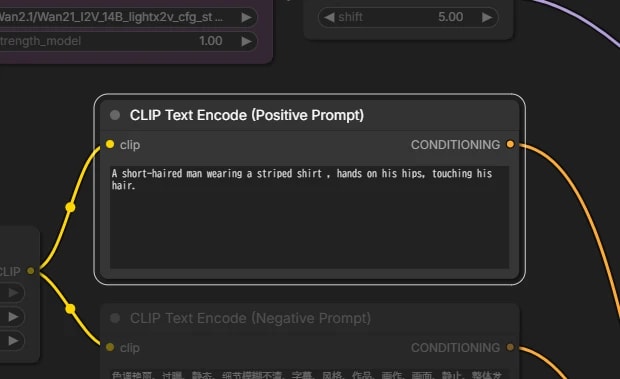
Prompt
Since this is just motion transfer, you do not need a detailed prompt.
- However, if the prompt is too short, generation can fail more easily, especially in Replacement Mode.
- For this example, write enough to describe the intended video, such as
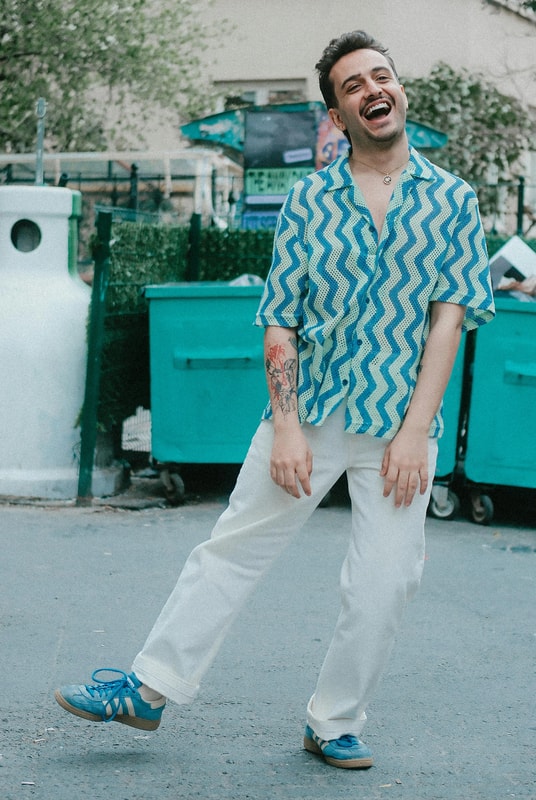
a man in a shirt is standing with one hand on his waist and touching his hair.
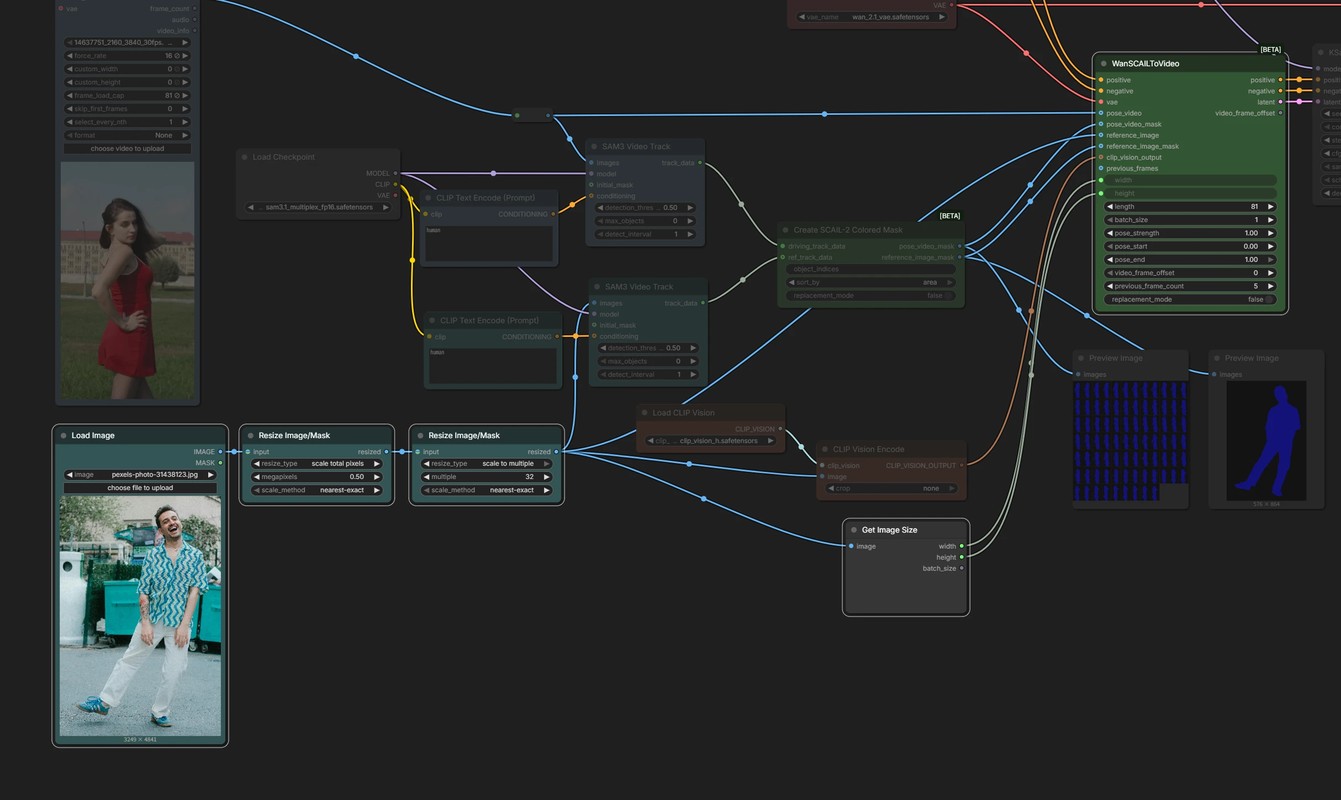
Resolution / Frame Count
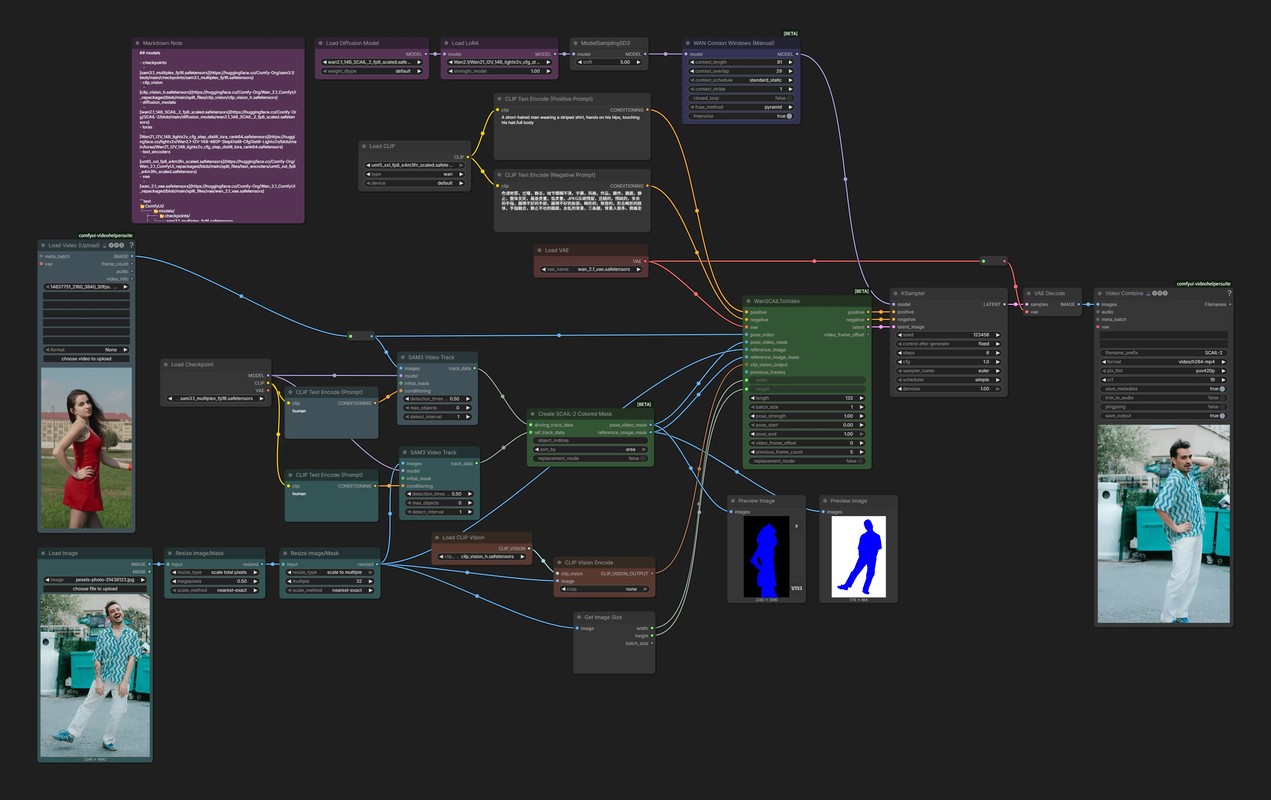
Set the generation size and frame count in WanSCAILToVideo.
- Recommended resolution is 480p (864×480) to roughly 720p (1280×704), and a multiple of 32
- Maximum frame count is 81
- In this workflow, the reference image is resized and that size is used as the generation resolution.
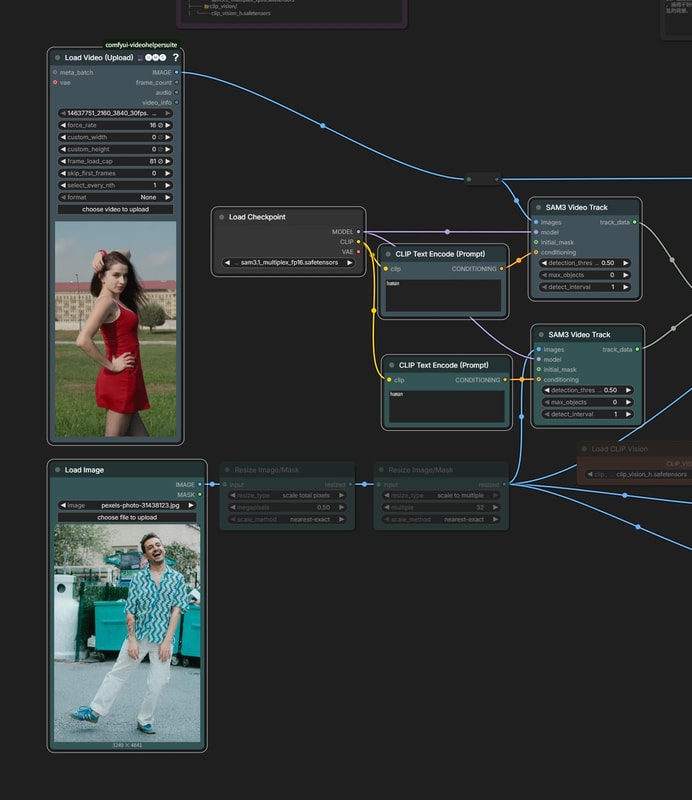
Mask Generation with SAM3.1
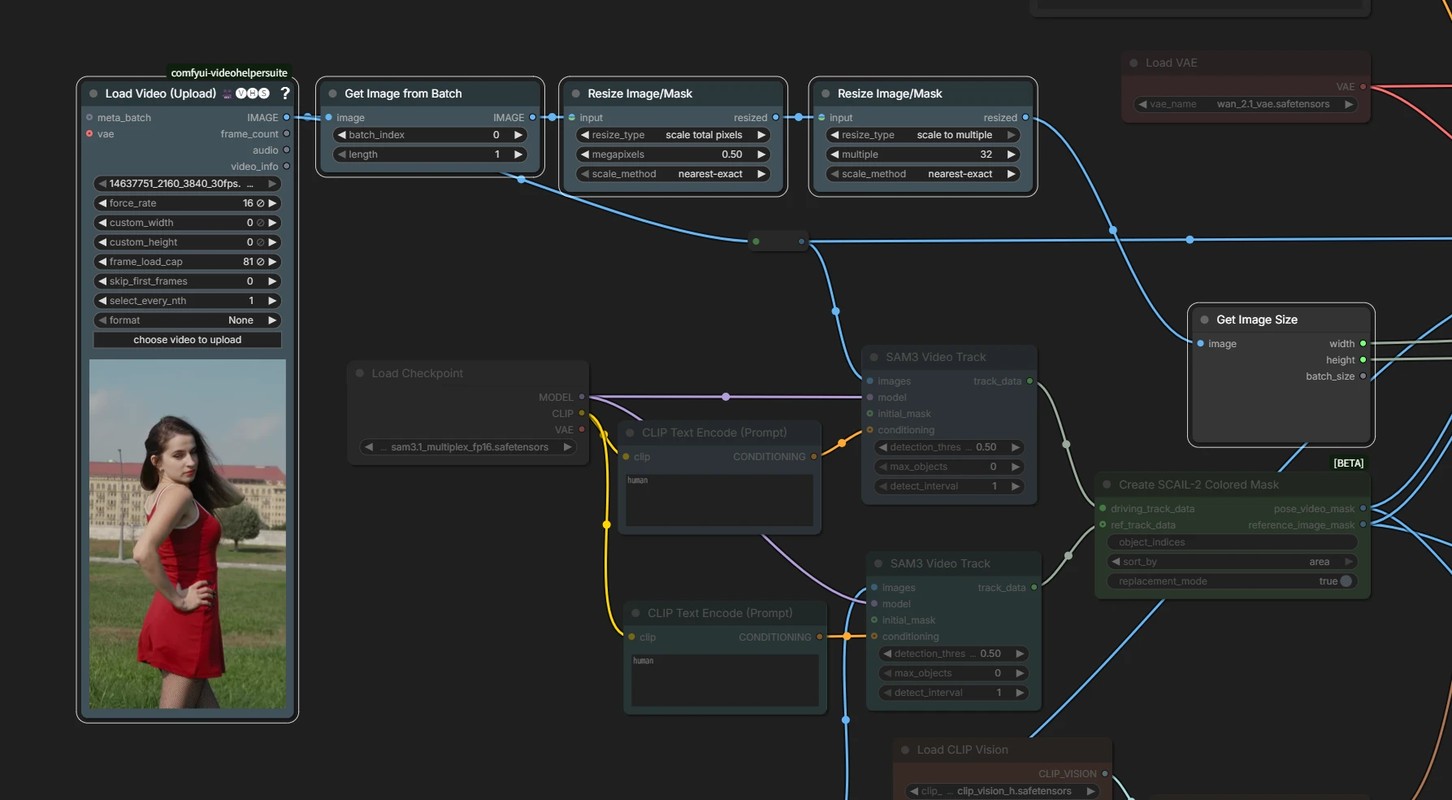
Mask the people in the reference image and motion video with SAM 3 / 3.1.
- This is not a strict inpainting mask. It is just a helper that tells SCAIL-2 which people correspond to each other, so a little misalignment is fine.
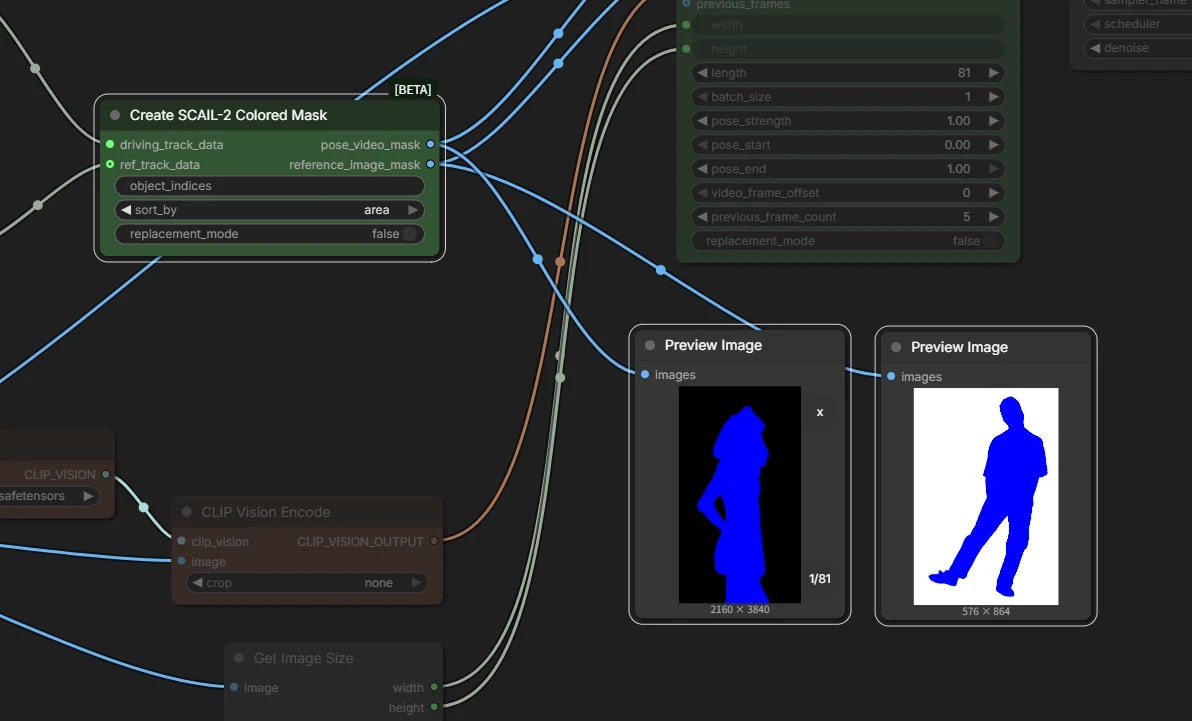
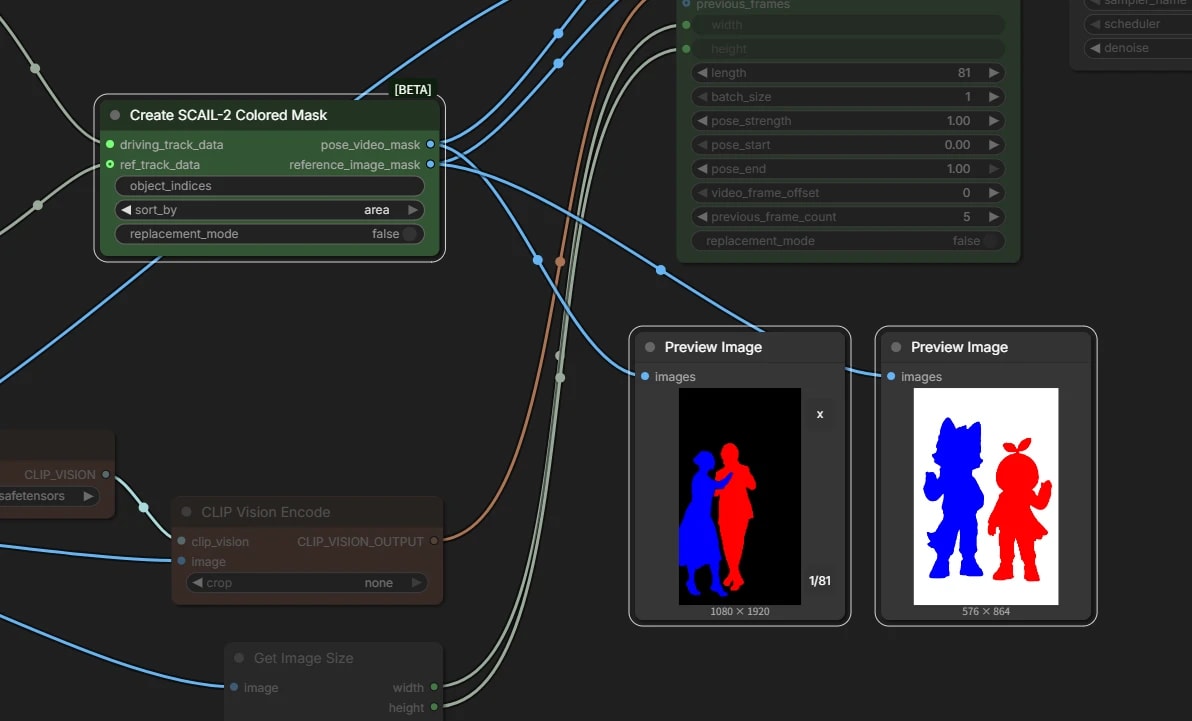
Create SCAIL-2 Colored Mask
The generated masks are colored appropriately.
- This becomes a little more important when there are multiple people. More on that later.
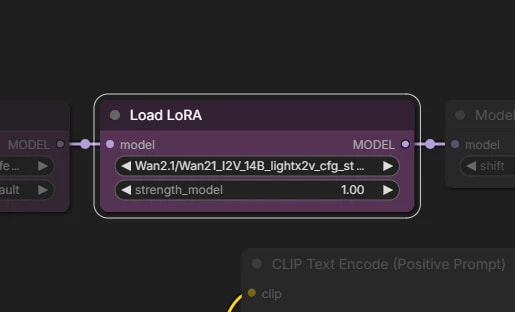
6-Step Generation
SCAIL-2 can also use the Lightx2v LoRA for fast Wan2.1 generation.
cfgis 1.0stepsis 6
Replacement Mode
Replace the person in the video with the person in the reference image.
Basically, just set replacement_mode to true in Create SCAIL-2 Colored Mask and WanSCAILToVideo.
Resolution
Replacement uses the video size as the base.
- In this workflow, it resizes the first frame of the video, reads that size, and sets it as the output size.
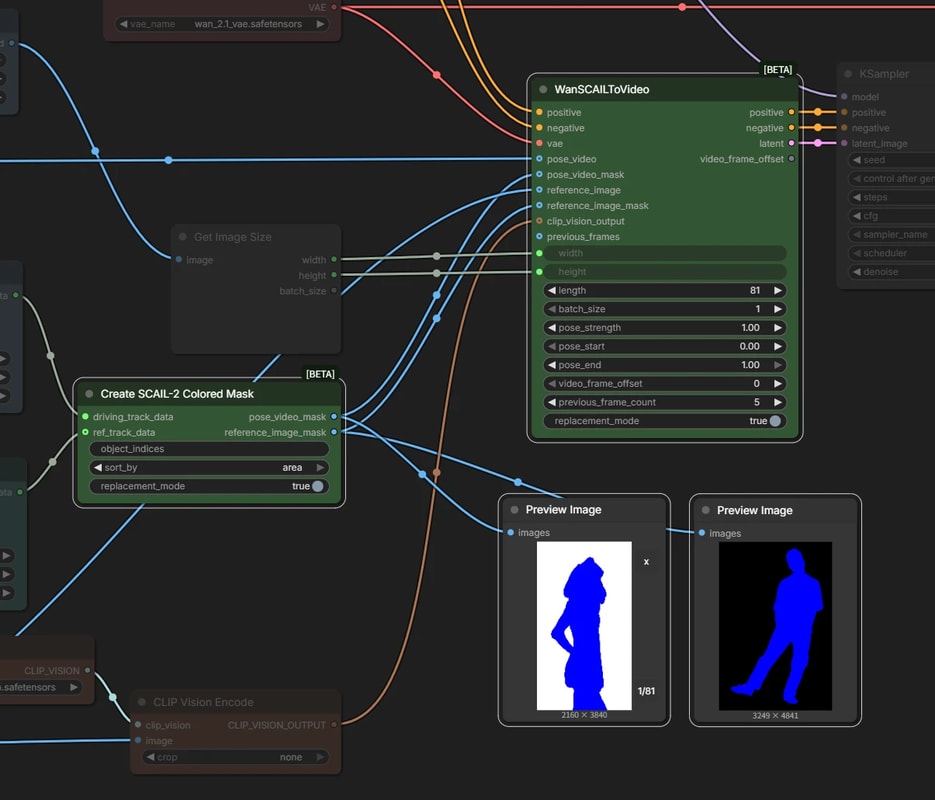
Create SCAIL-2 Colored Mask and WanSCAILToVideo
Set replacement_mode to true.
- By the way, the output of
Create SCAIL-2 Colored Maskonly makes the pose_video background white.
From here on, the examples use Animation mode, but all of them can also be used in Replacement mode.
Animation Mode (Multiple People)
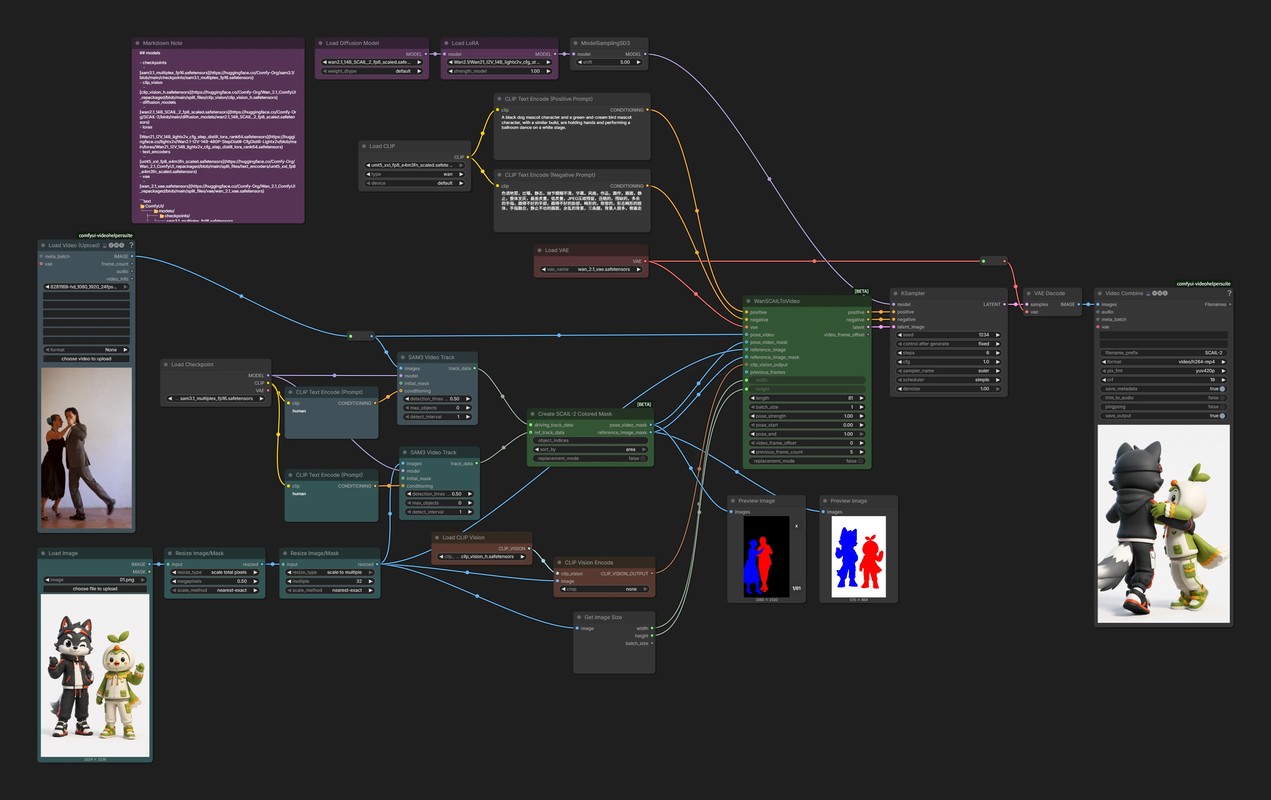
SCAIL-2 also supports videos and images with multiple people.
Nothing special is needed. Just input the video and reference image as before.
Create SCAIL-2 Colored Mask
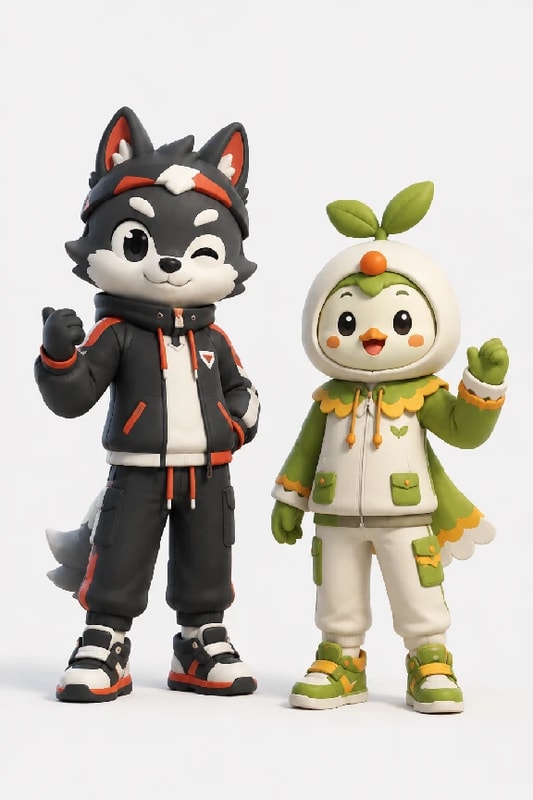
With multiple people, which motion goes to which person becomes important, and SCAIL-2 controls this with colored masks.
- When SAM3.1 segments multiple targets,
Create SCAIL-2 Colored Maskpaints them in different colors in order. - Basically, matching colors are linked together, so use options such as
sort_byto align the colors.
However, as in the output example below, the color correspondence and the motion may not always match. It's only a loose condition, and sometimes the model simply picks whichever is closer in composition.
Animation Mode (Multiple References)
You can also provide several reference images at once, such as another angle of the same person or a separate background image.
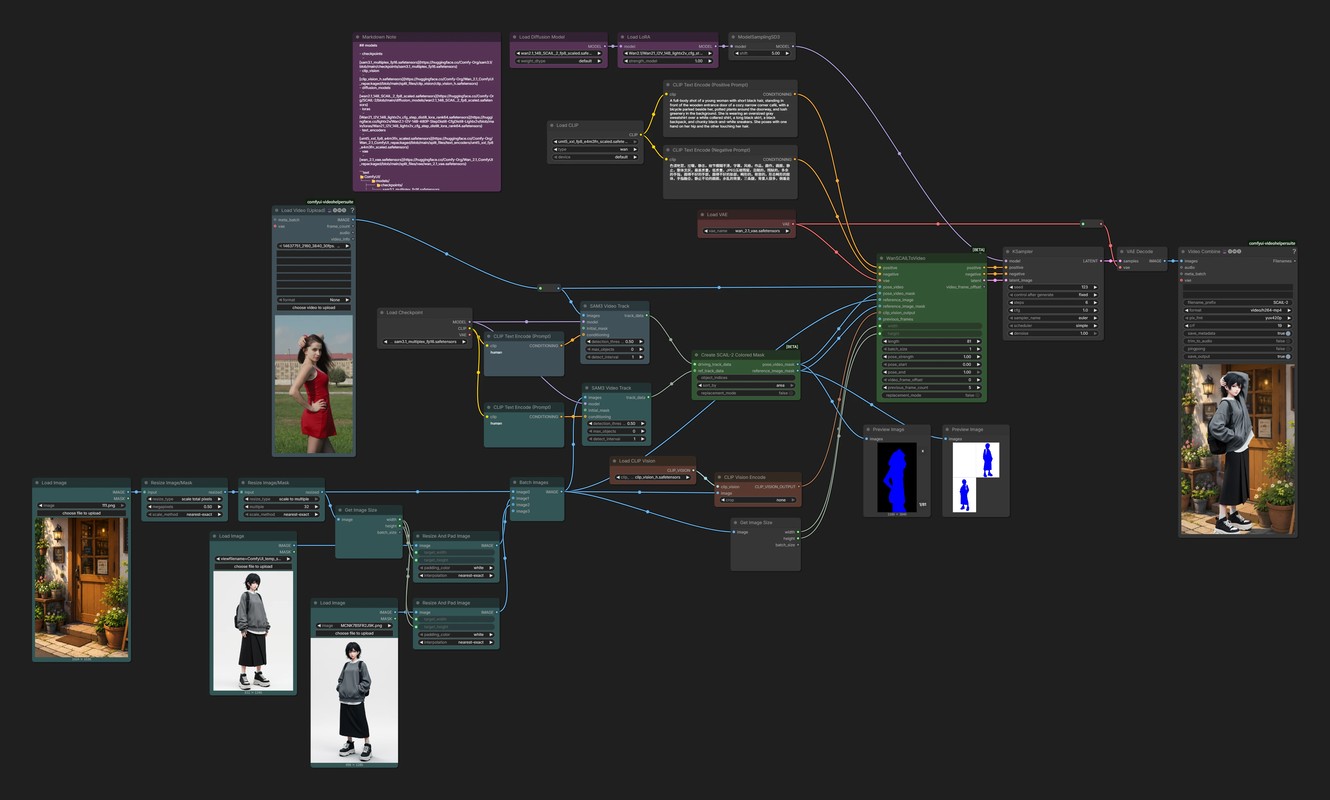
The basic flow is the same as the normal Animation mode. The difference is that the reference images are passed in as a batch instead of a single image.
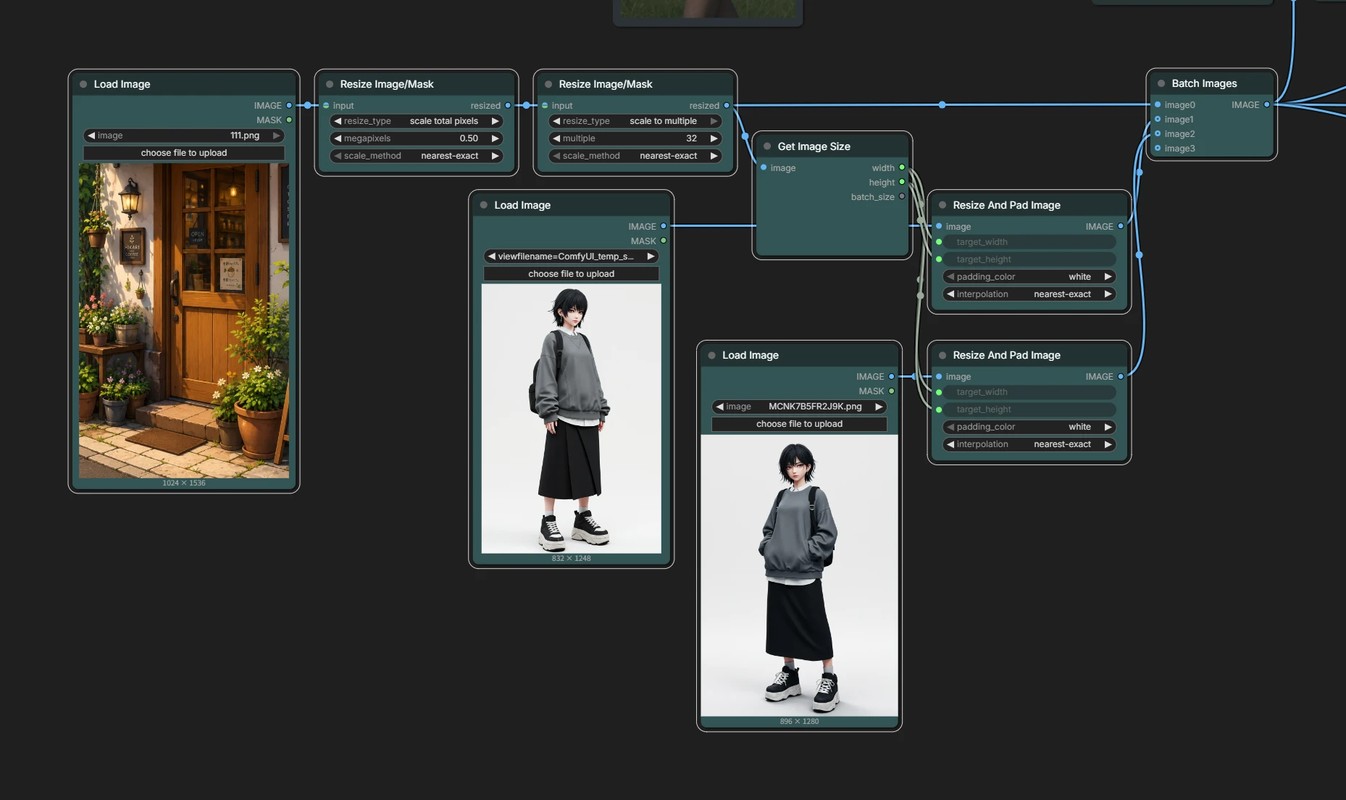
Batch input
Input the images you want to reference into Batch Images.
- Once the images are batched, they are all cropped to the same size as the first image.
- Images after the first one usually do not need to be resized, but anything outside that size will not be reflected.
- In this workflow, the later images are padded to match the first image size.
- The last input image is reflected most strongly.
- It seems better to place the person you want to move after the background.
You can use multiple reference images, but it won't adjust the background to match the person's size or relight the whole scene naturally.
It works well for filling in a person from other angles, but if you want to composite a background, you're better off building a single image with image editing than using this feature.
Animation Mode (Over 81 Frames)
SCAIL-2 normally generates up to 81 frames, but with WAN Context Windows (Manual), you can generate longer videos by splitting them along the time axis.
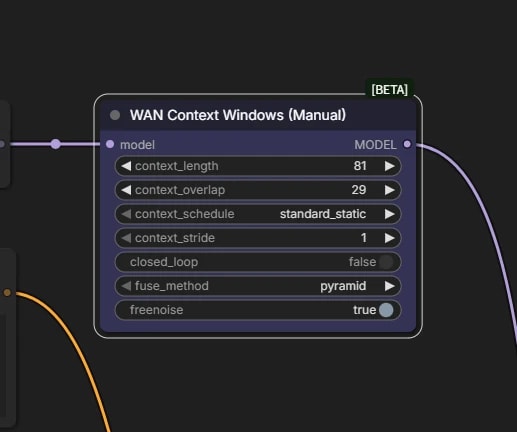
WAN Context Windows (Manual)
It's something like tiling along the time axis, or context sliding.
- Set
context_lengthto 81, and it generates internally in chunks of 81 frames. - If you leave it as-is, the seams will be obvious, so set
context_overlapto a suitable number of frames as an overlap margin.