What is Subject Transfer?
The formal name for this task is "Subject-Driven Image Generation."
A "subject" isn't just a person. It can be a character, a stuffed animal, a particular dog, a mascot, a figure... basically "that thing in this image." Subject transfer is about generating images that contain the same subject shown in the reference image.
Transferring ID (a person's face and identity) is technically part of subject transfer, but it gets special treatment and has many dedicated techniques, so it's covered separately.
LoRA
Needless to say, this is the way to train a model so it can draw things it couldn't before.
From the day it appeared until now, nothing has beaten it for flexibility and stability.
The big problem is that it requires training. It's not something you can just casually do.
image2prompt
The most basic approach is to "generate a caption from the image, then run text2image with that caption."
"Something that primitive?" you might think, but in principle it works, as long as you have an MLLM that can describe the reference image perfectly and an image model that can reproduce that description perfectly.
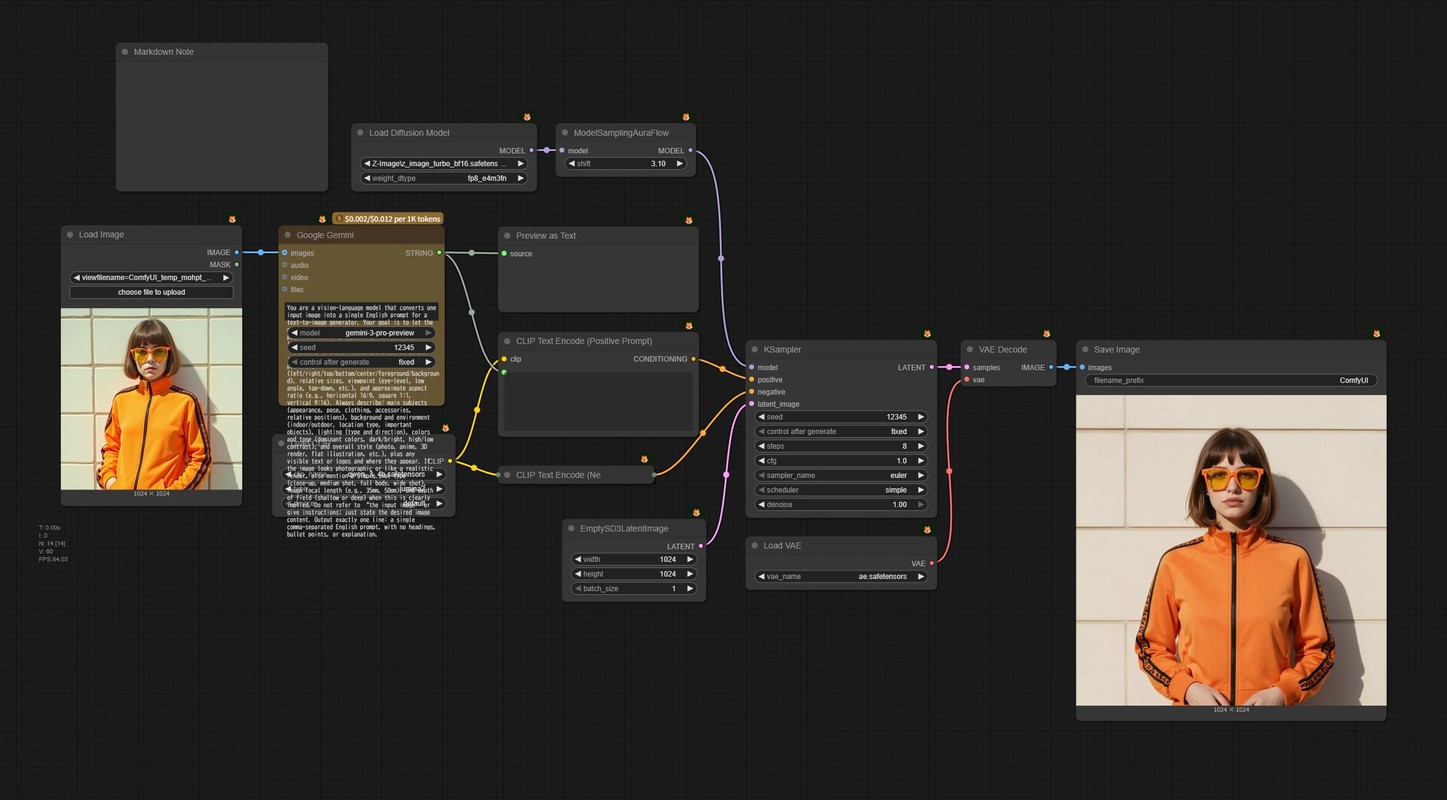
Recent models are getting close to making that possible. As "the cheapest knockoff of subject transfer," it's worth a try.
SeeCoder / UnCLIP Family
image2prompt is a two-step "image → text → embedding" process, but SeeCoder and the UnCLIP family go from "image → embedding" directly.
They create a vector equivalent to a text embedding from the image and use it in place of the text encoder.
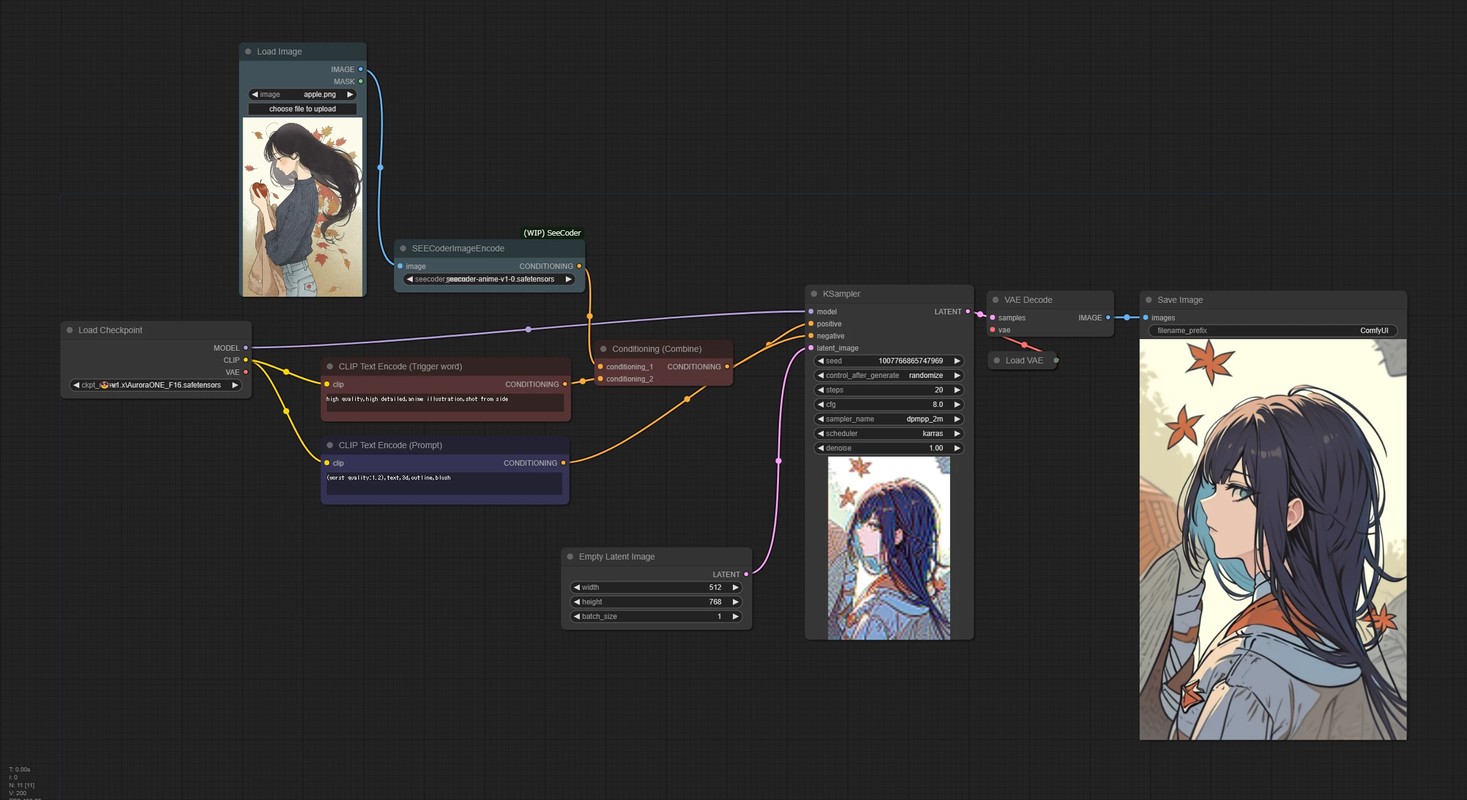
You lose less information than image2prompt does when converting to text, but since you can't edit it as text, it's less convenient to use.
IP-Adapter
This was the first "subject transfer without training" technique that was good enough for real-world use.
IP-Adapter is an adapter that feeds "conditions from an image" into existing text2image models. Next to ControlNet, it was one of the most widely used adapters.
It extracts feature vectors from the reference image and injects them into the UNet (around the Cross-Attention layers, etc.) so they show up in the output. Because it works alongside a text prompt, you can split the roles: "subject from the image, scene and style from the text."
IC-LoRA / ACE++
DiT models such as Flux have a latent ability to "create consistent images."
IC-LoRA / ACE++ use this property for subject transfer.
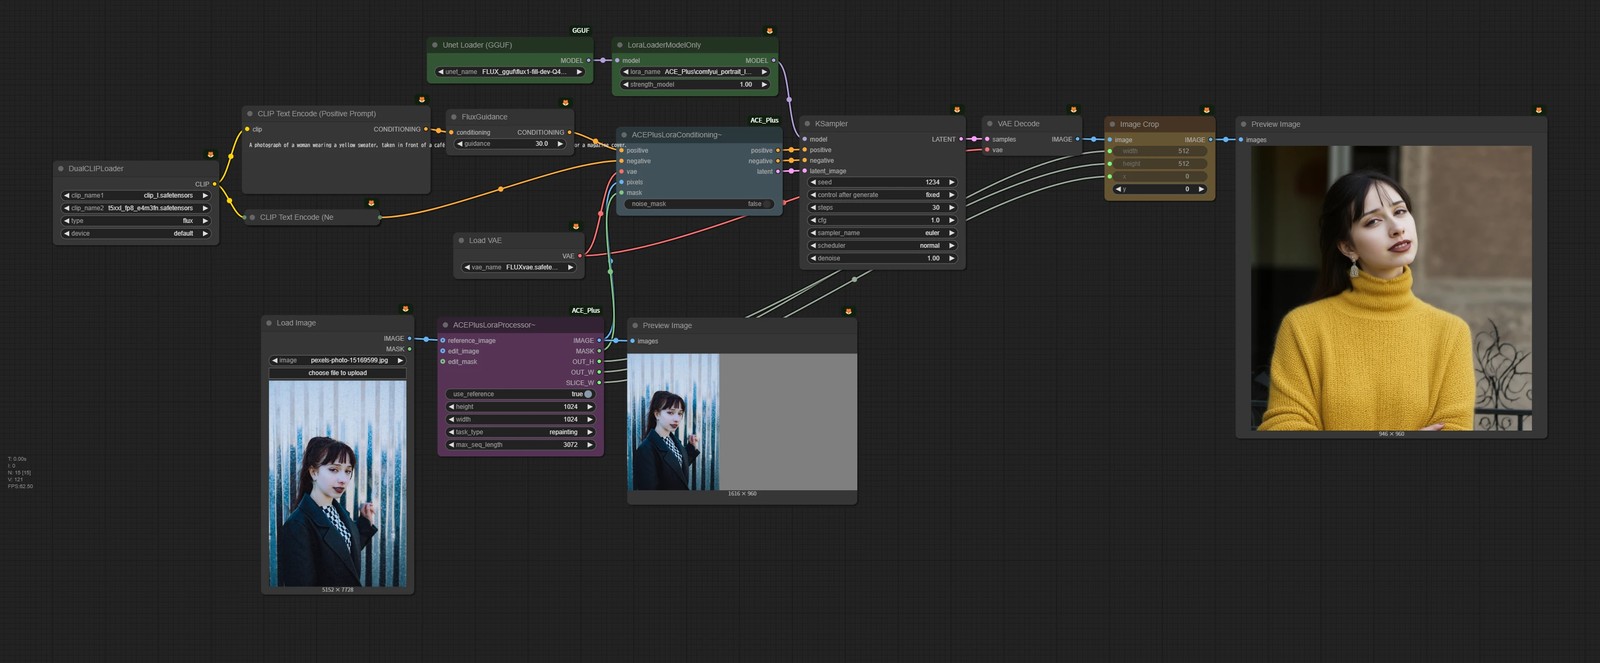
You place the reference image (with the subject) on the left side of the canvas, mask the entire right side, and generate (inpaint). The model fills in the right side while looking at the left, so it can "generate a new image with the same subject as on the left."
Instruction-Based Image Editing Models
"Instruction-based image editing models" can be used for subject transfer too.
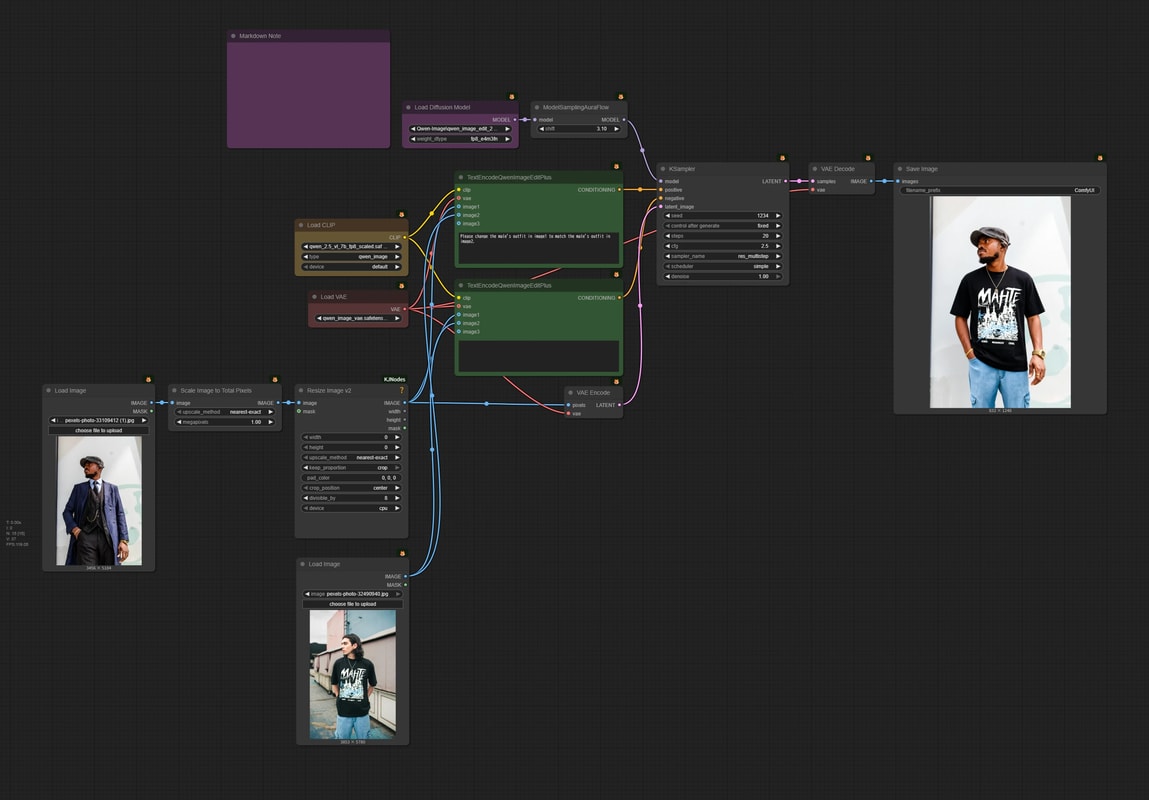
These models can edit images from text instructions like "put this dog in front of a different background" or "place this person in a forest."
And if the model supports multiple reference images, you can even do things like swap "the outfit of the person in image A" for "the outfit of the person in image B."