What is Florence-2?
It is a general-purpose VLM (Visual Language Model) that can handle multiple tasks such as caption generation, object detection, segmentation, and OCR with a single model by looking at an image.
In this page, we will focus on four tasks often used in ComfyUI: "Caption Generation", "Object Detection (Coordinate Extraction)", "OCR", and "Q&A about Images".
Custom Node
- kijai/ComfyUI-Florence2
- The model is automatically downloaded at the first run.
Florence2Run Node
Florence2Run is the main node for having Florence-2 execute tasks on the input image. By switching task, you can use functions such as caption generation, object detection, and OCR properly.
caption, detailed caption
Generates a natural language caption from the image.
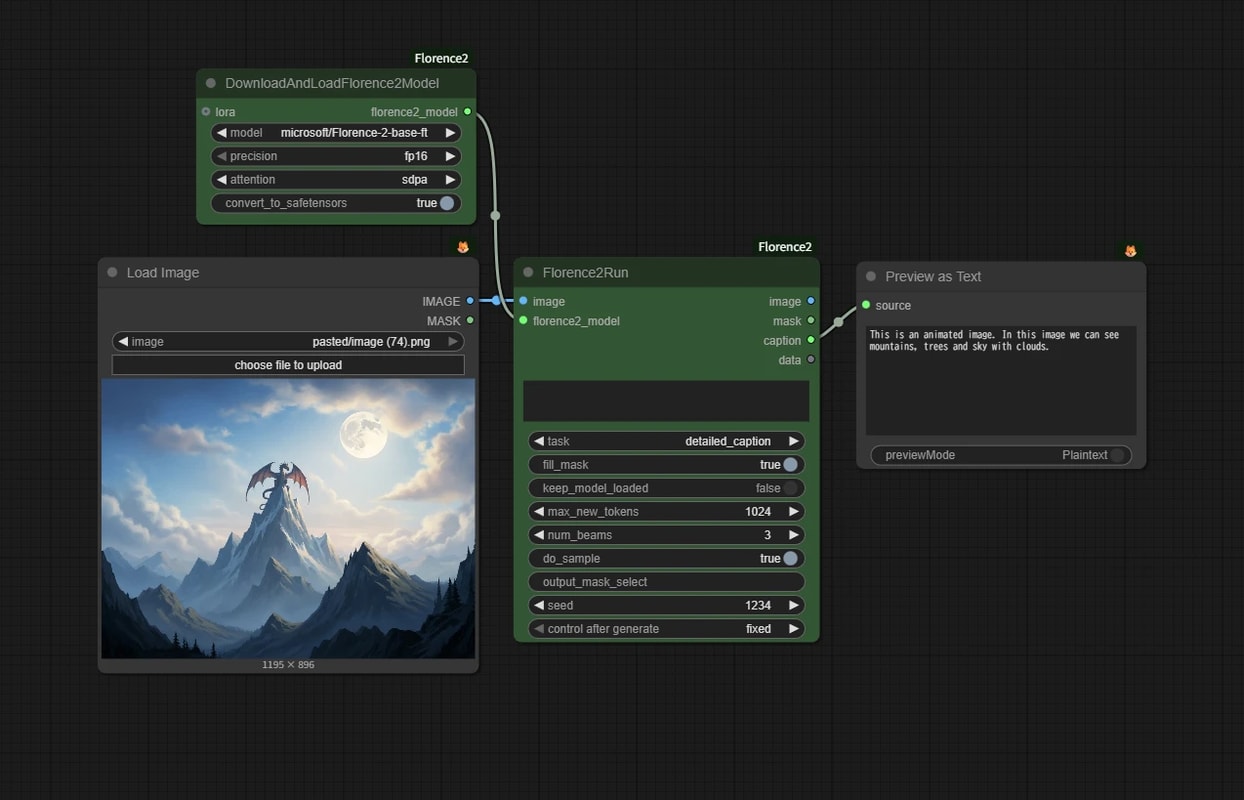
caption- Explains the outline of the image simply.
detailed caption- Explains the composition and appearance in a little more detail.
However, if the purpose is only "caption for prompts", using a caption-specific model such as JoyCaption will produce much more flexible and high-quality results.
caption_to_phrase_grounding
Outputs the position of the object in the form of a rectangle (bounding box) for each phrase of the specified caption.
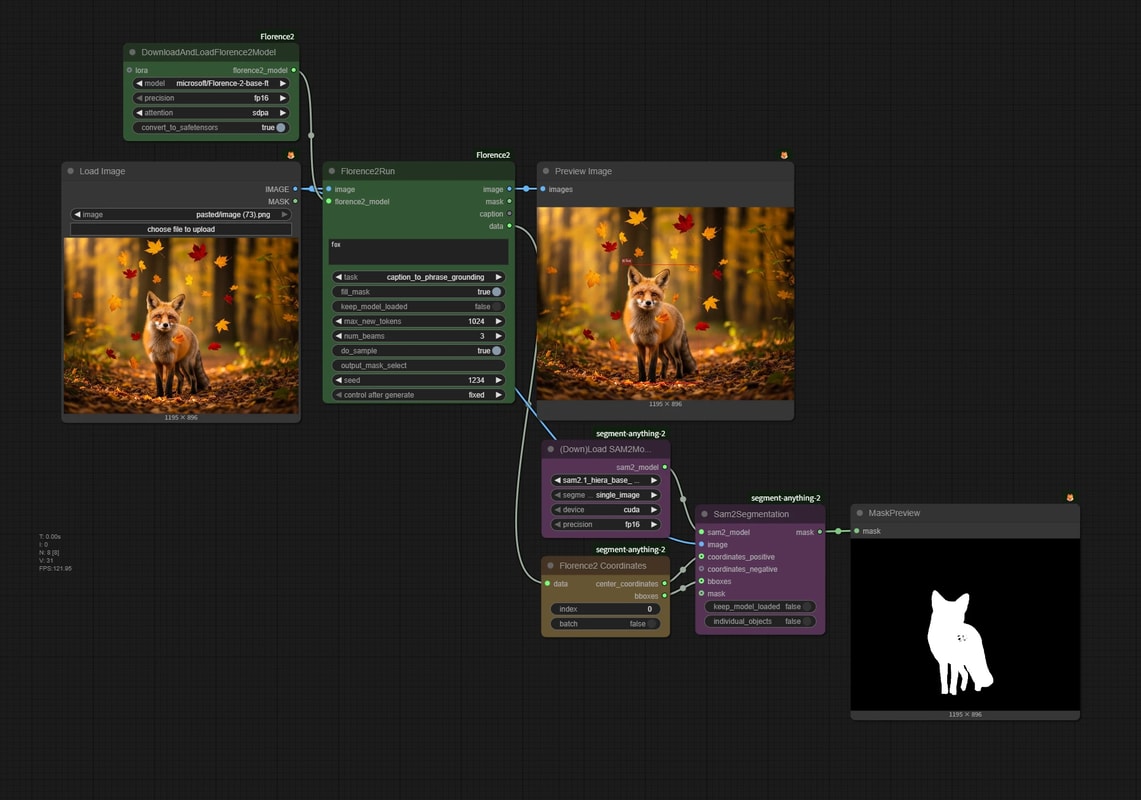
- It is characterized by being able to take the position even with slightly complex instructions such as "left tree" or "red car".
- By extracting coordinates with the 🟨
Florence2 Coordinatesnode and combining it with a segmentation model such as SAM2, you can use it to mask only specific objects.
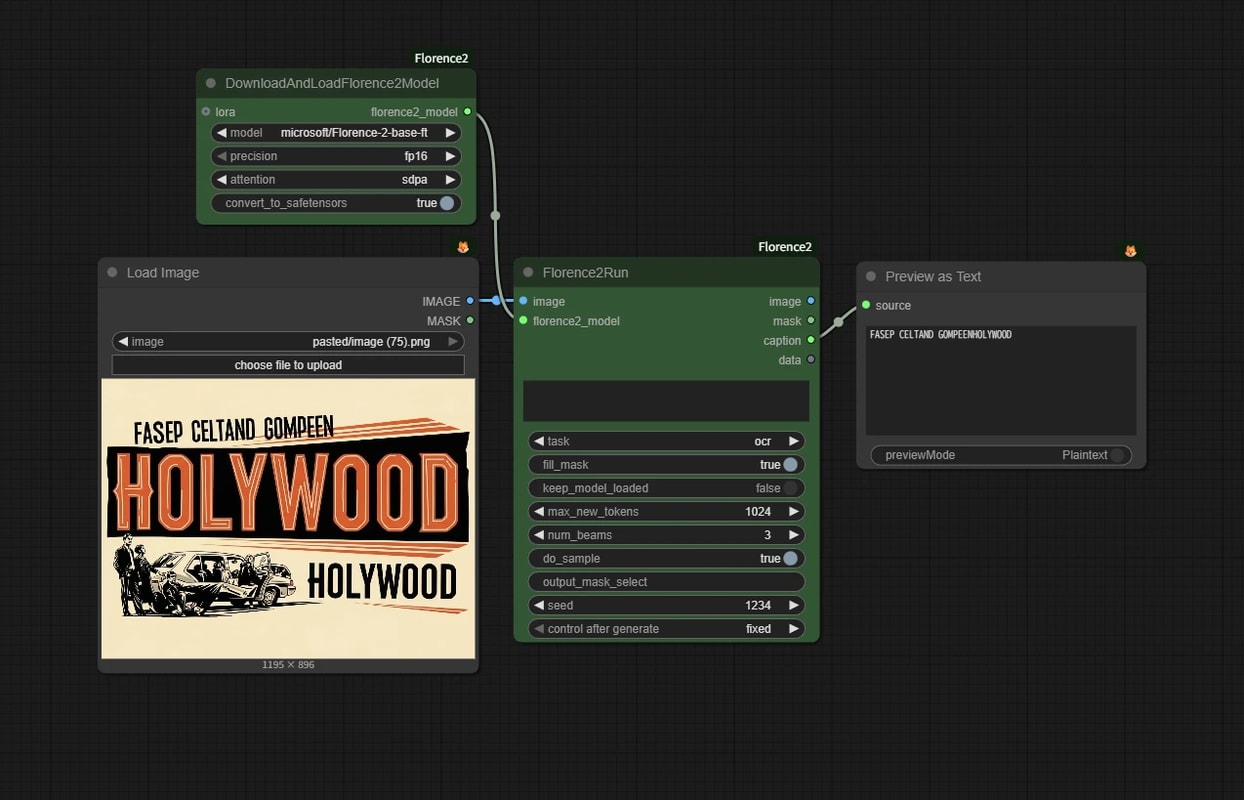
ocr
Reads characters in the image and outputs them as text.
docvqa
A task to answer questions about the image.
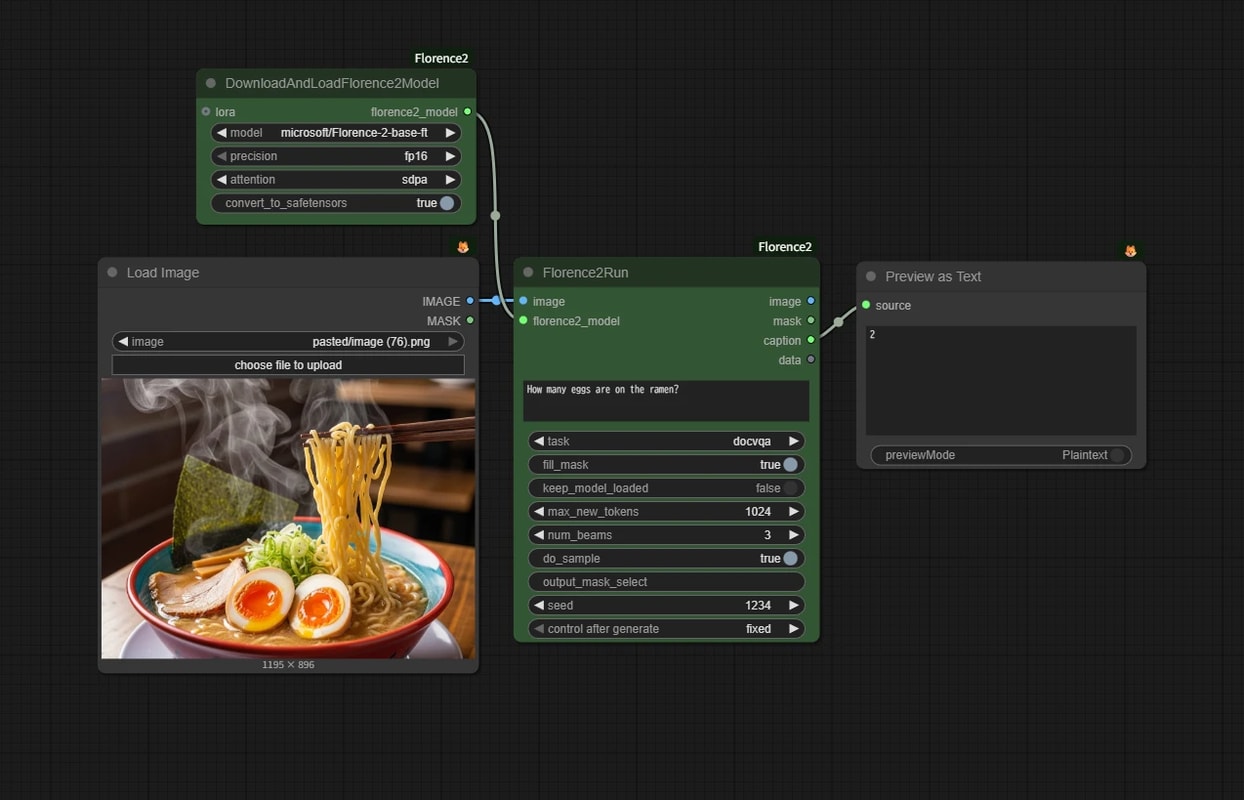
- You can ask questions like "Where is XX in this image?" or "What is the value of this table?" and receive the answer in text.
- Imagine usage similar to throwing an image to ChatGPT and asking questions.