PixelDiT
PixelDiT is a pixel diffusion model released by NVIDIA.
Many image generation models after Stable Diffusion use a mechanism called a Latent Diffusion Model.
Calculating an image pixel by pixel is expensive, so these models first compress the image into a smaller representation called a latent. This reduces computation while making it easier to handle features like shape, color, and composition.
However, when the latent is converted back into pixels, fine details such as small text and patterns can degrade.
A pixel diffusion model works directly with the image in pixel space instead of going through a latent. Because of that, VAE reconstruction loss does not occur in the same way.
That raises the obvious question: wasn't the latent there to reduce computation? PixelDiT handles this by splitting the image into patches, looking at the whole image roughly while drawing details on the pixel side.
Model Download
- diffusion_models
- text_encoders
- gemma_2_2b_it_elm_bf16.safetensors (5.23 GB)
📂ComfyUI/
└── 📂models/
    ├── 📂diffusion_models/
    │   └── pixeldit_1300m_1024px_bf16.safetensors
    └── 📂text_encoders/
        └── gemma_2_2b_it_elm_bf16.safetensors
text2image
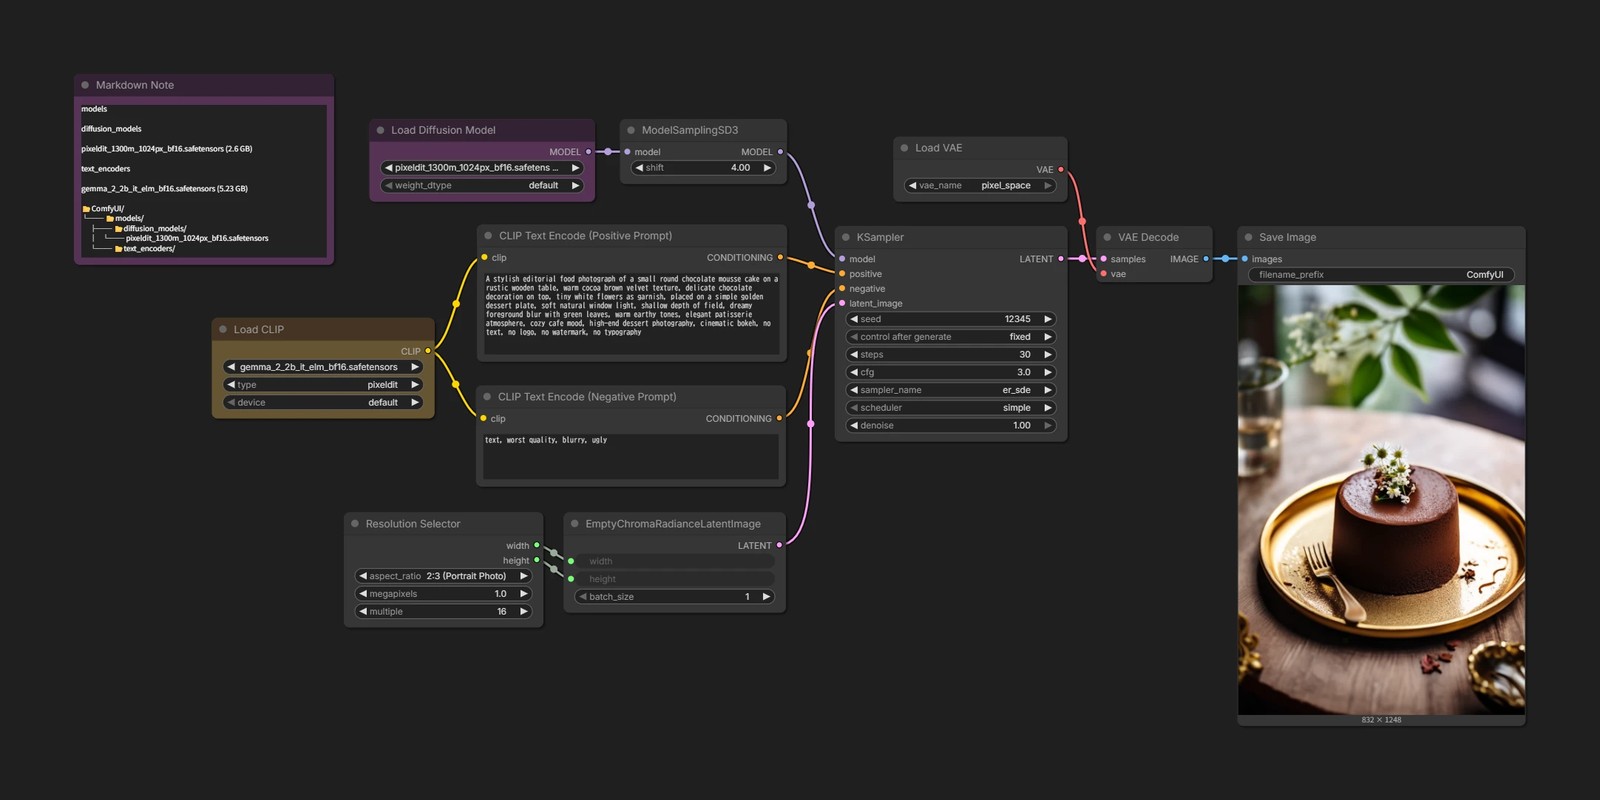
Because this is a pixel diffusion model, it does not inherently need Load VAE or VAE Decode.
In ComfyUI, however, the workflow still follows the existing format: select pixel_space in Load VAE, then connect it to VAE Decode.
It may look as if the image is being decoded with a VAE called pixel_space, but think of it as the step that gets an IMAGE output from KSampler.
PiD
PiD is PixelDiT used in place of VAE Decode.
Normally, the generated latent is passed through VAE Decode to become an image. With PiD, that latent is passed to PixelDiT instead, so restoration into an image and upscaling are handled together.
For example, Z-Image-Turbo can generate a 1024×1024 latent, then send it to PiD before VAE Decode.
With a 1024_to_4096 PiD model, the result is output as a 4096×4096 image.
In short, you can use the generation ability of an existing model while avoiding fine-detail degradation from VAE Decode.
Model Download
-
For SDXL
-
For Qwen-Image
-
For Flux.1 / Z-Image
-
For Flux.2
📂ComfyUI/
└── 📂models/
    └── 📂diffusion_models/
        ├── pid_sdxl_1024_to_4096_4step_bf16.safetensors
        ├── pid_1.5_qwenimage_1024_to_4096_4step_bf16.safetensors
        ├── pid_flux1_512_to_2048_4step_bf16.safetensors
        ├── pid_1.5_flux1_1024_to_4096_4step_bf16.safetensors
        ├── pid_flux2_512_to_2048_4step_bf16.safetensors
        └── pid_1.5_flux2_1024_to_4096_4step_bf16.safetensors
You do not need to install all of them. Place only the PiD model that matches the base model you use.
Choosing a Model
There are two points to watch when choosing a PiD model.
-
Base model type
- It needs to match the latent type used by the original model.
- Use the SDXL version for SDXL, and the Flux.1 version for Z-Image.
-
Scale
- Model names include strings such as
1024_to_4096; this indicates the scale. - It does not upscale automatically just because you choose the model. For
1024_to_4096, pass a latent / output around 1024px to PiD, then set the parameters so that PiD outputs a 4096px image. - The aspect ratio is flexible as long as the rough resolution matches.
- Model names include strings such as
Z-Image-Turbo → PiD
Let's decode a Z-Image-Turbo latent with PiD.
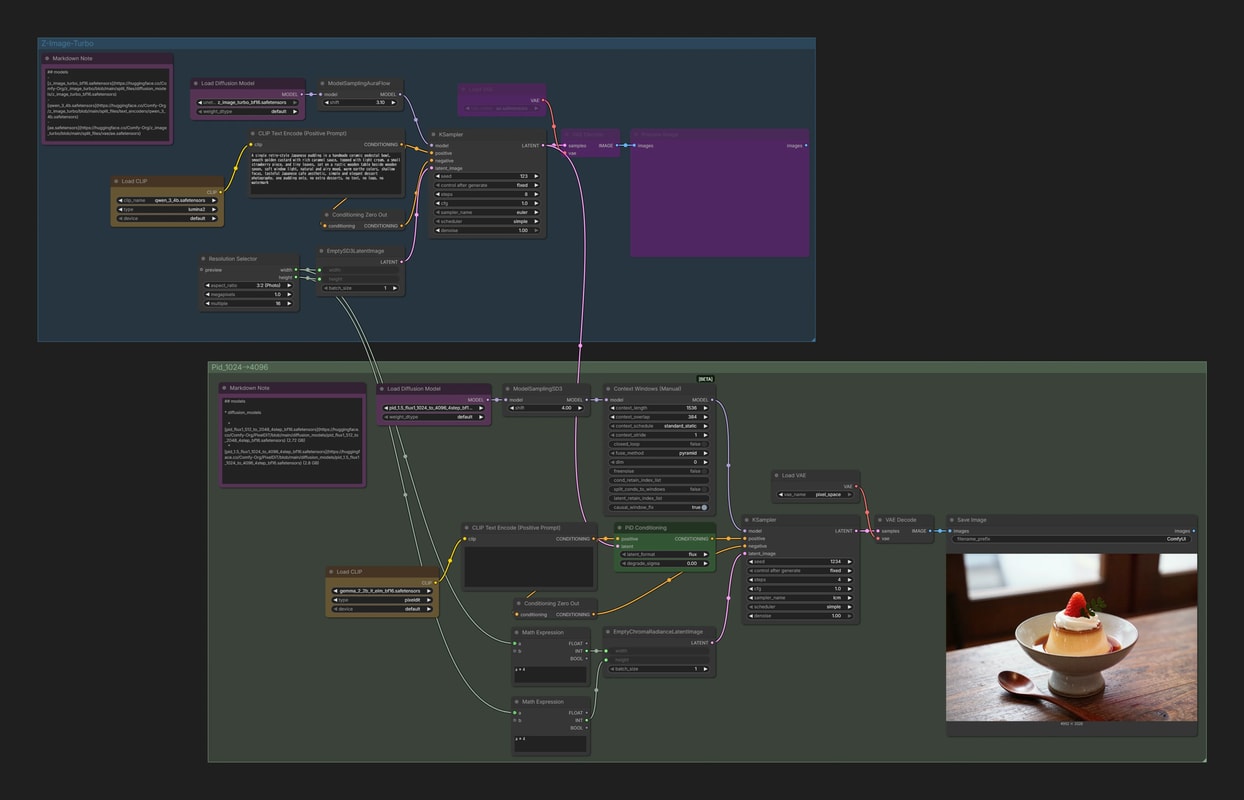
- 🟦 The upper-left part is a normal Z-Image-Turbo workflow.
- 🟩 Instead of sending the output latent to VAE Decode, connect it to PixelDiT's
PiD Conditioning.
- 🟩 Instead of sending the output latent to VAE Decode, connect it to PixelDiT's
- This example uses the
1024_to_4096model.- Z-Image-Turbo generates at around 1M pixels, and PiD is set to output at 4× that resolution.
- PiD is a 4-step distilled model, so this workflow uses
steps4 andcfg1.0. - The
Context Windows (Manual)node is for tiling. Use it when you run into OOM, or when tall / wide images come out rough.
Upscaling Any Image
What gets passed to PiD Conditioning is just a latent.
So the previous step does not need to be text2image. You can VAE Encode any image you like, pass it to PiD, and use it like an upscaler.
This example uses the PiD 1.5 model for Flux.2 with flux2-vae.safetensors.
- flux2-vae.safetensors (336 MB)
📂ComfyUI/
└── 📂models/
    └── 📂vae/
        └── flux2-vae.safetensors
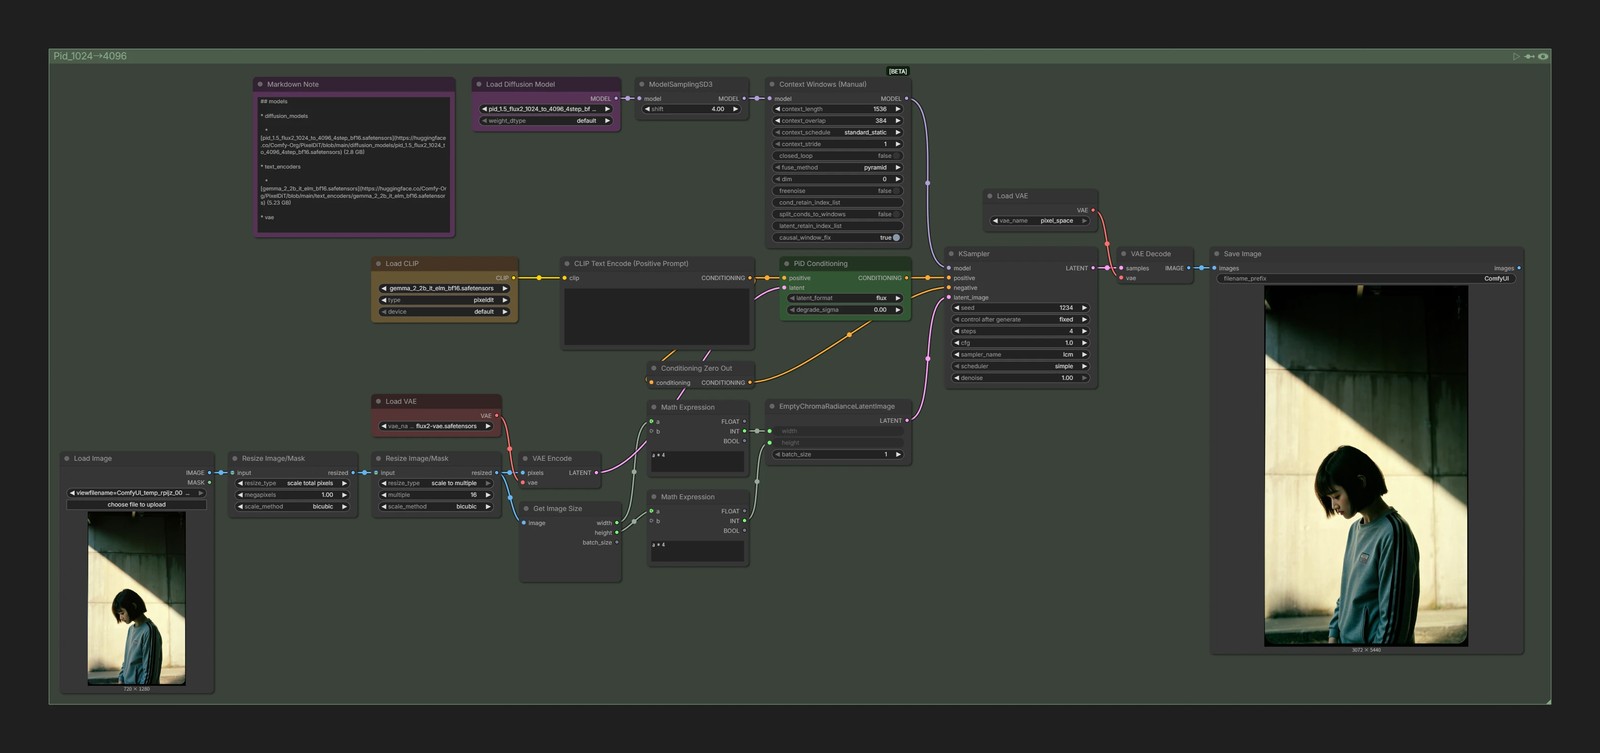
- Resize the input image to around 1M pixels, with dimensions that are multiples of 16
- Get the resized height and width, multiply them by 4, and use those values as the PiD output size
What this does is essentially redrawing, so it is more of an enhance step than a normal upscaler.
It is not well suited when faithful reproduction is required.