What is Ideogram 4.0?
Ideogram 4.0 is a 9.3B DiT-based model.
Its standout feature is JSON-format captions, which let you specify the elements in an image in quite a lot of detail.
FIBO took a similar approach, but Ideogram 4.0 is especially good at following BBOX coordinates and specified colors, which makes it a good fit for DTP-style design work like posters, logos, UI, and packaging.
The price of all that control is that it won't perform as intended unless you write prompts in its expected format, so it may not be the most casual model to use.
Model Download
- diffusion_models
- ideogram4_fp8_scaled.safetensors (9.28 GB)
- ideogram4_nvfp4_mixed.safetensors (5.49 GB)
- ideogram4_unconditional_fp8_scaled.safetensors (9.28 GB)
- ideogram4_unconditional_nvfp4_mixed.safetensors (5.49 GB)
- text_encoders
- qwen3vl_8b_fp8_scaled.safetensors (10.6 GB)
- vae
- flux2-vae.safetensors (336 MB)
📂ComfyUI/
└── 📂models/
    ├── 📂diffusion_models/
    │   ├── ideogram4_fp8_scaled.safetensors
    │   ├── ideogram4_nvfp4_mixed.safetensors
    │   ├── ideogram4_unconditional_fp8_scaled.safetensors
    │   └── ideogram4_unconditional_nvfp4_mixed.safetensors
    ├── 📂text_encoders/
    │   └── qwen3vl_8b_fp8_scaled.safetensors
    └── 📂vae/
        └── flux2-vae.safetensors
I'll explain the details later, but it loads two diffusion models, so it's quite heavy.
ComfyUI juggles memory internally, so running short on VRAM doesn't mean you can't generate at all, but it will take a very long time.
You can use nvfp4 to lighten the load, but quality drops.
The unconditional side has less effect on quality, so using fp8 for the main model and nvfp4 for the unconditional one might be a good choice.
Prompt
Plain natural-language prompts do work, but unless you follow the expected JSON schema, you won't get decent quality.
The basic form looks like this.
{
  "high_level_description": "Overall 1-2 sentence description of the image.",
  "style_description": {
    "aesthetics": "Mood and aesthetic direction.",
    "lighting": "Lighting.",
    "medium": "illustration / photograph / graphic_design, etc.",
    "art_style": "Art style for non-photographic images.",
    "color_palette": ["#FFFFFF", "#000000"]
  },
  "compositional_deconstruction": {
    "background": "Background and environment description.",
    "elements": [
      {
        "type": "obj",
        "bbox": [100, 200, 800, 700],
        "desc": "Description of an object, person, or element.",
        "color_palette": ["#FFFFFF", "#000000"]
      },
      {
        "type": "text",
        "bbox": [820, 200, 920, 800],
        "text": "HELLO",
        "desc": "Description of the text appearance.",
        "color_palette": ["#000000"]
      }
    ]
  }
}
The structure itself is simple: an overall description, style, background, and a description for each element. But you can't be writing this by hand every time.
The coordinates are especially tedious. You have to specify with BBOXes which element goes where in the image, and picturing that in your head is next to impossible.
So here are a few ways to create the prompt.
Let an LLM Handle It
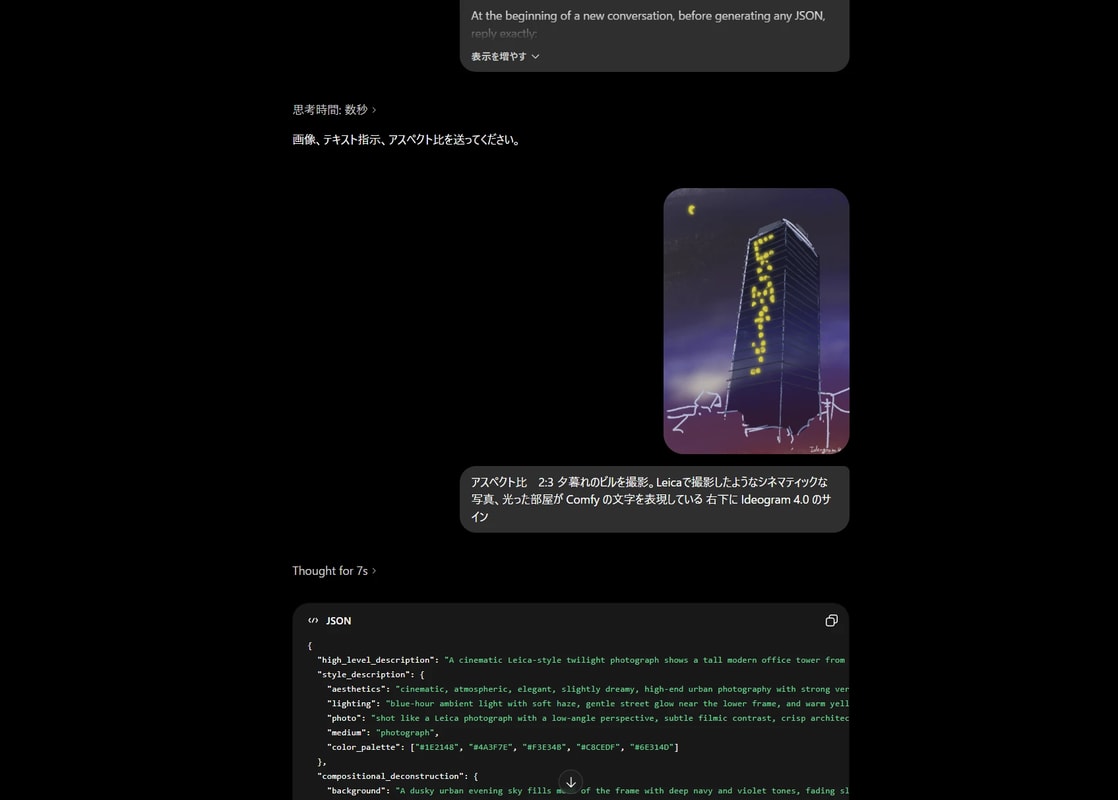
The easiest way is to pass the official Prompting Guide and a description of the image you want to an LLM, and have it convert the request into a JSON caption.
You could also hand it a reference image or a rough sketch of your own.
Local models small enough to run in ComfyUI aren't up to this, so you're better off just relying on ChatGPT, Gemini, or similar.
Use a Dedicated Prompt Builder
Another option is to use a dedicated prompt builder and create the prompt visually.
For example, ComfyUI-KJNodes includes a commonly used node called Ideogram 4 Prompt Builder KJ.
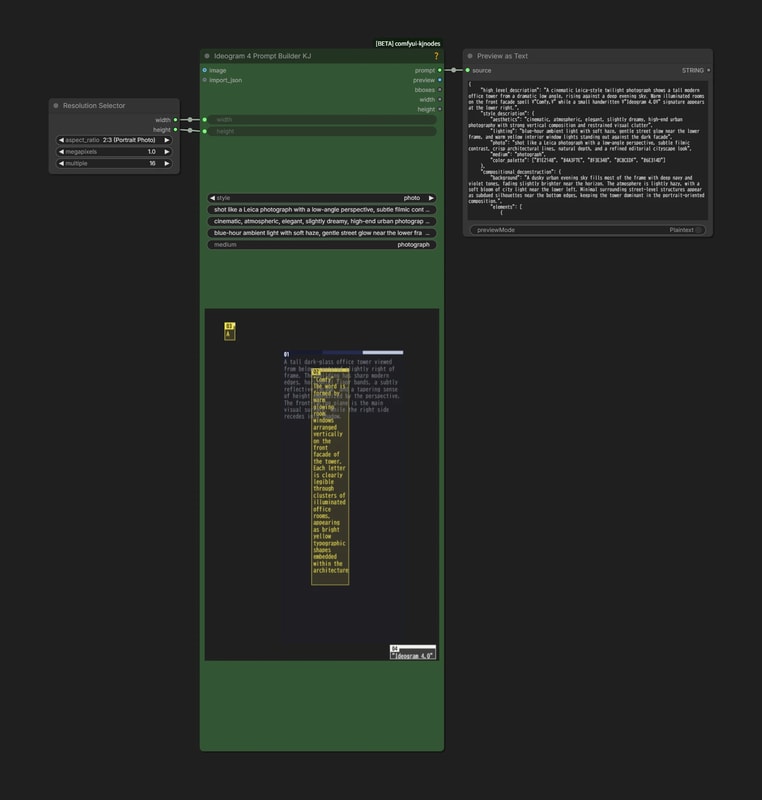
- Set the size of the image to generate, then fill in things like the background and style.
- Drag in the region area to create a BBOX, then set the prompt and color codes for what you want drawn there.
text2image
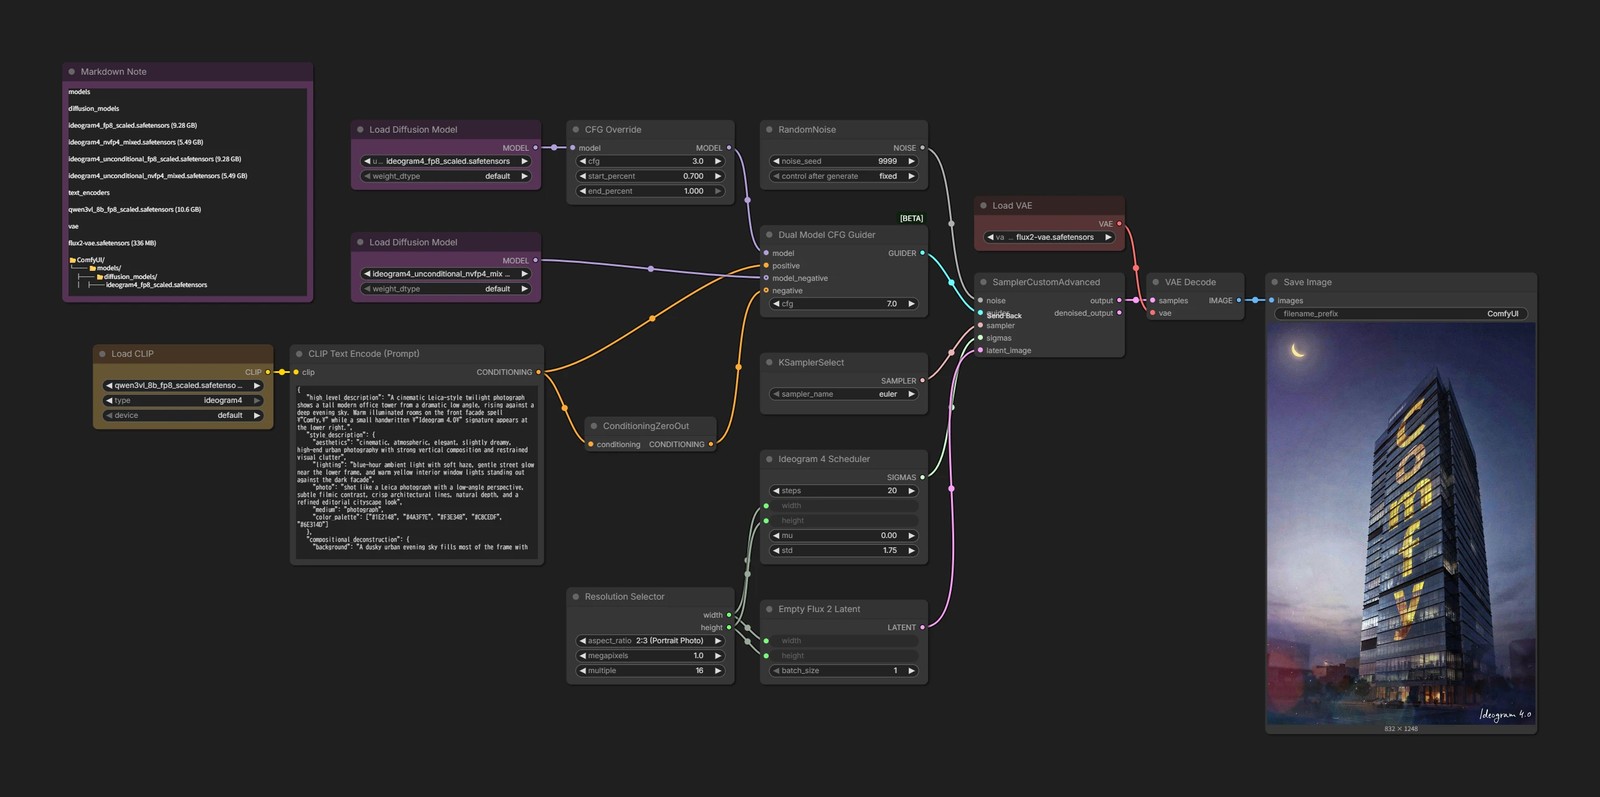
Besides the prompt, a few parts differ a little from a typical workflow, so let's just go over those.
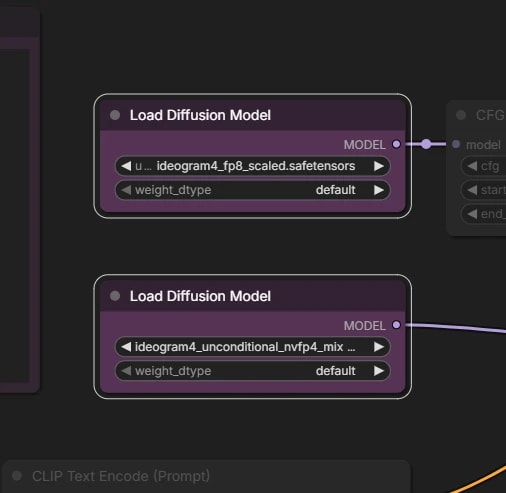
Load Diffusion Model
Ideogram 4.0 loads two diffusion models for its slightly unusual CFG.
- Normal CFG compares the result with the prompt against the result without it, and pushes the generation toward the prompt.
- Ideogram 4.0 does not pass an empty prompt to the unconditional side. Instead, it sends image-only input, without text tokens, through the unconditional model.
- You might wonder what difference that makes, but I guess it's a trick for handling the positive prompt with more finesse.
Ideogram 4 TurboTime LoRA
A LoRA released by Ostris that lets you generate in 2 to 8 steps.
Model Download
- loras
- ideogram_4_turbotime_v1.safetensors (847 MB)
📂ComfyUI/
└── 📂models/
    └── 📂loras/
        └── ideogram_4_turbotime_v1.safetensors
text2image (8 step)
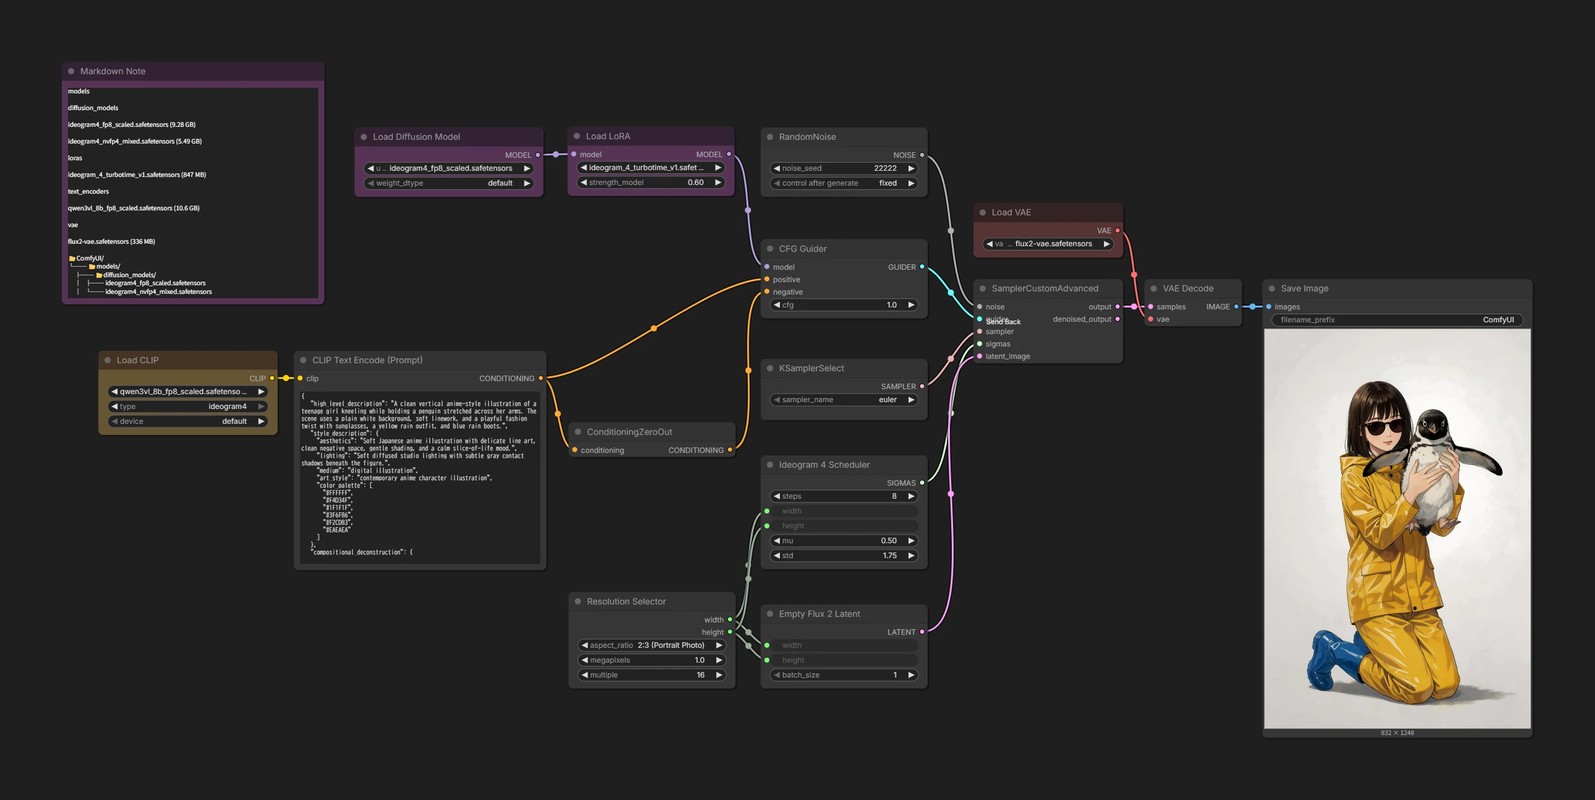
- It generates with CFG 1.0, so the unconditional model is no longer needed.
- It's billed as a 2-8 step LoRA, but with too few steps the image clearly starts to fall apart.
- For now, 8 steps is the way to go.
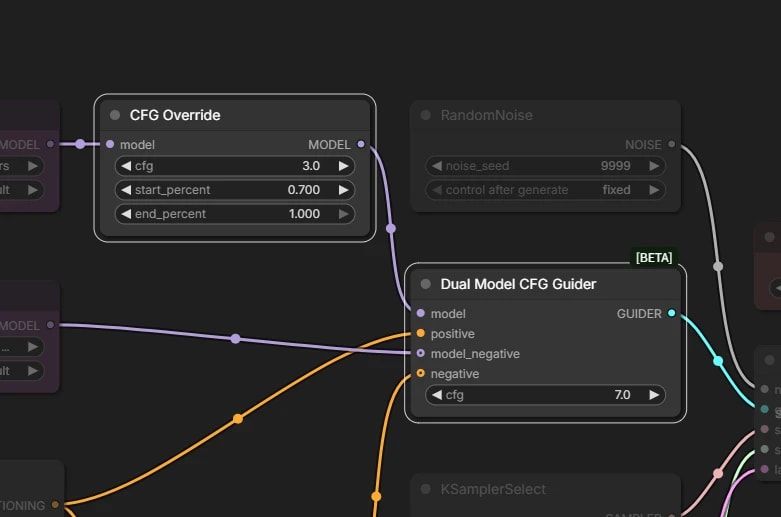
CFG
This is a small trick that's been around for ages: use a different CFG value for the first and second halves of sampling.
- In this workflow, the first half is CFG 7, and the second half is CFG 3.
- Lowering a high CFG partway through is more stable than keeping it high from start to finish.
CFG Overrideis the node used for this.- It overrides the CFG value only for the specified step range.
- In this workflow,
cfgbecomes 3 after 70% of the total steps.