What is Tag & Caption Generation?
The task of automatically adding tags and descriptions (captions) to images.
It's used for building datasets for LoRAs and fine-tuning, and for generating prompts to make images similar to a reference.
Tag Generation (Tagger)
Automatically assigns Danbooru-style tags and genre labels.
WD Family Taggers
- WD14-tagger / WD-tagger-v3 family
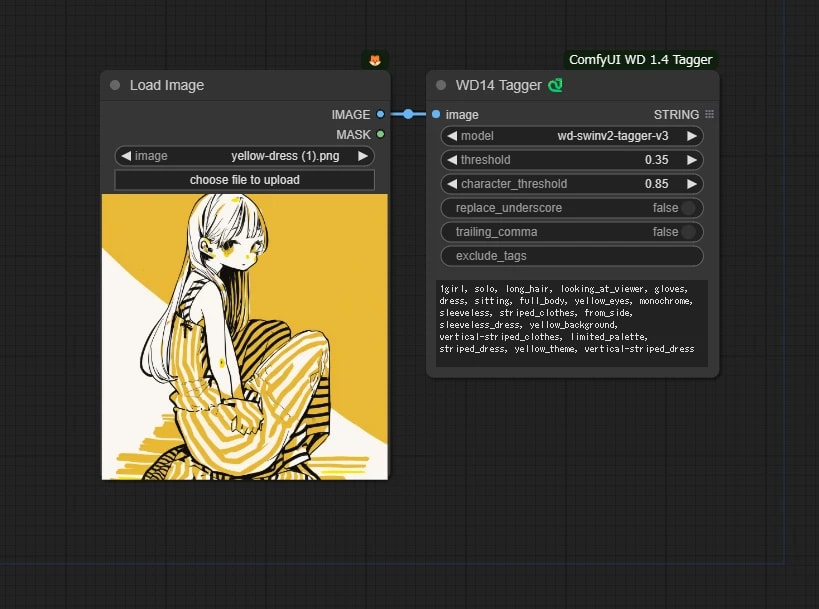
- Tagging models for illustrations and anime-style images.
- They add very fine-grained tags for things like character, hair color, clothing, expression, and composition.
JoyTagger
- Where the WD family specializes in anime, this tagger also handles more general images.
- It's made by the same author as JoyCaption (covered below), which is handy if you want your tagging and captioning tools to come from the same family.
Local Caption Generation Models
Back when LLMs that could handle images (VLMs) were rare, lots of local captioning models were proposed. moondream, the LLaVA family, InternLM-XComposer2-VL... the list goes on.
By today's standards, many of them don't hold up in terms of accuracy, stability, and cost, and few are worth setting up fresh now.
Here I'll list only the ones that are still fairly easy to use.
JoyCaption
- JoyCaption
- A lightweight model built specifically for captioning, by the same author as JoyTagger.
- Unlike general-purpose VLMs, it does only "image → description," so you don't need to fuss over prompts and can just use it.
- Best of all, it's lightweight.
Qwen-2.5 / Qwen3-VL Family
- Among lightweight local MLLMs, this series is about as close to SoTA as it gets right now.
- Besides ordinary captioning, it can handle somewhat more involved instructions like "write it in a style suited to training captions."
- If you want to run a ChatGPT-like LVLM locally, start with this one.
APIs like ChatGPT / Gemini
As with prompt generation, using closed models through an API is also a good option.
- Setup is very easy.
- Japanese captions can be handled as is.
- You can ask for post-processing together, like "Make it a slightly more technical description for LoRA training."
Setting up an MLLM is hard, and the compute costs are high too... So being able to just use one without any hassle is a real blessing.
Reasons to Use Local Models
This goes beyond LLMs, but the big reason to use local models is really whether they can handle NSFW content.
- Public APIs often blur or reject NSFW content.
- On the other hand, training datasets sometimes require "captions as they are" regardless of content.
- Even local models are often censored.
I think that's exactly why WD taggers and JoyCaption are still in demand.
If you need to run everything locally, or you're building a dataset that includes NSFW content, use these local models together.