JavaScript is unavailable, so some features (menu/search) are unavailable. Check browser or extension settings.
Segmentation
What is Segmentation?
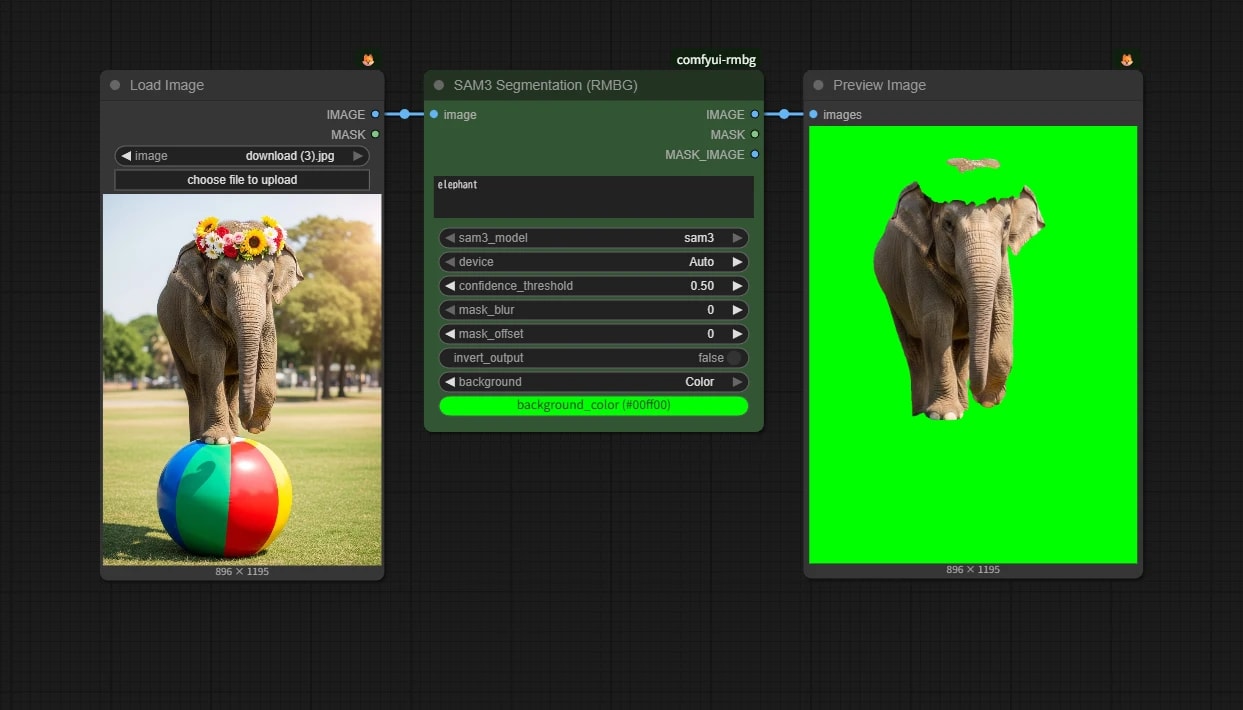
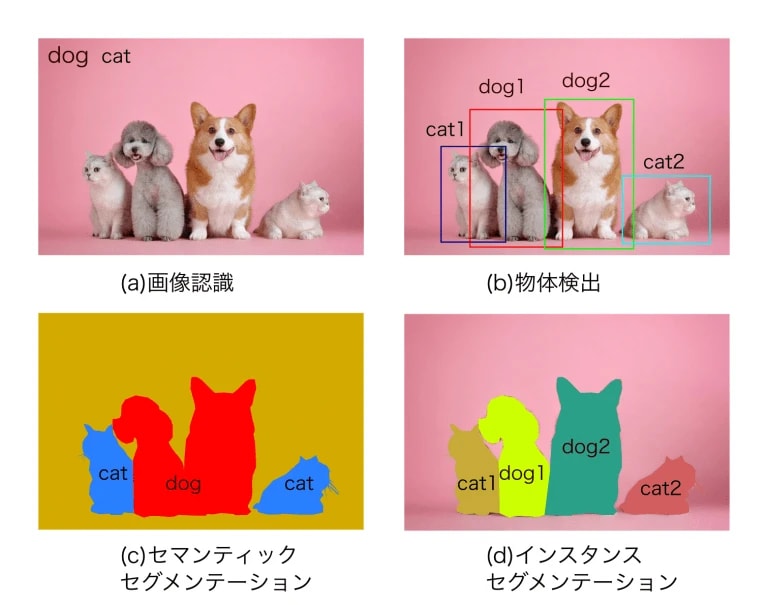
There are actually many kinds of segmentation, but in the ComfyUI context it means making a mask in the shape of an object you pick with points, a BBOX, a mask, or text.
Difference from Matting
It may sound similar to matting, but there are some big differences.
Matting
Makes a mask by deciding between just two options: "foreground" or "background"
Segmentation
The goal is to cut out (make a mask for) any object you choose
So is matting just a weaker version of segmentation? Not at all. They do different jobs in the first place.
Segmentation is closer to a classification task
Matting gives high-quality cutouts that can even represent transparency
When people say "segmentation" in ComfyUI, what they're actually using is almost always a SAM (Segment Anything) family model.
I said the goal is to cut out (make a mask for) any object, but to do that, the AI has to understand "the shape of that object" to some degree.
Say there's a fruit basket on a desk and you want to cut out an apple. If the AI doesn't know what an apple looks like, it can't tell where the apple ends. SAM is what made this possible.
Main Models
SAM
The original model released by Meta.
Just click anywhere, and it returns a mask for that region.
Adds video support. It can track the same object through a video and output masks for it.
SAM 3
You can now specify the target with text.
Before this, you had to pick the target with points or a BBOX, so making masks automatically meant pairing it with object detection.
Use Cases in ComfyUI
It comes up everywhere, from cutouts to inpainting.
The Segment Anything Playground also has lots of examples, like blurring faces or turning the background black and white. (By the way, you can recreate most of them in ComfyUI.)
sam3.json
Up through SAM 2.1, you couldn't specify objects with text, so it was often paired with object detection models like Grounding DINO or Florence2.
SAM 3 does take text, but when it comes to object detection, models better than SAM will probably keep coming out, so this combination is worth remembering.