
What is Object Detection?
Object detection is the task of finding "what's in the image (class)" and "where it is (location)."
It usually outputs a bounding box (rectangle) and a label for each object.
In ComfyUI, it's used almost entirely as the first step in making masks. Detect a dog and erase it, detect just the face and refine it... it comes up all the time.
Representative Methods
The wider field of object detection has many branches, but from a ComfyUI point of view, these are the main ones.
YOLO Family
A long-established, powerful family of models for detecting specific objects (cars, people, dogs, etc.).
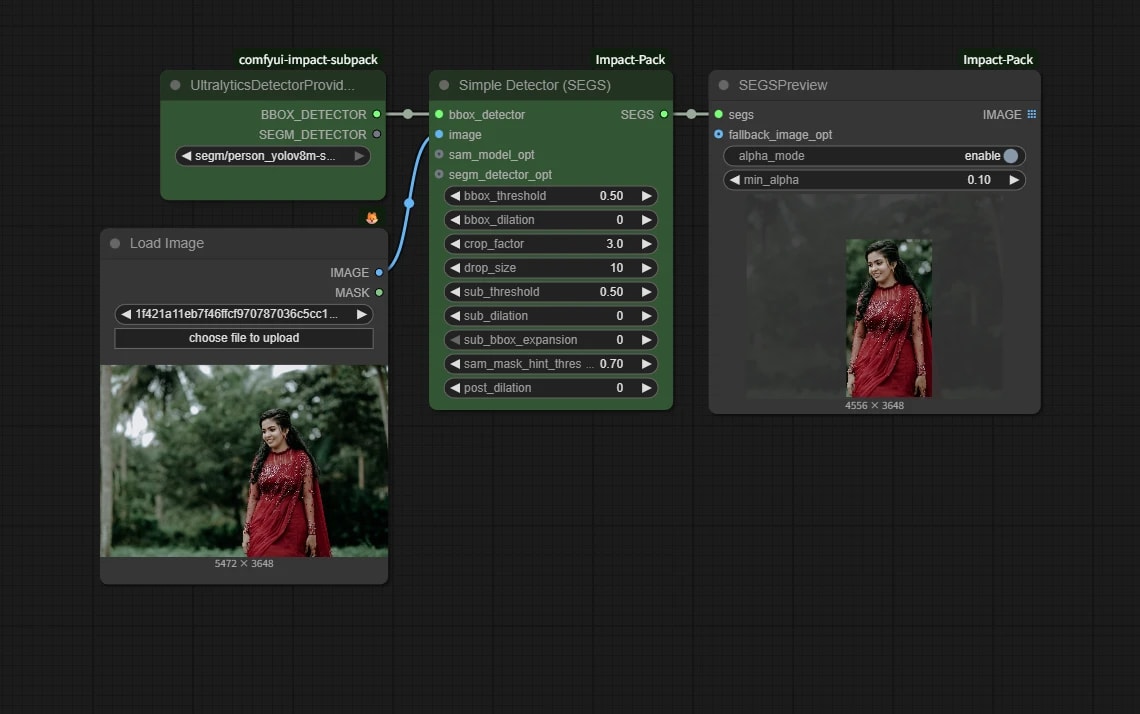
- Extremely fast, and light enough for real-time use.
- Trained in advance on a fixed set of classes like "person" or "car," and detects only from that set.
- If no model exists for what you need, you have to train one yourself.
DETR Family
Detection models that use Transformers instead of CNNs. You'll rarely use them directly in ComfyUI, but you may come across the name when reading about object detection.
Object Detection by Text
The detectors above can only find their predefined classes, so as soon as you want to detect something beyond the usual people or cars, they get awkward to use.
What matters for ComfyUI is detection where you can specify the object in text.
Grounding DINO
- Uses an image encoder + text encoder to match image features with text features.
- It can detect anything you describe in the prompt (text), such as "red car" or "traffic light."
Florence-2
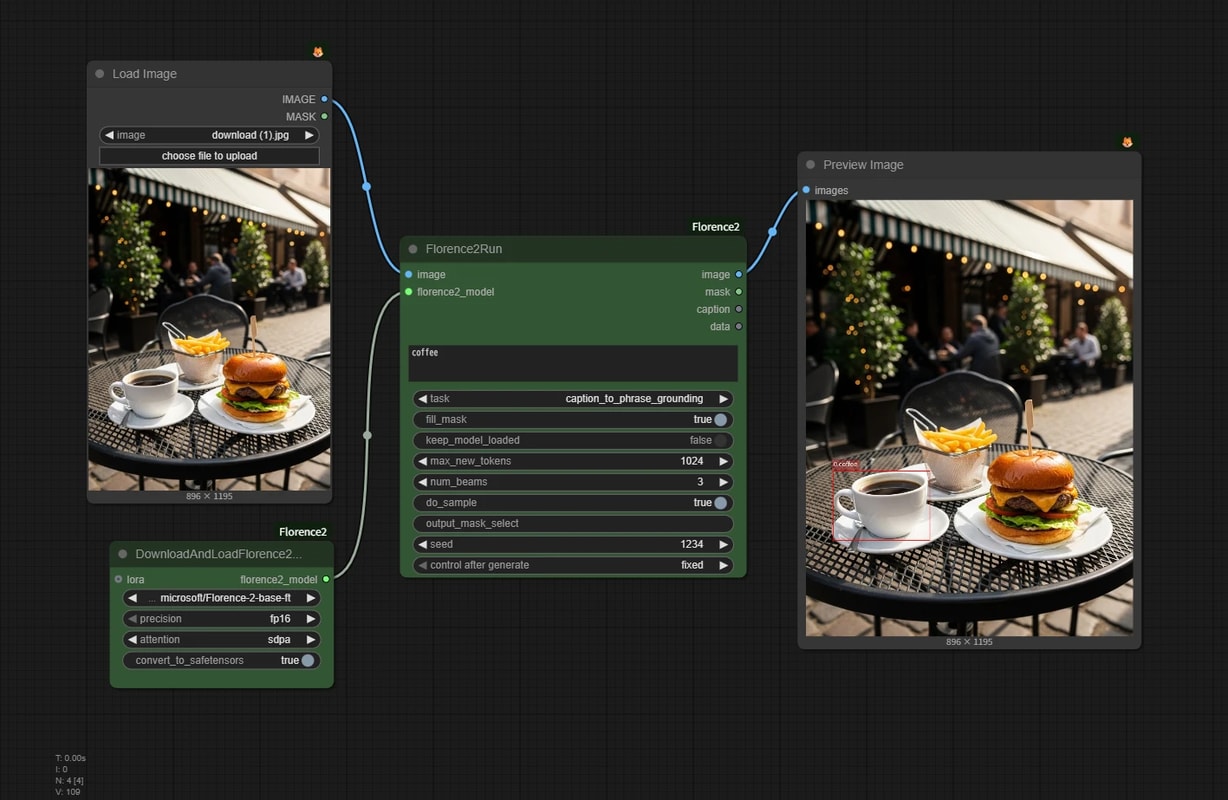
- A general-purpose VLM that looks at an image and handles many jobs in one model: captioning, object detection, segmentation, and more.
- Its structure is close to an LLM's, so its strength is that it understands more complex instructions than Grounding DINO.
Use Cases in ComfyUI (As Mask Generation)
In ComfyUI, object detection is used almost entirely as the first step in mask generation.
But all an object detection model outputs is a BBOX (rectangle).
That alone is useful for things like object removal with inpainting, but when you detect a person, for example, most of the box is background, so it's a bit wasteful as a mask.
So detection results are usually not used on their own but passed on to matting or segmentation. Let's look at those next.