What is JoyCaption?
JoyCaption is a VLM (Visual Language Model) for generating captions from images.
It can generate high-accuracy captions for a wide range of genres such as real photos, anime, and digital art. Above all, since it handles NSFW images without censoring, it is popular as a "caption-specific model" even now that higher-performance general-purpose MLLMs have appeared.
Because it is based on LLaVA-based multimodal models, it cannot be said to be lightweight compared to taggers, but it has the ease of being easy to incorporate into a local image generation pipeline as a ComfyUI node.
Custom Node
JoyCaption Node
Generates a caption from the input image.
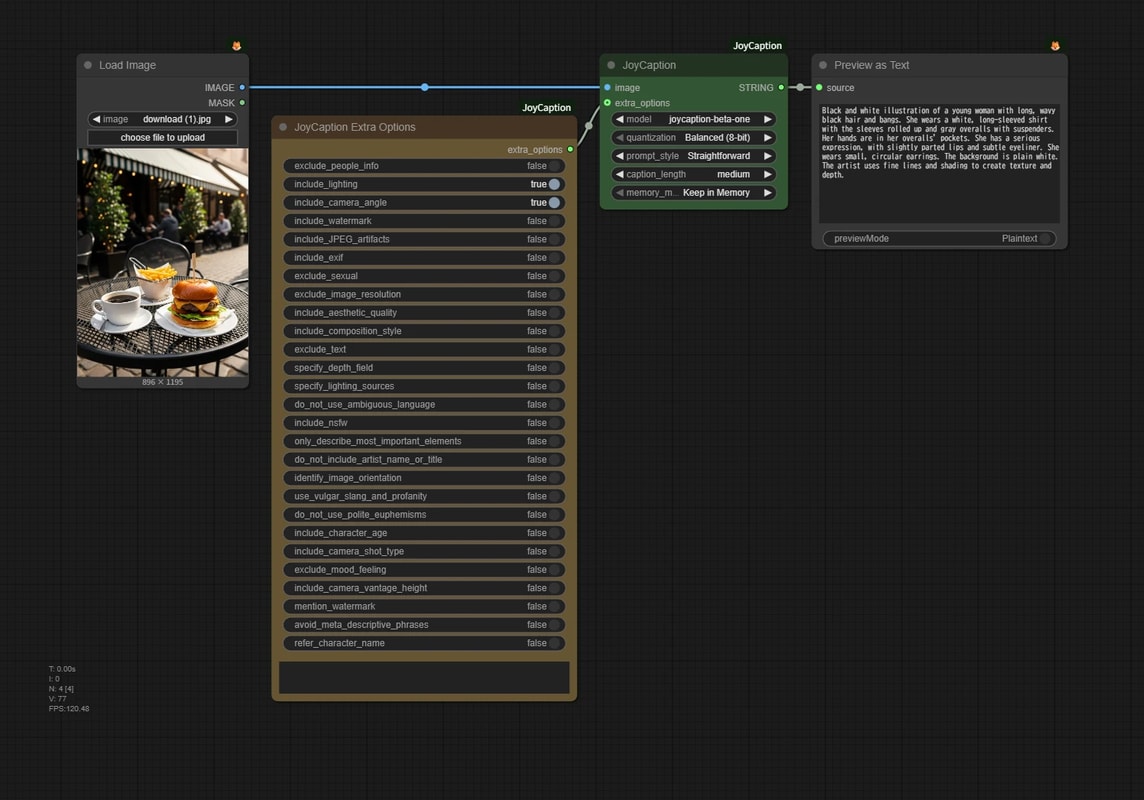
-
prompt_style- Descriptive
- Writes as formal and long prose.
- Useful when you want to keep the content of the image in detail, but tends to be redundant to use as a prompt as is.
- Straightforward
- Writes in a concise and objective style.
- A style that is easy to divert as is for prompts and captions for LoRA.
- Stable Diffusion Prompt
- Writes in a prompt format for Stable Diffusion.
- Danbooru tag list
- Lists tags in Danbooru tag format (e.g.,
1girl,blue_hair).
- Lists tags in Danbooru tag format (e.g.,
- Descriptive
-
caption_length- Specifies the volume of the caption to output (short/long).
-
Extra Options- Sets additional instructions to guide caption generation.
- For example, you can specify a policy such as "write in detail / do not touch much" about camera angle, image quality/resolution, NSFW elements, etc.