3D Generation
3D generation is exactly what it sounds like: creating a 3D model from a text prompt or a reference image.
It would be nice if a model simply emerged from noise, the way it does in text2image. But just as video adds a dimension along the time axis, 3D generation adds a spatial dimension, so it isn't that easy.
To be upfront: 3D generation isn't yet good enough for professional use. Still, the technology for turning images into models, and even into worlds you can walk around in, is steadily improving.
Let's trace a bit of how this fast-moving technology has developed.
Note: Both the timeline and the technical connections here are pretty rough. Take it as a loose overview.
Multi-View Generation
Techniques like NeRF, which build 3D spaces and models from images, already existed. But to build 3D with NeRF, you need images of the same object from many different viewpoints.
That need is what gave rise to multi-view generation.
Zero-1-to-3
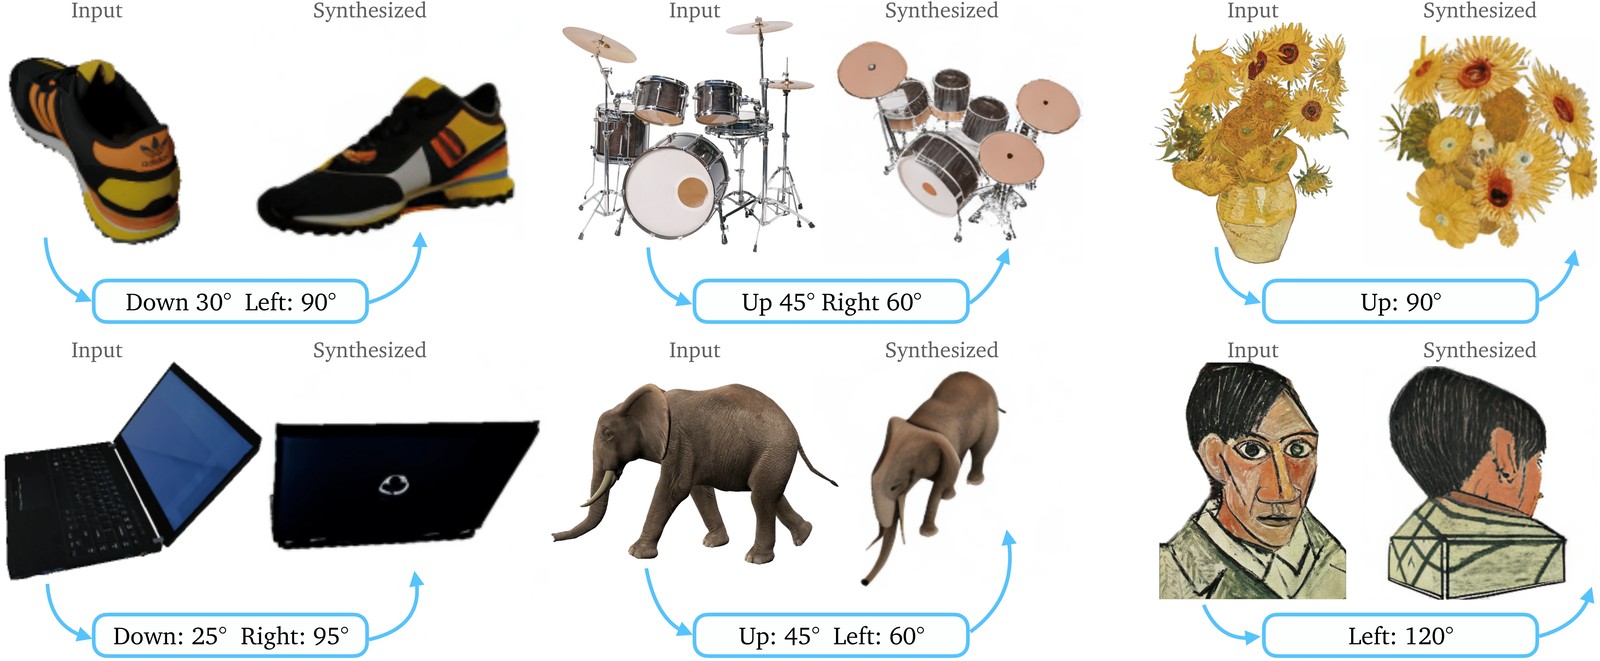
One of the earliest diffusion-based multi-view models. It generates an image from a new viewpoint by changing the camera angle of the input image.
At the time I thought it looked handy even outside of 3D generation, but the hardware requirements were too high for me to use it. These days you can do something similar easily with instruction-based image editing.
Zero123++
Zero-1-to-3 was used as "make one image of the input from another angle → change the angle and run it again and again," whereas Zero123++ generates multiple viewpoints simultaneously.
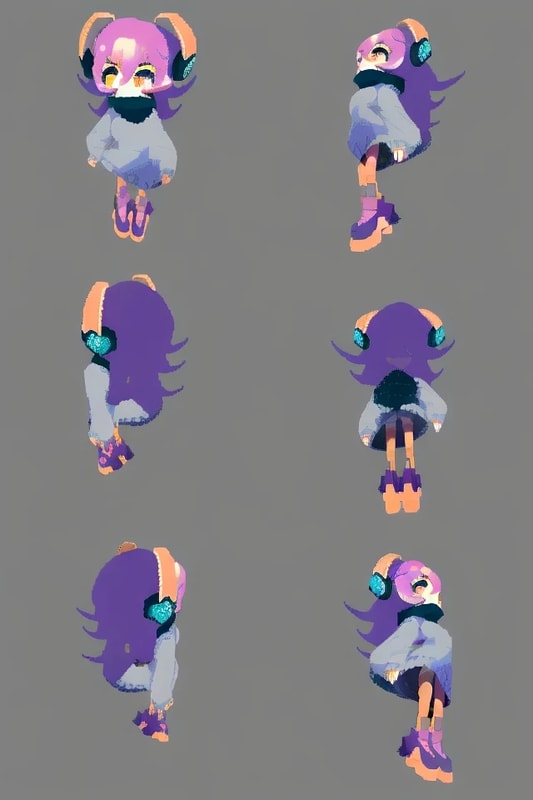
It was already known that when a diffusion model generates several images as a batch (cf. Batch & Video), the images come out somewhat consistent with each other.
3D generation needs images from every direction right from the start. You could say Zero123++ takes advantage of that property and leans toward "making a set of multi-views that are as consistent as possible in a single generation."
Emergence of Video Generation Models
A little later, models capable of video generation began to appear.
This led to an idea. Instead of treating multi-view generation as "a kind of image editing," why not think of it like this?
A video shot while circling around the target object = Very finely sliced multi-view
Stable Video 3D
An image2model model based on Stable Video Diffusion.
- Input one still image
- Generate a 360-degree video of the object turning all the way around
- Treat each frame as an image from a different viewpoint and reconstruct 3D from them
Applying video generation models to 3D model generation is still an active approach today.
Today's video generation models are far more capable than they were back then, so they can produce detailed 360-degree turnaround videos even without dedicated fine-tuning.
Models Aiming Directly for image→3D Model
Up to this point, everything assumed a "two-stage" setup:
- First, gather multi-views (or a turnaround video)
- Then, turn them into 3D with a separate method
Going a step further, models are now appearing that tackle this head-on:
Input an image (or text), and get a 3D model directly
Hunyuan3D-2.1
Hunyuan3D-2.1 is a large-scale model for creating 3D assets from images or text.
- A first stage that produces only the "shape" (a rough 3D form)
- A second stage that applies a high-resolution appearance, including PBR textures
It works in these two stages.
SAM 3D Objects
SAM 3D Objects reconstructs 3D objects from a single real photo.
- On the 2D side, it uses SAM-style segmentation to cleanly cut out the target object
- Using the cut-out region as a guide, it estimates the 3D shape and texture, filling in hidden parts along the way
That's the overall flow.
The technology inside is completely different, but both are trying to solve "image → 3D model" head-on.
World Models
So far, we've talked about turning a single object into a 3D model. Meanwhile, there are also efforts to build entire worlds from photos.
"World model" here doesn't mean a world model in the sense of predicting physics. It simply means a model that builds a 3D world (scene).
360-degree Panorama Generation
It starts with 360-degree panorama generation.
Examples include tools from Latent Labs and HunyuanWorld-1.0.
- Map the input image onto a panoramic sphere
- Fill in the directions it doesn't show with outpainting
It's a simple idea that gives you something that "at least looks filled in all 360 degrees."
At this stage it isn't really 3D yet, but by adding depth maps and mesh reconstruction on top, these approaches aim to build a 3D space with real depth.
HunyuanWorld-Mirror
HunyuanWorld-Mirror gets closer to the real goal: a world you can actually walk around in.
- It's built from components that take an image (or video) as input and estimate camera information, depth, and a 3D representation (such as 3D Gaussians) all together.